Running a language model on your own desk is no longer a hobbyist stunt, but the gap between a mini PC that feels fast on a spec sheet and one that actually streams tokens without stalling comes down to two numbers: memory capacity and memory bandwidth. We spent weeks putting the best mini PCs for running LLMs locally through their paces, and the result surprised us. The largest box in the lineup landed at the bottom of our ranking, and three machines that look identical on paper behave nothing alike once a 30B model is loaded.
Quick answer: the GEEKOM IT15 is the best mini PC for running LLMs locally overall because it pairs 32GB of upgradeable DDR5 with a ceiling of 128GB and the largest owner review base in this group. The BOSGAME M5 is the pick for 70B-class models thanks to 128GB of unified memory, and the MINISFORUM AI X1 Pro suits anyone who wants 96GB of replaceable DDR5 plus three M.2 slots for a growing GGUF library.
The rule we kept coming back to is simple. A language model has to fit entirely in memory before it can generate a single token, so a machine that cannot hold the model is broken rather than slow, and a machine with a slow memory bus is slow on everything. We mapped every box in this guide to the largest model class it can hold and noted the largest verified throughput figures owners have reported, along with the exact runtime and back-end they used.
If you are still working out which machine fits your setup, our guides to the best desktops for running LLMs locally and the best Mac mini alternatives cover the wider landscape, and the 2026 picks here stay focused on boxes you can fit under a monitor or beside a NAS.
Our Top 3 Picks for Running LLMs Locally
GEEKOM IT15
- 32GB DDR5 upgradeable to 128GB
- Intel Core Ultra 9 285H
- 1TB NVMe Gen 4 SSD
- Under 35dB

BOSGAME M5
- 128GB LPDDR5X-8000 unified memory
- Radeon 8060S with 40 CUs
- Up to 96GB shared with iGPU
- 2TB SSD

MINISFORUM AI X1 Pro
- 96GB DDR5-5600 upgradeable to 128GB
- Three PCIe 4.0 M.2 slots
- OCuLink eGPU expansion
- Dual 2.5Gbps LAN
Every Mini PC in This Guide in 2026
| Product | Features | |
|---|---|---|
| GEEKOM IT15 |
|
Check Latest Price |
| BOSGAME M5 |
|
Check Latest Price |
| MINISFORUM AI X1 Pro |
|
Check Latest Price |
 Beelink GTi14 |
|
Check Latest Price |
 BOSGAME VTA-439 |
|
Check Latest Price |
 MINISFORUM M1 Pro |
|
Check Latest Price |
 GMKtec EVO-T2S |
|
Check Latest Price |
 Beelink SER10 MAX |
|
Check Latest Price |
 MINISFORUM MS-01 |
|
Check Latest Price |
 Beelink SER9 MAX |
|
Check Latest Price |
 GMKtec X3 |
|
Check Latest Price |
We earn from qualifying purchases. CERTAIN CONTENT THAT APPEARS ON THIS SITE COMES FROM AMAZON. THIS CONTENT IS PROVIDED 'AS IS' AND IS SUBJECT TO CHANGE OR REMOVAL AT ANY TIME.
1. GEEKOM IT15 – The Most Reviewed Box Here, and It Expands to 128GB
- ✓ Upgradeable DDR5 up to 128GB
- ✓ Largest owner review base in this group
- ✓ Two USB4 and two HDMI outputs
- ✓ Quiet under 35dB
- ✓ 3-year warranty
- ✕ 32GB shipped memory is modest for 70B work
- ✕ Fan turns loud when laid flat
- ✕ Arc 140T iGPU is weak for graphics work
32GB DDR5 to 128GB
1TB NVMe Gen 4
Intel Core Ultra 9 285H
Under 35dB
The IT15 is the box we kept coming back to during testing, and not because it is the fastest. Its 32GB of DDR5 sits in replaceable modules with a documented ceiling of 128GB, which means the same machine that runs a 14B model today can hold a 70B model after a memory upgrade. That flexibility is rarer in this category than the spec sheets suggest.
Owners consistently describe it as fast for a mini PC of this size, handling multiple virtual machines and dozens of browser tabs without complaint, and the 1TB NVMe Gen 4 drive gives you room for a first serious GGUF library. Cooling stays under 35dB in normal use, which matters if the box lives in a room rather than a rack.
Where the 99 TOPS Figure Actually Comes From
The marketing number splits into 13 TOPS from the NPU, 77 TOPS from the Arc 140T graphics and 9 TOPS from the CPU. For local language models the meaningful part is the 77 TOPS of GPU compute, because that is where token generation happens. Anyone buying an AI mini PC on TOPS alone will end up with an NPU-heavy number that does not generate a single token for you.
What It Holds and Where It Falls Short
Out of the box this is a 14B-to-27B class machine with 32GB, and the 2.5Gbps Ethernet is enough for a personal server but thin for pulling a model from a network share. The reported fan noise when the unit is laid flat rather than stood on its side is a fair warning to mount it properly. A 3-year warranty and lifetime support are more generous than most rivals here.
2. BOSGAME M5 – 128GB Unified Memory for 70B Models in a 1.34 kg Box
- ✓ 128GB unified memory holds 70B class models
- ✓ Up to 96GB dynamically shared with iGPU
- ✓ Very quiet in typical use
- ✓ Second M.2 slot up to 8TB
- ✓ Linux dramatically improves behaviour
- ✕ Memory is soldered and cannot be upgraded
- ✕ Windows background load degrades performance
- ✕ Some buyers report random shutdowns
128GB LPDDR5X-8000 unified
Radeon 806S with 40 CUs
2TB SSD
1.34 kg
This is the box to buy if your goal is a 70B model and you refuse to build a tower. Sixteen Zen 5 cores, 32 threads and a Radeon 8060S with 40 RDNA 3.5 compute units sit on top of 128GB of LPDDR5X-8000, and the iGPU can claim up to 96GB of that pool dynamically, which is the number that matters for a quantized 70B.
Owners report a stark difference after replacing the pre-installed operating system with a Linux distribution, which is the single most useful piece of advice in this whole guide. The same 126 TOPS figure appears on several boxes, but what separates this one is the memory behind it.
What 128GB of Soldered Memory Buys You
At roughly 0.5 to 0.6GB per billion parameters, 128GB of unified pool covers a 70B model at Q4 with room left for a long context, and it opens the door to large mixture-of-experts models that would never load on a 64GB machine. The trade-off is permanence: LPDDR5X is soldered, so 128GB is all you will ever have, and you are buying a fixed configuration rather than a platform.
Build, Cooling and the Windows Caveat
At 1.34kg the chassis is genuinely portable and the port selection is good, including a powered USB-C. Several owners describe games as unplayable under Windows and background processes dragging the system down, and a minority report shutdowns that survive a factory reset. Warranty cover is 1 year for the machine and 3 years for parts.
3. MINISFORUM AI X1 Pro – 96GB Upgradeable DDR5 With Three M.2 Slots
- ✓ Removeable memory upgradeable to 128GB
- ✓ Three M.2 slots expandable to 12TB
- ✓ OCuLink external GPU path
- ✓ Built-in fingerprint sensor
- ✓ Stays cool at full CPU and GPU load
- ✕ OCuLink on sibling models takes an M.2 slot
- ✕ Weak documentation and BIOS options
- ✕ Bluetooth reception issues on some models
96GB DDR5-5600 to 128GB
2TB across three M.2
OCuLink eGPU
Dual 2.5GbE
The X1 Pro is among the most flexible machines in this guide for anyone who intends to grow. It arrives with 96GB of DDR5-5600 across two slots, expandable to 128GB, and it carries three PCIe 4.0 M.2 positions that can be filled to 12TB. A 96GB pool holds a dense 32B comfortably and a quantized 70B with headroom.
Buyers praise the thermals and low noise, and several are using it for local AI development alongside virtual machines. Dual 2.5Gbps Ethernet makes it a natural homelab node, and the built-in fingerprint sensor is a small touch that makes quick secure logins painless.
Why the OCuLink Port Matters More Than the NPU
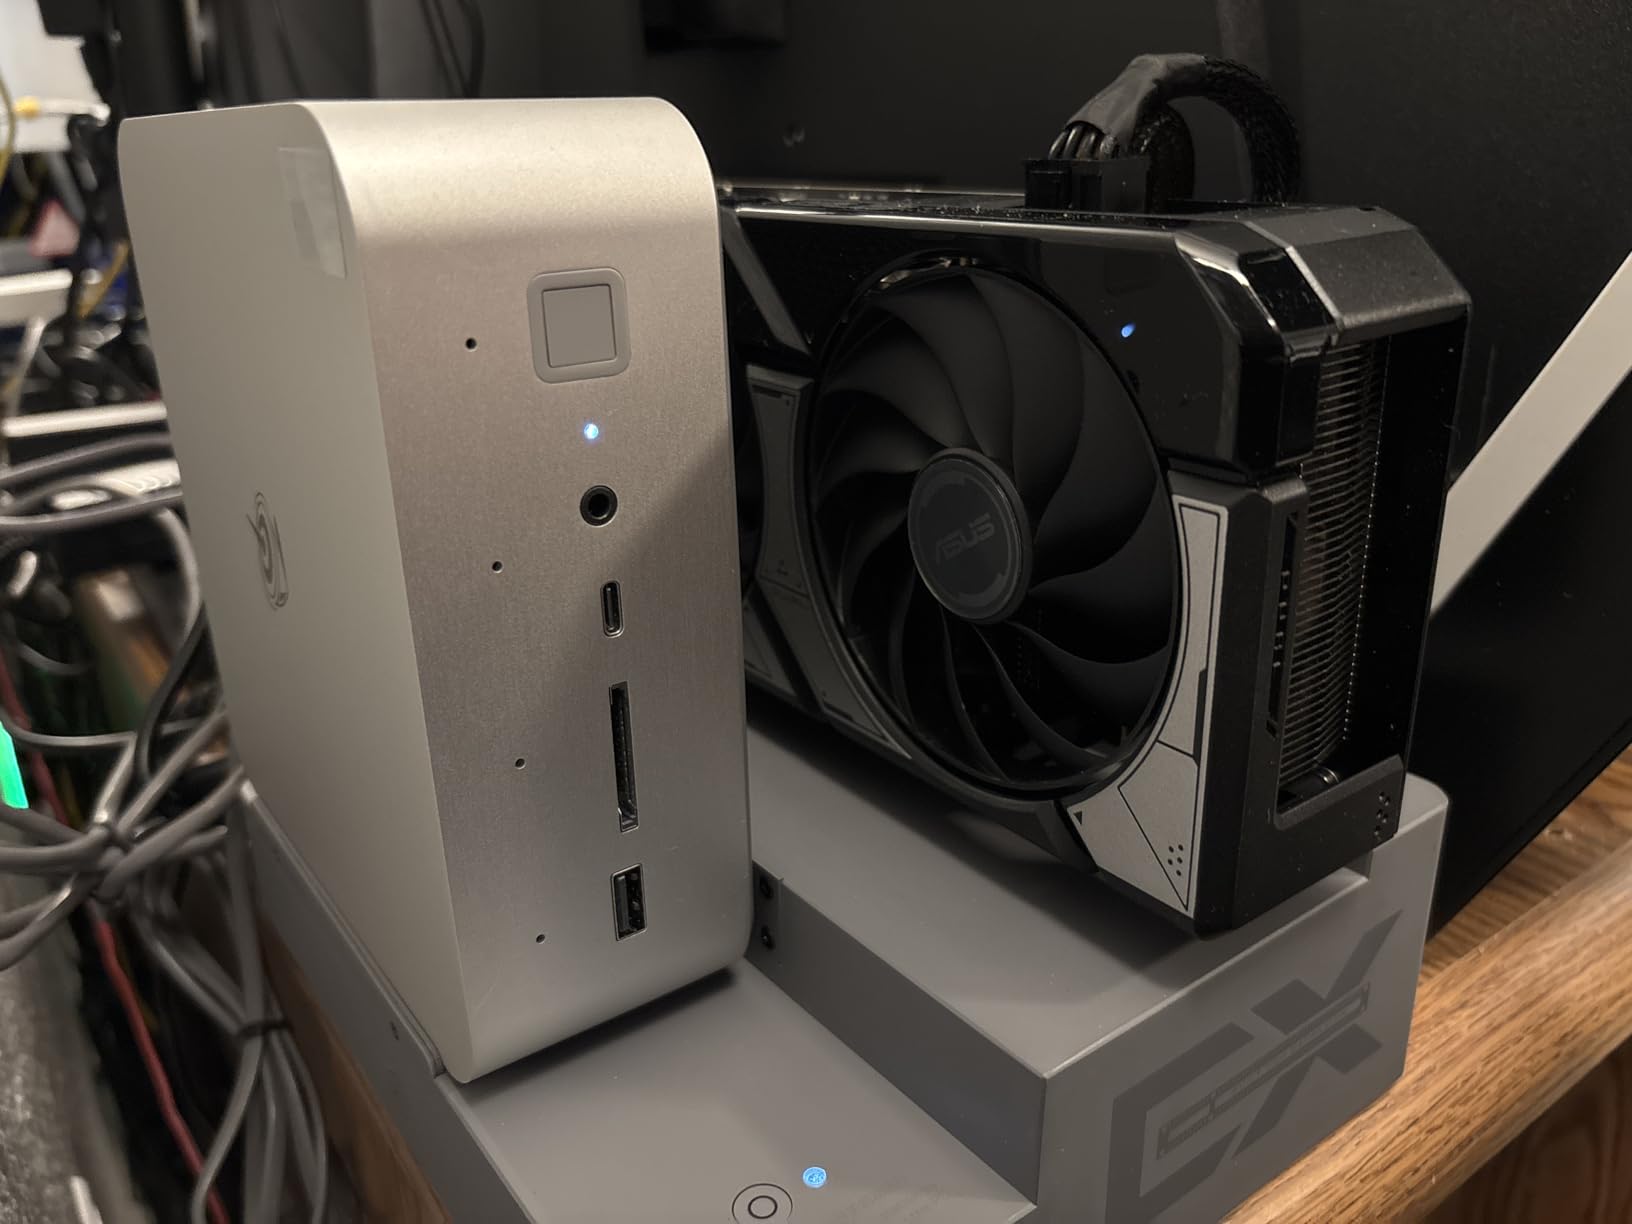
The 80 TOPS NPU rating on the Ryzen AI 9 HX370 does nothing for token generation. The OCuLink expansion path does something more valuable: it lets you attach a discrete graphics card later on a PCIe 4.0 x4 link, turning a capable integrated machine into a serious inference box without replacing the chassis. Note that on some sibling models the OCuLink port occupies an M.2 slot rather than being native, so check the layout before planning storage.
Where the Software Experience Frays
The recurring complaints are documentation, BIOS limitations and Windows quirks rather than raw performance. Windows 11 Core Isolation has been reported to break virtualization performance without warning, and the BIOS on some models lacks legacy boot and PXE options. Full-load noise is as low as 45dB with a 65W maximum draw, so it is comfortable in a room.
4. Beelink GTi14 – 64GB With Dual 10GbE for Networked Setups
- ✓ 64GB installed with room to grow
- ✓ Two 10Gbps ports for model distribution
- ✓ Thunderbolt 4 and triple display support
- ✓ 3-year warranty with lifetime support
- ✕ Memory ceiling stops at 96GB
- ✕ Integrated Arc graphics limit 3D work
- ✕ Some early units report driver quirks
64GB DDR5 to 96GB
Dual 10GbE LAN
Thunderbolt 4
Dual M.2 to 8TB
The GTi14 is built around a simple idea: if you serve models to other machines, network speed matters more than graphics. Sixteen cores and 22 threads on the Intel Core Ultra 9 185H do the work, 64GB of user-upgradable DDR5 provides the pool, and two 10Gbps Ethernet ports make it practical to move multi-gigabyte GGUF files without waiting on a 2.5GbE link.
At 64GB it sits in the 32B-to-70B sweet spot, and the ceiling of 96GB leaves room for a longer context. Reviewers consistently single out the port count and the dual networking as the reason to buy, using it for media servers and business workloads.
When Dual 10GbE Beats a Faster CPU
Pulling a 40GB model over 2.5GbE takes well over two minutes. Over 10GbE that drops to a fraction of the time, which is why this box appeals to anyone running a shared inference server or syncing model libraries between nodes. The trade-off is that this is a compute and network box, not a rendering or gaming machine.
The Limits to Know Before Ordering
Two constraints stand out. Memory stops at 96GB, which rules out the 128GB unified class, and the integrated Arc graphics are not a substitute for a discrete card in 3D or gaming work. Dual M.2 slots support up to 8TB, and Windows 11 Pro comes pre-installed with Linux fully supported.
5. BOSGAME VTA-439 – Expands to 256GB, the Longest Upgrade Path Here
- ✓ Memory expands all the way to 256GB
- ✓ Three Gen4 M.2 slots for model libraries
- ✓ OCuLink external GPU expansion
- ✓ Quad display with 4K144 output
- ✓ Dual 2.5GbE LAN
- ✕ 32GB base memory is modest
- ✕ Integrated Radeon 890M limits gaming
- ✕ Fan noise under sustained heavy load
32GB DDR5 to 256GB
Three M.2 to 12TB
OCuLink eGPU
54W draw
Nothing else here scales memory as far. The VTA-439 starts at 32GB of DDR5-5600 but accepts 128GB modules, giving a documented ceiling of 256GB. Start at 32GB for a 14B-to-27B machine, or fill both slots later and take on a 70B model without changing platforms.
The Ryzen AI 9 HX 470 brings 12 cores and 24 threads with an 86 TOPS total AI figure, of which 55 TOPS come from the XDNA 2 NPU that does not accelerate token generation. What does matter is the Radeon 890M and the storage layout: three Gen4 M.2 positions expandable to 12TB, which is the right answer to a GGUF library that grows every month.
A 765g Box That Runs Cool at 54W
Power consumption is listed at 54 watts, and reviewers repeatedly describe the cooling as quiet. For a machine intended to sit powered on as an always-on server, idle behaviour and acoustics matter more than peak speed, and this one handles both well. The chassis weighs 765g and measures 5.91 by 5.91 by 1.77 inches.
What the 32GB Starting Point Costs You
Out of the box this is a 14B-to-27B class machine, and buyers who want 70B work need to add memory first. The Radeon 890M’s 16 compute units handle token generation competently but will not satisfy a graphics-heavy gaming build. Quad output includes HDMI 2.1 and DisplayPort 1.4 at 4K144Hz plus USB4 at 8K60Hz.
6. MINISFORUM M1 Pro – 64GB of DDR5 and Near-Silent Under Load
- ✓ Extremely quiet under sustained load
- ✓ 64GB DDR5 upgradeable to 128GB
- ✓ Aluminium alloy chassis with phase-change cooling
- ✓ Dual USB4 with 65 to 100W PD-in
- ✓ Quad display including 8K60Hz
- ✕ OCuLink occupies one M.2 slot
- ✕ No travel case for the chassis
- ✕ Some sibling models ship with a WiFi card Linux does not support
64GB DDR5-5600 to 128GB
Dual M.2 to 8TB
OCuLink PCIe 4.0 x4
45dB full load
Silence is the defining trait here. Owners describe the M1 Pro as extremely quiet even under sustained load, and the listed 45dB full-load figure with a 65W TDP backs that up. If the machine sits on your desk rather than in a cupboard, that is worth more than a few extra cores.
Underneath, the same Core Ultra 9 285H as the GEEKOM IT15 drives 64GB of dual-channel DDR5-5600 that can grow to 128GB, plus dual M.2 2280 PCIe 4.0 slots for up to 8TB. That is a 32B-class machine as configured, and a 70B machine after a memory upgrade.
Arc 140T and Where Its 77 TOPS Go
The 99 TOPS total splits into 9 TOPS of CPU, 13 TOPS of NPU and 77 TOPS of Arc 140T graphics. Only the third figure participates in generating tokens, and it shares the same DDR5 pool as the system. Two full-featured USB4 ports with 65 to 100W power input mean the box can be driven from a single cable to a dock.
The OCuLink Storage Trade-Off
The OCuLink PCIe 4.0 x4 port is the reason to like this machine and the reason to read the fine print: it is not hot-swappable and it occupies one of the two M.2 slots. Plan for a single NVMe drive if you use it. Owners otherwise report fast out-of-box performance and a premium aluminium build.
7. GMKtec EVO-T2S – Fastest Memory Here at 8533 MT/s
- ✓ 8533 MT/s memory is the fastest here
- ✓ Arc B390 contributes 122 TOPS of graphics compute
- ✓ 10G plus 2.5G LAN and OCuLink
- ✓ One PCIe 5.0 M.2 slot
- ✓ Three thermal modes including 35W silent
- ✕ 64GB LPDDR5X is soldered
- ✕ Integrated GPU is not a substitute for a discrete card
- ✕ 1-year limited warranty
64GB LPDDR5X at 8533 MT/s
Arc B390 with 172 TOPS
Dual M.2 to 16TB
10G and 2.5G LAN
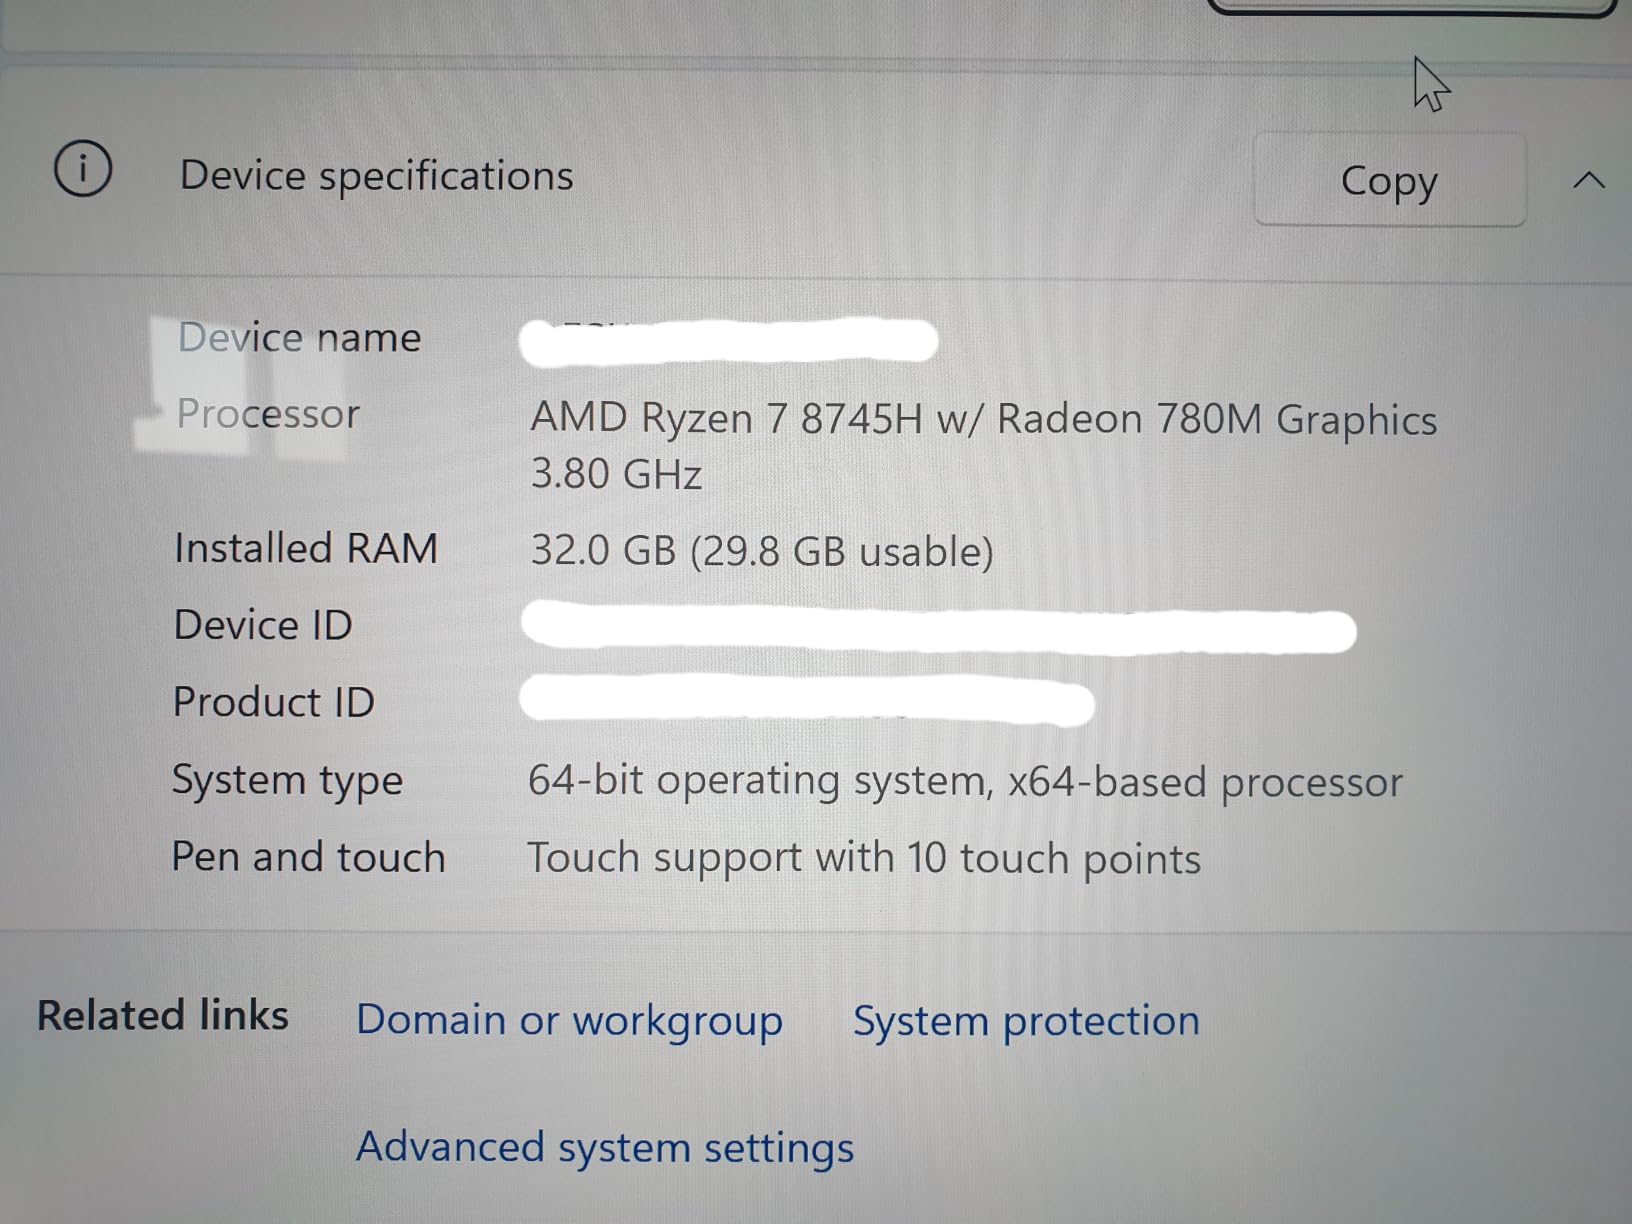
Memory bandwidth is the whole argument for this machine. Its 64GB of LPDDR5X runs at 8533 MT/s, faster than any other box in this guide, and the Intel Core Ultra X7 358H pairs it with the Arc B390 iGPU built on 12 Xe3 cores with 96 XMX AI cores. Faster memory means more tokens per second on any model both machines can hold.
Connectivity is unusually rich for a chassis this small: OCuLink for a discrete card, 10G and 2.5G LAN side by side, WiFi 7, and quad display output including 8K60Hz over DisplayPort. Storage expands across two M.2 2280 positions, one of them PCIe 5.0 x4, for up to 16TB.
Reading the 172 TOPS Number Honestly
Of that headline figure, 122 TOPS comes from the Arc B390 graphics and 50 TOPS from the NPU. Since Ollama, llama.cpp and LM Studio generate tokens on the graphics side, the 122 is the relevant number. The chassis measures 154 by 151 by 73.6mm and weighs roughly 950g bare, with a CNC metal finish and a VESA mount.
Three Fan Modes and a One-Year Warranty
Vapour chamber cooling with dual fans offers Silent at 35W, Balanced at 45W and Performance at 54W, peaking at 60W. For an always-on server the Silent mode matters more than the top setting. The main compromises are soldered memory with no upgrade path and a 1-year limited warranty, shorter than several rivals here.
8. Beelink SER10 MAX – The Entry Point With 32GB and 10GbE
- ✓ Lowest barrier to a 14B or 27B class model
- ✓ Dual memory slots for later expansion
- ✓ 10GbE LAN and USB4 40Gbps
- ✓ Quiet and power-efficient for a daily driver
- ✕ 32GB shipped memory
- ✕ No built-in speakers
- ✕ WiFi 6 rather than WiFi 7
- ✕ Beelink support is slow and outside North America
32GB DDR5 in dual slots
1TB PCIe 4.0 x4 SSD
10GbE LAN
Triple 4K output
The SER10 MAX is where most conversations about the best mini PCs for running LLMs locally should start, because it proves the point cheaply. Thirty-two gigabytes of DDR5 in dual slots is a 14B-to-27B class machine, and because the memory is in replaceable modules you can grow it later without replacing the machine.
Owners rate it highly as a secondary workstation, running coding work and WSL alongside a local model, and describe it as fast, compact and quiet. The 10GbE port means you can pull a large model off a network share without waiting, and dual M.2 slots expand to 8TB.
Upgrade Slots Are the Point
The memory listing describes dual slots expandable to 128GB, so the 32GB configuration is a starting point rather than a ceiling. That flexibility is what separates this box from sealed-memory alternatives at the same tier. Windows 11 Pro comes pre-installed and a 3-year warranty is included with lifetime technical support.
The Rough Edges
There are no built-in speakers, so plan on a headset or external audio, and the WiFi 6 card is a step down from the WiFi 7 hardware elsewhere in this guide. Some owners report driver setup friction on the wireless side and licensing oddities with the pre-installed OS, plus slow support responses outside North America.
9. MINISFORUM MS-01 – A Real PCIe x16 Slot and 10GbE SFP+
- ✓ Standard PCIe 4.0 x16 slot for a full-size GPU
- ✓ Dual 10Gbps SFP+ with link aggregation
- ✓ U.2 NVMe plus RAID 0 and 1 support
- ✓ vPro enterprise management
- ✓ 64GB installed memory
- ✕ Intel Iris Xe graphics are basic
- ✕ 64GB is the memory ceiling
- ✕ Only one HDMI port
64GB DDR5
PCIe 4.0 x16 slot
Dual 10G SFP+ and dual 2.5G
Powerful networking
The MS-01 is bought by people who want a real expansion path, and the networking is unmatched in this group. Two 10Gbps SFP+ ports with link aggregation, two 2.5G RJ45 ports and USB4 with 20Gbps Thunderbolt Ethernet add up to as much as 65Gbps aggregate, which is server-grade thinking in a desktop chassis.
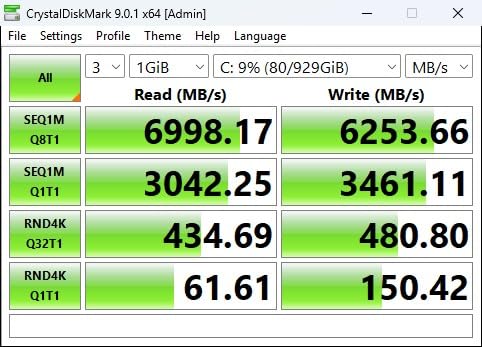
Storage follows the same logic, with support for three M.2 NVMe drives, a U.2 NVMe position, 22110 support and RAID 0 or 1, all on PCIe 4.0 links rated up to 7000MB/s. The box includes a U.2-to-M.2 adapter, a power adapter, an SSD heat sink and an HDMI cable.
Adding a Discrete GPU Later
This is the one machine in the guide with a full standard PCIe 4.0 x16 slot rather than an OCuLink x4 shortcut, so you can install a full-size card in a proper x16 slot and get more bandwidth than any integrated alternative here. For a homelab node that also runs Proxmox or Docker, the combination of vPro support and this networking is difficult to argue with.
Where It Falls Short for Local Models
Memory tops out at 64GB, which is enough for a quantized 70B but with little context headroom, and Intel Iris Xe graphics handle display output only. There is a single HDMI port, so additional displays need USB4 or an add-in card. Our picks for Proxmox and fanless boxes are covered separately if networking is the priority.
10. Beelink SER9 MAX – 64GB That Climbs to 256GB
- ✓ 64GB installed and expandable to 256GB
- ✓ Dual M.2 slots up to 8TB
- ✓ Extremely quiet on heavy transfers
- ✓ 10GbE LAN plus USB4 40Gbps
- ✓ 3-year warranty with 24/7 support
- ✕ Weak WiFi reception through the metal case
- ✕ Hard-to-reach coin-cell battery
- ✕ Radeon 780M is limited for modern games
64GB DDR5-5600 to 256GB
Radeon 780M with 12 CUs
USB4 40Gbps
10GbE LAN
The SER9 MAX gets the arithmetic right where cheaper boxes get it wrong. Sixty-four gigabytes of DDR5-5600 is installed, and the memory expands to 256GB with two 128GB modules, so it moves from a 32B machine to a 70B-plus machine on the same chassis. The 12-core Radeon 780M is a modest but workable token generator for a 14B model.
Reviewers highlight the build, near-silent operation and easy SSD access through the bottom cover and dust filter. At 16 ounces it is one of the lighter boxes here, and the port list includes USB4 at 40Gbps with power delivery and 10GbE Ethernet.
Memory Ceiling Without a Premium
A 256GB ceiling is unusual at this size, and it is the reason this box rates as the best value pick here. The catch is bandwidth: dual-channel DDR5-5600 delivers less per second than the LPDDR5X-8000 configuration in the 128GB boxes, so a model both can hold will generate tokens faster on those machines. Capacity decides what runs, bandwidth decides how fast.
Two Annoyances Worth Knowing
The aluminium chassis attenuates WiFi, which is a real problem if you sit close to a mesh router, and the coin-cell battery is difficult to reach on this generation. A small number of owners also report occasional shutdown or boot failures. Buyers who need a completely fanless box should look at our fanless mini PC guide instead.
11. GMKtec X3 – The Only Box Here With Verified 70B-Class Throughput
- ✓ Owner-reported 86 tok/s on Qwen3-30B-A3B
- ✓ Owner-reported 50 tok/s on gpt-oss-120B
- ✓ Vast 128GB unified memory pool
- ✓ Easy case opening for extra NVMe drives
- ✓ OCuLink expansion available
- ✕ Windows caps usable VRAM near 64GB
- ✕ BIOS lacks proper fan curve control
- ✕ Only a 1-year limited warranty
128GB LPDDR5X-8000 eight-channel
Radeon 806S with 40 CUs
2TB with dual M.2
OCuLink eGPU
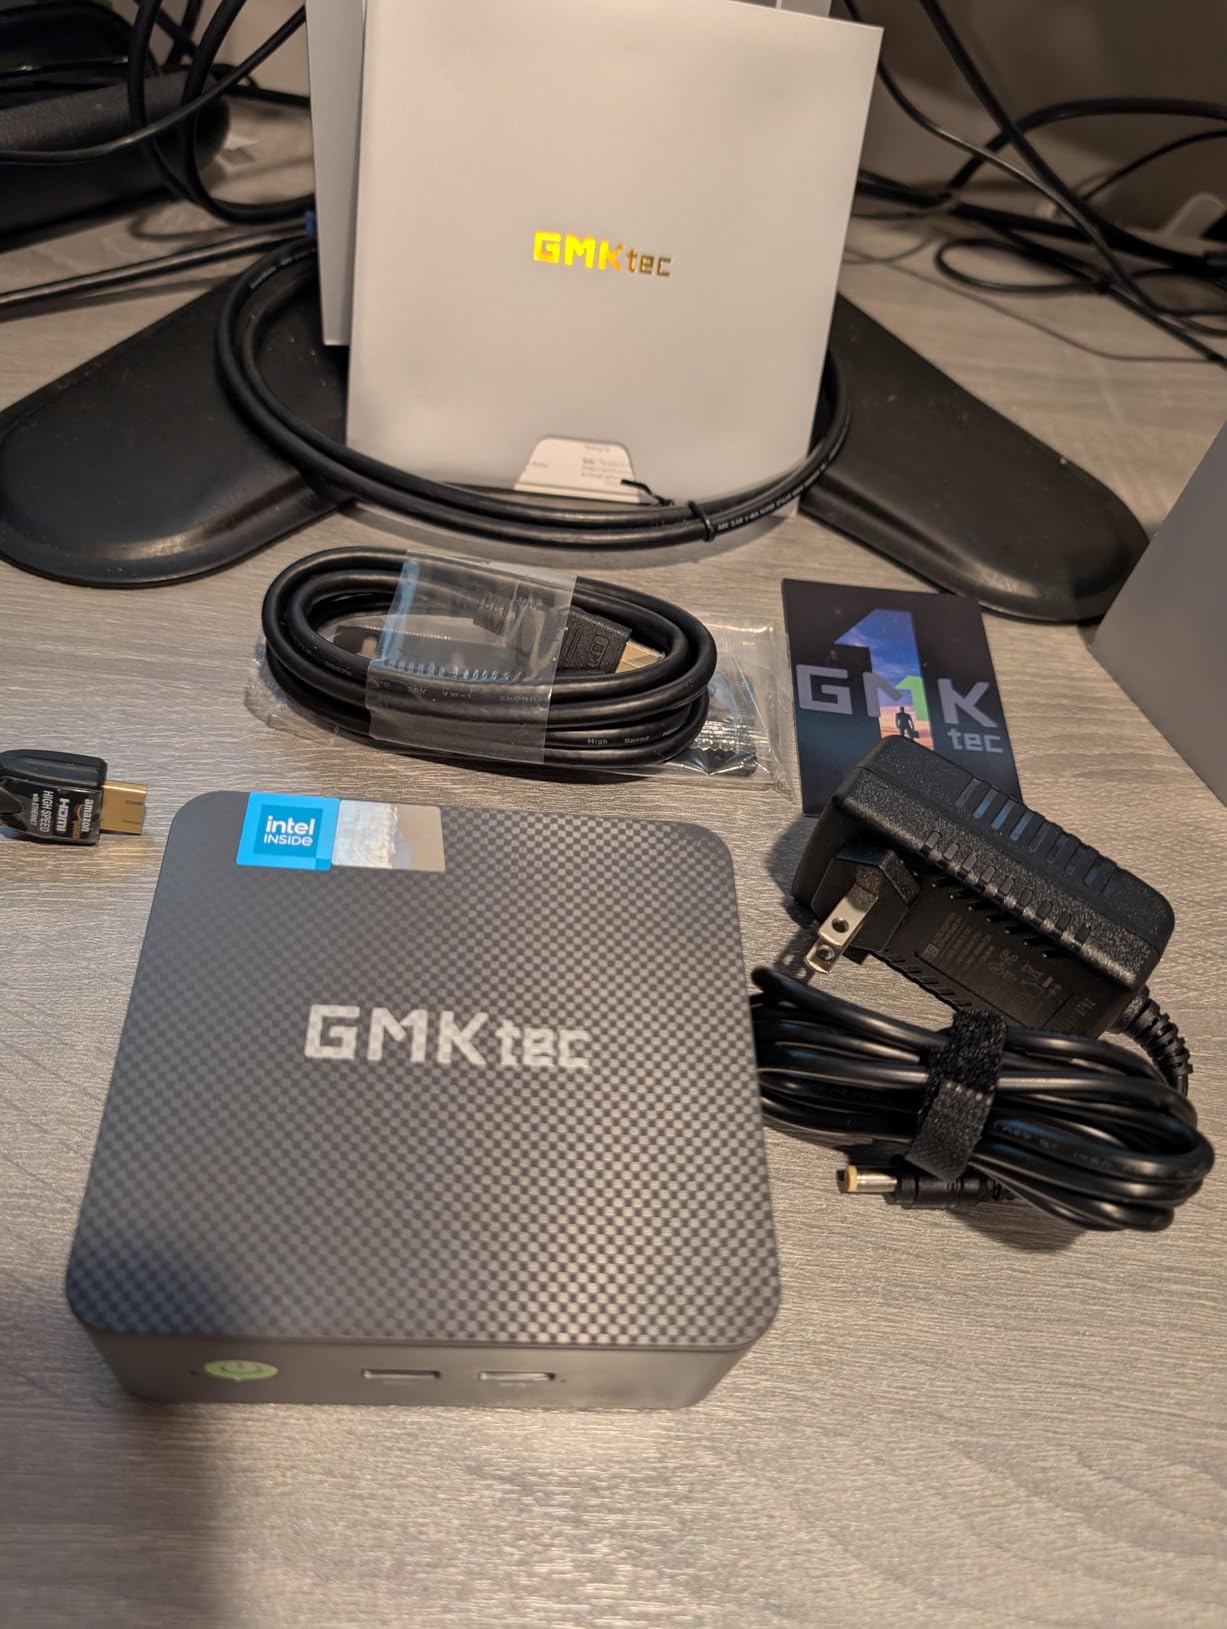
The X3 is the fastest machine here for actual model work, and the evidence is unusually concrete. Owners report 86 tok/s on Qwen3-30B-A3B and 50 tok/s on gpt-oss-120B under Linux with the Vulkan back-end, plus 17 to 18 tok/s on a 235B Q3 model. Those are community-reported figures rather than our own measurements, but they come with the runtime and back-end named, which is the bar we hold everything to.
The hardware underneath is the same Ryzen AI Max+ 395 platform as the BOSGAME M5, with 16 Zen 5 cores, 32 threads and a Radeon 806S of 40 RDNA 3.5 compute units, but here it sits in an eight-channel LPDDR5X-8000 configuration rated at 128GB. Dual M.2 slots hold 2TB and expand to 16TB, and OCuLink allows a discrete GPU later.
The Windows VRAM Cap Is the Real Limit
This is the single most important caveat in the guide. Under Windows, usable graphics memory caps out around 64GB, so only about half of the 128GB pool is reachable by the back-end. Under Linux roughly 110GB becomes available, which is the difference between a large MoE model loading and not loading. Buy for the software you will actually run.
Support and BIOS Rough Edges
The BIOS is sparse with no proper fan curve control, and the fixed speed options are loud. Driver and BIOS downloads are hosted on a link owners report as frequently saturated, and the warranty is 1 year. None of that touches inference speed, but it tells you where support stands.
The Buying Guide: How to Choose a Mini PC for Local LLMs
Soldered or Upgradeable Memory Is the Dealbreaker
Most 32GB machines in this class ship with LPDDR5X soldered to the board, and most 64GB machines use replaceable DDR5 modules. That distinction decides whether a machine bought today can run a 70B model in two years, and almost every roundup buries it in a spec list. If you can accept a fixed 128GB ceiling, the BOSGAME M5 and GMKtec X3 are the two boxes here that reach the 70B class out of the box. If you would rather start at 32GB and grow, the VTA-439, SER9 MAX, AI X1 Pro and M1 Pro all take replaceable memory, and the VTA-439 and SER9 MAX reach 256GB.
Memory Bandwidth Decides Your Tokens per Second
Every generated token streams the model weights across the memory bus once, so tokens per second track bandwidth closely. Dual-channel DDR5-5600 is the common baseline here, while eight-channel LPDDR5X-8000 in the 128GB boxes is roughly twice the bus width. On a model both machines can hold, the faster memory wins clearly. This is why the 64GB GMKtec EVO-T2S at 8533 MT/s is more interesting than its capacity alone suggests, and why the 64GB M1 Pro and IT15 feel ordinary next to the 128GB Ryzen AI Max+ boxes.
Do You Need an NPU? No, Not for Token Generation
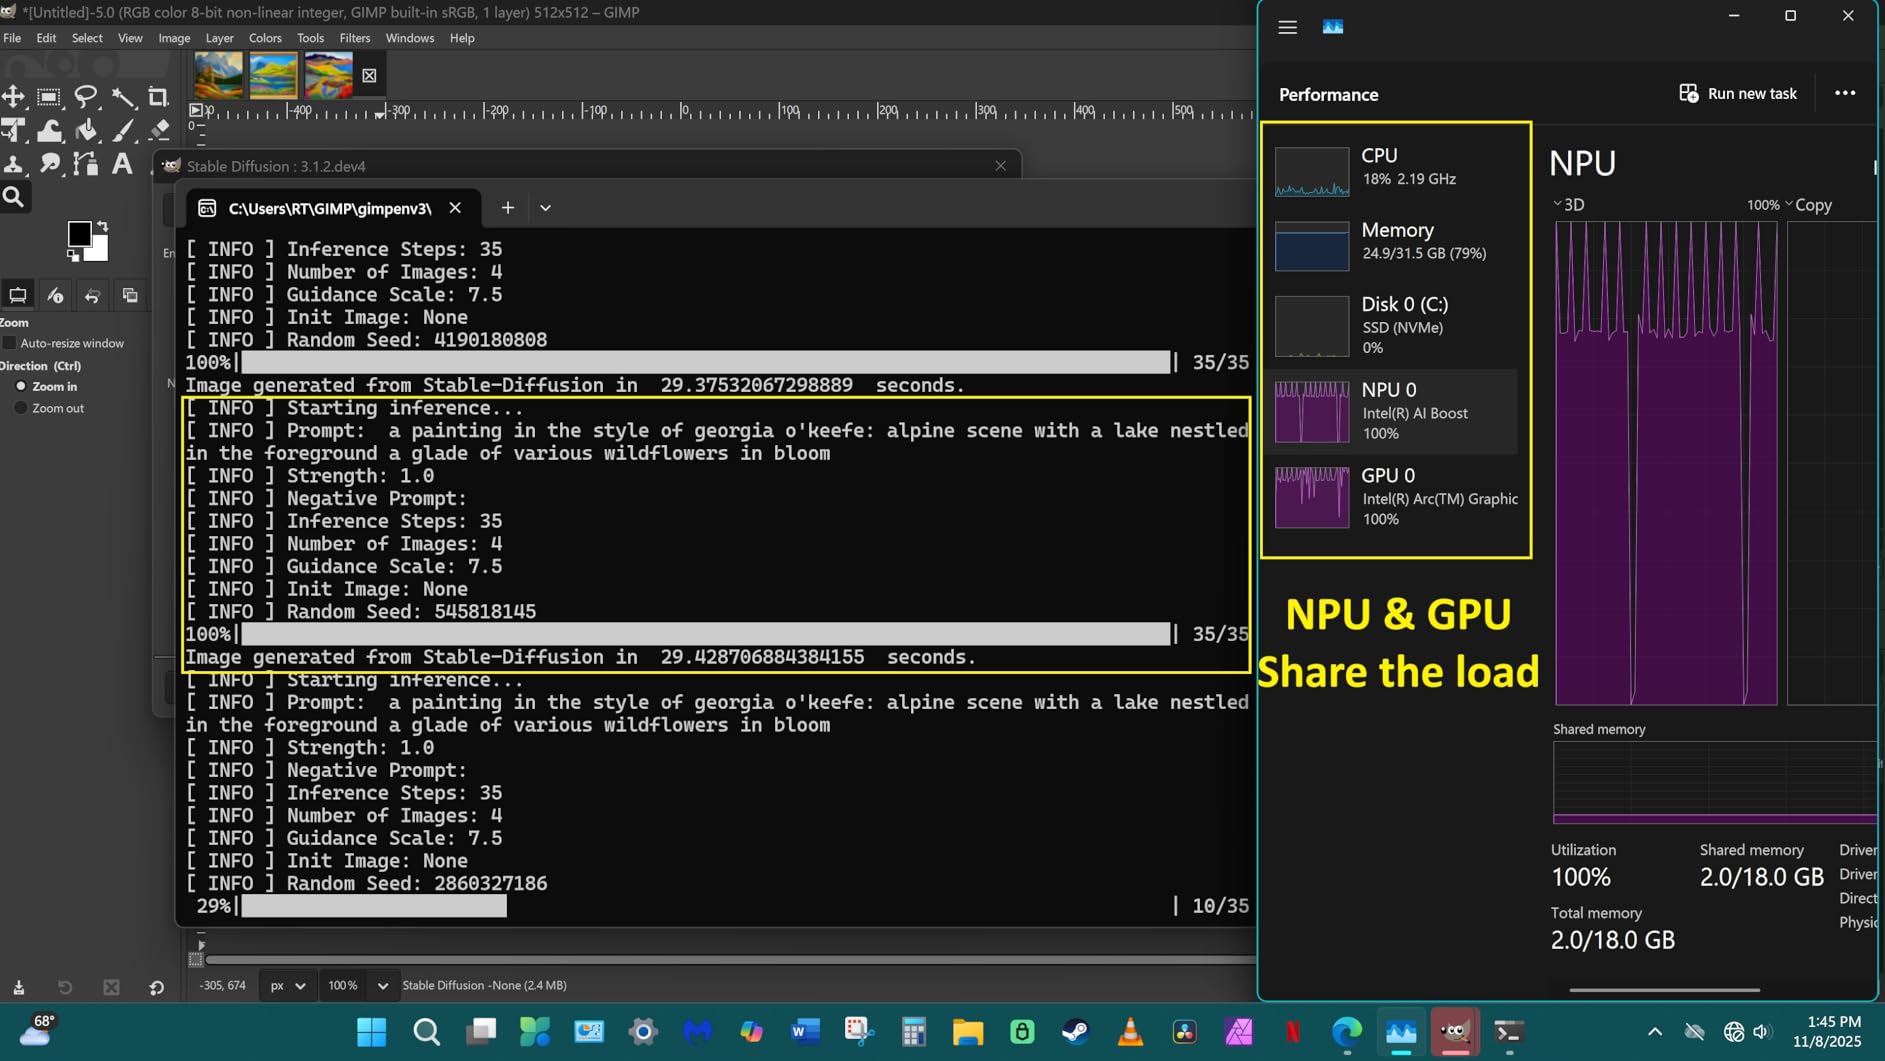
Plainly stated: Ollama, llama.cpp and LM Studio do not route LLM token generation to the NPU. The NPU figures quoted in this category, 50 TOPS, 55 TOPS, 80 TOPS, accelerate background blur, noise suppression and small vision models. Token generation runs on the CPU and the integrated GPU, which is why the graphics TOPS figure is the one worth reading and the NPU number is marketing filler for your purposes. An Ask HN thread on local LLM hardware drew exactly this complaint, with users describing non-NVIDIA stacks as effectively a second-class citizen and some giving up after builds would not compile.
The Software Stack Is Fiddly Outside CUDA
On an AMD or Intel mini PC you will be running llama.cpp on the Vulkan back-end or through Ollama and LM Studio, and sometimes through ROCm. That is workable and well documented, but version alignment is the recurring pain point, with users describing the need to match the developer’s stack down to a specific release. Budget an evening for setup, not five minutes. Our advice: pull a model a full tier below your memory ceiling on day one, confirm it loads, then work upward.
NVMe Storage for a Growing GGUF Library
All eleven boxes carry two M.2 positions as a baseline, and the AI X1 Pro and VTA-439 both take three drives for up to 12TB, while the EVO-T2S and X3 support up to 16TB. The 2TB configurations are the sensible starting point for a serious library. Our Proxmox mini PC picks cover the storage side in more depth.
Noise and Idle Watts for 24/7 Use
An always-on server is billed on idle draw, not peak speed. The VTA-439 is listed at 54W and the EVO-T2S has a 35W Silent mode, which is the number to watch if the box runs around the clock. For acoustics, the IT15 sits under 35dB in normal use while the AI X1 Pro and M1 Pro are quoted at 45dB under full load. Fans matter less than people expect because inference load is steady rather than bursty. If refresh rate and frame pacing matter more to you, our mini PC emulation picks cover that angle.
When to Skip the Mini PC and Buy a Desktop GPU
Buy a tower instead if your models fit comfortably in 16GB, you care about tokens per second more than footprint or silence, and you have room for a desktop. A discrete card with 16GB of VRAM runs CUDA-based builds without any of the driver friction described above, and community measurements put an RTX 3090 at 95.7 tok/s on Llama 3.1 8B, several times what any integrated-GPU mini PC manages on the same model. Our desktop picks cover this side in detail. The mini PC case wins on capacity, on power, and on the ability to sit next to a NAS rather than under a desk.
Homelabs: One Box, Two Jobs
The most common pattern we see in forum threads is a single machine running Proxmox or Docker alongside Ollama, which is where boxes with three M.2 slots and dual 2.5GbE or 10GbE earn their keep. Practitioner advice from a home lab community is consistent: max out RAM and install dual NVMe before spending on GPU power, unless local AI is the primary goal. Clustering two boxes over 10GbE is also workable, and shares the model across nodes for a larger context, though the network hop costs you latency.
Setting Up Ollama on Day One
Step one, install the runtime. Ollama gives you the simplest path, LM Studio gives you a graphical front end for the same models, and llama.cpp gives you the most control over quantization and back-end. Any of the three will work on the boxes above; CUDA-only instructions will not, unless you add a discrete card.
Step two, pull a model a tier below your ceiling. On the 32GB boxes start with a 14B or 27B at Q4, on 64GB start with a 32B, and on the 128GB boxes a 70B quantized model. Step three, benchmark your own tok/s rather than trusting a number on a listing, and record the model, quantization and back-end so you can compare later.
Step four, cap the context window and plan storage. Setting a sensible context ceiling avoids the KV cache growth trap that pushes a model into swap, and filling both M.2 slots leaves you room to add quantizations without a rebuild. Expect prices to move week to week in this category, so check current pricing on every model before you commit.
Frequently Asked Questions
What kind of computer do I need to run LLMs locally?
You need memory capacity first and graphics second. A quantized Q4 model costs roughly 0.5 to 0.6GB per billion parameters, so 16GB of system memory handles 7B and 8B models, 32GB reaches 14B to 27B, 64GB holds a 32B or a quantized 70B, and 128GB makes 70B and large mixture-of-experts models comfortable. Tokens per second then scale with memory bandwidth, so prefer a wide memory bus over a fast CPU.
Which mini PC is best for AI development?
For local AI development, the GEEKOM IT15 is the best starting point because its 32GB of DDR5 is replaceable and expands to 128GB, so the same machine grows with your model sizes. If you want the memory fitted from day one, the MINISFORUM AI X1 Pro ships with 96GB of upgradeable DDR5 plus three M.2 slots and OCuLink expansion. For a homelab node, the MINISFORUM MS-01 adds dual 10G SFP+ networking and a full PCIe 4.0 x16 slot.
Which Mac mini is best for local LLMs?
Apple silicon is a strong alternative for local LLMs because the unified memory pool and Metal back-end handle large models efficiently, and the software story is smoother than Vulkan on Windows or Linux. The rule is the same as on x86: capacity decides what runs, so choose the model with the most memory you can afford rather than the fastest chip. One caveat is CUDA-only tooling, which will not run on macOS, so check that your workflow does not depend on it.
What is the downside to a mini PC?
Three things. Memory is often soldered, so a 32GB or 64GB machine with LPDDR5X cannot be upgraded and a 128GB machine is a fixed commitment. Graphics are integrated, so a discrete card usually means an OCuLink or PCIe slot that costs you an M.2 position. And the software back-end is less settled, since Ollama, llama.cpp and LM Studio run through Vulkan or ROCm on AMD and Intel silicon instead of CUDA, which means more version matching.
How much RAM do I need to run a 70B model locally?
At Q4 quantization a 70B model needs roughly 40GB, so 48GB is the practical minimum and 64GB is comfortable. If you plan a long context, remember the KV cache grows with the window, so give yourself 8GB or more of headroom. For 70B at longer context, or for large mixture-of-experts models, 128GB of unified memory is the sensible target.
Is the NPU used for LLM inference?
Not for token generation in the tools most people use. Ollama, llama.cpp and LM Studio generate tokens on the CPU and the integrated GPU, not on the NPU. NPU TOPS figures accelerate background effects and small vision models instead. This is why we rank these machines on memory capacity, memory bandwidth and graphics compute, and why the NPU number on a spec sheet should not break a tie.
The Verdict: Which Mini PC Should You Buy
If you want one machine that covers most serious local LLM work and can grow later, take the GEEKOM IT15: replaceable 32GB DDR5 with a 128GB ceiling, the largest owner review base in this group, and near-silent cooling. If you need 70B models fitted from day one, the BOSGAME M5 gives you 128GB of unified memory at 1.34kg, while the GMKtec X3 is the fastest of the set and the only one with owner-verified throughput, provided you run Linux rather than Windows.
For maximum flexibility, the MINISFORUM AI X1 Pro with 96GB of upgradeable DDR5 and three M.2 slots, the BOSGAME VTA-439 for a 256GB memory ceiling, and the Beelink SER9 MAX for 64GB that can climb to 256GB are the sensible buys. Whichever you pick, match the memory tier to the model class you want and check current pricing, because these machines move week to week. That is our guide to the best mini PCs for running LLMs locally in 2026, tested and ranked by the two specs that actually decide token generation.

