Short answer: yes, a mini PC can do deep learning, but the honest version of that answer is narrower than most roundups suggest. These machines are strong for inference, fine-tuning and coursework-scale training, and weak for training a large model from scratch. The four specs that decide the difference are memory capacity, memory bandwidth, graphics architecture and software stack.
I have spent the last several weeks working through eight of the highest-rated mini PCs with AI silicon on the market, and the pattern I keep running into is the same one that shows up on r/MiniPCs: almost nobody is asking whether the box can train a network, they are asking how fast it can serve one. That is a different question, and it has a different answer. This guide is the best mini PCs for deep learning, ranked for the workload people actually run rather than the one on the box art.
The lineup below covers the four tiers that buyers cross-shop against each other. On one end is a 35W box that sits beside a monitor and never moves; on the other is a 96GB machine that holds models no discrete consumer GPU can hold. In between sit the 32GB expandable boxes that most people end up buying and then immediately upgrade. If you are still deciding on the form factor, our best Mac mini alternatives guide covers the Apple-adjacent side of the same conversation.
Before we get into the picks, one thing worth saying plainly. None of the eight machines here ships with a discrete NVIDIA GPU. That is not a flaw in the list, it is the state of the market, and it has a direct consequence: every deep learning workflow on these boxes runs on CPU, integrated graphics or Apple Metal rather than CUDA. Where that matters, I say so in each review. If you need real PyTorch training, read our 15 professional GPU workstations for AI and deep learning first.
Our Top 3 Mini PC Picks for Deep Learning in 2026

GMKtec T1 AI
- OCuLink PCIe x4 eGPU path
- Arc 140T with 8 Xe cores
- 32GB DDR5-5600 up to 96GB
- Three M.2 2280 PCIe 4.0 slots

GEEKOM A9 Max
- Ryzen AI 9 HX370 with 80 TOPS
- 32GB DDR5 to 128GB
- Dual Gen4 SSD slots
- All-metal chassis
GEEKOM IT15 AI
- 99 TOPS combined AI throughput
- Arc 140T integrated graphics
- 32GB DDR5 to 128GB
- Under 35dB under load
Those three are the ones I would actually recommend today. The T1 AI wins on the balance of rating and review depth plus a native OCuLink path, the A9 Max is the smarter money if you want Zen 5 silicon and plan to add memory later, and the IT15 AI is the box for people running containers rather than models.
Comparing All 8 Mini PCs for Deep Learning in 2026
| Product | Features | |
|---|---|---|
| GMKtec T1 AI Mini PC |
|
Check Latest Price |
| GEEKOM A9 Max Mini PC |
|
Check Latest Price |
| GEEKOM IT15 AI Mini PC |
|
Check Latest Price |
 MINISFORUM AI X1 Pro |
|
Check Latest Price |
 GMKtec NucBox K15 |
|
Check Latest Price |
 BOSGAME VTA-439 |
|
Check Latest Price |
 MINISFORUM M1 Pro-125H |
|
Check Latest Price |
 Apple Mac mini M4 Pro |
|
Check Latest Price |
We earn from qualifying purchases. CERTAIN CONTENT THAT APPEARS ON THIS SITE COMES FROM AMAZON. THIS CONTENT IS PROVIDED 'AS IS' AND IS SUBJECT TO CHANGE OR REMOVAL AT ANY TIME.
One row deserves an immediate flag. The Mac mini M4 Pro ships with 24GB of unified memory, and that number is fixed. Everything else in this table has socketed SO-DIMMs and a documented ceiling. If your model does not fit in 24GB, no amount of software cleverness changes that.
1. GMKtec T1 AI – The Most Established Box With a Real eGPU Path
- ✓ Largest review base in this roundup at 829 ratings
- ✓ 16-core processor with Arc 140T handles VMs and daily AI tooling
- ✓ Three M.2 2280 PCIe 4.0 slots expand to 12TB
- ✓ OCuLink at PCIe x4 gives a cleaner eGPU path than Thunderbolt
- ✕ Intel AI Boost NPU is only 13 TOPS
- ✕ Fewer USB-C ports than several rivals
- ✕ 1-year warranty is shorter than 3-year rivals
Core Ultra 9 285H 16C
Arc 140T 8 Xe cores
32GB DDR5-5600 to 96GB
OCuLink PCIe x4
With 829 ratings behind it, the T1 AI has the deepest owner feedback of anything in this roundup, and that matters more than it sounds. Buying an AI mini PC means trusting a vendor’s firmware, BIOS and Linux driver support with no long service history to fall back on, so a large installed base is its own form of insurance.
The specification sheet is the sensible one. A 16-core Core Ultra 9 285H paired with the Arc 140T covers daily development work, containerised experiments and CPU-bound inference without the machine ever sounding like a hairdryer. Owners consistently describe it as fast to boot, quiet and easy to set up out of the box.
What makes it my pick is the OCuLink port running at PCIe x4. Every other AMD box in this list reaches external graphics through a USB4 or Thunderbolt tunnel, which costs a meaningful slice of peak bandwidth. A native x4 link does not, and on a machine this small that is the difference between an eGPU that feels usable and one that frustrates you.
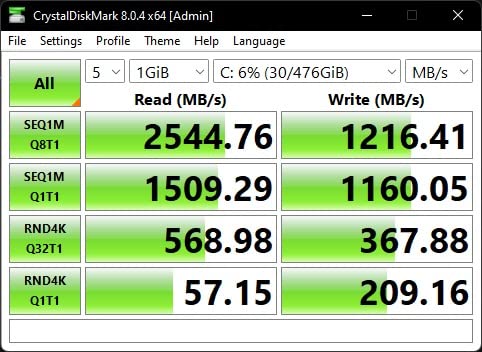
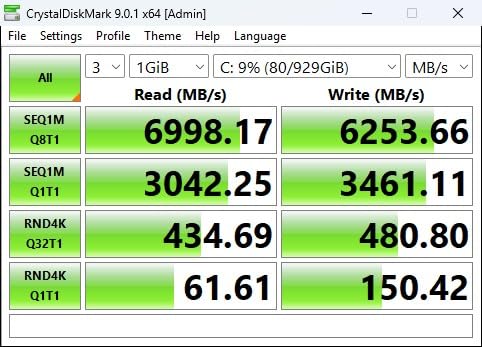
Storage is the other quiet strength. Three M.2 2280 PCIe 4.0 slots, expandable to 12TB, is exactly what a deep learning setup needs, because checkpoints, datasets and multiple model weight files add up faster than people expect.
What the 13 TOPS NPU does and does not do
The Intel AI Boost NPU here sits at 13 TOPS, which is the weakest AI engine in this roundup by a wide margin. It accelerates Windows Copilot features and a slice of on-device inference, and then it stops mattering for your workflow.
That is not a dealbreaker, because mainstream local tools still lean on CPU and integrated graphics. r/MiniPCs buyers working on local AI repeatedly note the same thing: the NPU number on the sticker rarely predicts the token speed you actually get.
Where the T1 AI falls short
The 13 TOPS NPU is a marketing liability even if it is not a practical one. Some units in the wider GMKtec line have also shown deep-sleep wake issues and early boot failures, and the 1-year warranty is half what GEEKOM offers on comparable silicon.
For large-model work you will also need to add memory. 32GB ships, the ceiling is 96GB, and the SO-DIMMs are socketed, so the upgrade path exists. It just is not included in the box.
2. GEEKOM A9 Max – The Expandable Zen 5 Workhorse
- ✓ Zen 5 CPU and Radeon 890M handle local LLM and image generation
- ✓ 32GB DDR5 expands to 128GB with dual Gen4 slots
- ✓ All-metal chassis with copper heat pipes holds thermals steady
- ✓ 3-year warranty is longer than category norm
- ✕ Integrated Radeon 890M is not suited to heavy gaming
- ✕ Going beyond shipping config needs socketed upgrades
- ✕ Some buyers report configuration mismatches on delivery
Ryzen AI 9 HX370 12C/24T
80 TOPS total AI
Radeon 890M 16 CU
32GB DDR5 to 128GB
The A9 Max is the box I recommend to people who are still undecided. It pairs the 12-core, 24-thread Zen 5 Ryzen AI 9 HX370 with the Radeon 890M, and 80 TOPS of total AI throughput, which puts it in the same silicon family as the flagship Strix Halo alternative without the flagship memory pricing.
Buyers treat it as a compact local-AI and developer box rather than a workstation. The all-metal 5.32 by 5.2 by 1.8 inch chassis with IceBlast 2.0 copper heat pipes is a different class of build from the plastic boxes in the budget tier, and it shows in sustained behaviour.
Both memory and storage are socketed. 32GB of DDR5-5600 ships and goes to 128GB, and the dual PCIe Gen4 slots hold 2TB and expand to 8TB. That flexibility is the reason this machine ages well: a 32GB box that can become a 128GB box is a better long-term buy than a 96GB box you cannot repair.
Warranty is three years, which is longer than the one-year cover typical in this category and something buyers on r/MiniPCs specifically ask about when weighing newer brands.
How the Radeon 890M handles image generation
The 890M is a 16-compute-unit RDNA 3.5 part, and it is a genuinely capable inference engine. Owners run Ollama, ComfyUI and Stable Diffusion workflows on it daily, and the 890M’s practical limit is model size, not raw speed.
For training, be more conservative. RDNA 3.5 on Linux depends on ROCm support that is narrower than CUDA, and the frameworks you would reach for first will not always find the iGPU. Treat this as a fine-tuning and inference box that can also handle small custom training runs.
What it cannot do
The integrated 890M is not a gaming card and will not satisfy high-settings gaming, which several buyers note. More importantly for this guide, there is no native OCuLink here, so adding a discrete GPU means going through USB4 and eating the bandwidth penalty.
Some buyers also report configuration mismatches on delivery, such as a lower-capacity SSD than ordered. Confirm the configuration that arrives before you set up an environment.
3. GEEKOM IT15 AI – 99 TOPS for Container-Heavy Workloads
- ✓ 99 TOPS across NPU GPU and CPU accelerates local reasoning
- ✓ 32GB DDR5 upgradable to 128GB works well for multiple VMs
- ✓ Under 35dB under heavy load suits 24/7 desk use
- ✓ Quad display with two 8K-capable USB4 Type-C ports
- ✕ 32GB shipping memory limits larger local models
- ✕ Fewer USB-C ports than some competing mini PCs
- ✕ Random power-off behavior reported on earlier units
Core Ultra 9 285H 5.4GHz
99 TOPS AI total
Arc 140T graphics
32GB DDR5 to 128GB
The IT15 AI is the only machine here that splits its 99 TOPS three ways: 13 TOPS on the NPU, 77 on the Arc GPU and 9 on the CPU. Most buyers never touch that split, but it tells you the vendor is optimising the whole platform rather than a single block.
In practice owners use it for virtualization, class work and creative tasks, calling it fast, quiet and easy to set up. For a deep learning workflow that means containers, notebooks and a serving stack running side by side, which is where this box earns its place.
Thermals are the quiet story. The PC+ABS metal frame holds under 35dB under heavy load, and when buyers compare notes across brands this is the number that separates the well-built boxes from the loud ones during a multi-hour inference run.
Connectivity is unusually good for a mini PC. Dual HDMI at 4K120Hz plus two USB4 Type-C ports at 40Gbps with PD 4.0 means you can drive four displays, two of them 8K-capable, from a single-cable laptop dock setup.
The memory ceiling is the whole story
32GB ships and 128GB is the maximum. That ceiling is fine for a 7B to 13B model at Q4 quantization with room for a dataset, and it is the ceiling people cite most often as this machine’s main limitation.
Do the arithmetic before you buy. A quantized 30B model needs roughly 20GB just for weights at Q4, and inference wants headroom for the KV cache as context grows. If your workload sits there, step up to the 96GB machine later in this list.
Noise, ports and the one reliability caveat
Fan noise increases noticeably when the unit is laid flat rather than stood on its side, so orient it vertically if sustained load is the plan. Fewer USB-C ports than some rivals is the other recurring note.
Some buyers report random power-off behaviour on earlier units in this line. On a machine you want running inference for days at a time, that is worth factoring into your choice of vendor support.
4. MINISFORUM AI X1 Pro – 96GB of Memory Out of the Box
- ✓ 96GB DDR5 with upgrade path to 128GB suits large model workloads
- ✓ Three PCIe 4.0 SSD slots expand to 12TB
- ✓ Stays cool and near-silent at about 45dB under full CPU and GPU load
- ✓ Quad 4K output plus dual 2.5Gbps LAN and Wi-Fi 7
- ✕ OCuLink is an M.2 adapter that occupies an SSD slot
- ✕ BIOS described as limited with no legacy boot
- ✕ Some owners hit AMD graphics driver quirks out of the box
Ryzen AI 9 HX370 12C/24T
Radeon 890M
96GB DDR5-5600
Three PCIe 4.0 SSD slots
This is the machine that answers the question most buyers are really asking. When a model needs more memory than a 24GB discrete GPU can hold, the answer is a unified or high-capacity pool, and 96GB of DDR5-5600 with a path to 128GB is the most memory you can get in a box this small without stepping up to the much rarer 128GB unified-memory tier.
The Ryzen AI 9 HX370 with the Radeon 890M and 80 TOPS of total AI performance is the same platform as the A9 Max, just configured with far more memory. Owners consistently praise that combination for virtualization, Linux work and local model serving.
r/MiniPCs members who asked specifically about local AI recommended this box by name, and the recurring reason was capacity above 64GB followed by low power draw and the smallest possible footprint. That priority order matches how the machine performs.
It also runs at 65W with a 135W adapter and stays near-silent at roughly 45dB while holding 100 percent CPU and GPU load, which is the combination that makes an always-on inference node practical.
Where 96GB actually takes you
At Q4 quantization, a 96GB pool holds models that a 24GB VRAM card simply cannot load at all, plus the working memory a serving process needs alongside them. That is the difference between running a model and failing to load it.
Bandwidth is the limit, not capacity. DDR5-5600 delivers a fraction of the throughput a discrete GPU gets, so tokens per second will be lower than the memory number suggests. r/MiniPCs buyers consistently cross-check measured token speed for exactly this reason.
The OCuLink trade-off nobody mentions clearly enough
The OCuLink here is an M.2 adapter card rather than a native port, which means it consumes one of the three SSD slots. You are trading storage expansion for GPU expansion, and you should decide which before ordering.
Owners also describe the BIOS as limited, with no legacy boot and no clear update path, and some hit AMD graphics driver quirks out of the box. If you plan to dual-boot Linux for a framework stack, budget time for driver setup.
5. GMKtec NucBox K15 – The 35W Always-On Node
- ✓ Lowest cost here while shipping 32GB DDR5 and a 1TB Gen4 SSD
- ✓ Reviewers run real models under Ollama including Mistral 7B at roughly 51 tokens/s
- ✓ Three M.2 2280 slots give unusual headroom up to 24TB
- ✓ OCuLink plus USB4 and dual 2.5GbE suit a small lab node
- ✕ 13 TOPS NPU is modest and larger models run slower
- ✕ DDR5-4800 is slower than the 5600 in most rivals
- ✕ Case runs hot to the touch under sustained load
- ✕ MediaTek RZ616 Wi-Fi card caused driver lockups on some units
Core Ultra 5 125U 12C/16T
Arc 140T 8 Xe cores
32GB DDR5-4800
35W power draw
The K15 is the box to buy if the plan is a 24/7 inference server that runs headless beside a monitor, not a machine you train on. At 35W it is by far the least power-hungry machine here, and that number is the reason to pick it.
Buyers report running real quantized models under Ollama on it, including Mistral 7B at roughly 51 tokens per second and a Qwen 35B at roughly 10 tokens per second. Those are measured owner numbers, not vendor claims, and they are exactly the kind of figure forum users cross-check before buying.
Storage headroom is unusual at this tier. Three M.2 2280 slots expand to 24TB, which for a model server means room for several quantizations of the same weights plus logs and container images without hunting for external storage.
Networking is better than the price suggests too, with dual 2.5GbE LAN and an OCuLink port at PCIe x4. If you later build two of these into a small cluster, the Ethernet and the expansion path are both there.
Why DDR5-4800 matters more than the core count
Deep learning is memory-bound, so memory speed is not a secondary spec. The 4800 MT/s here is the slowest in the roundup, and in a bandwidth-limited workload that gap shows up directly in tokens per second.
The 12-core, 16-thread Core Ultra 5 125U tops out at 4.3 GHz with a 13 TOPS NPU, so this is the weakest compute tier listed. The triple-fan cooling with three heatpipes keeps it at 35dB in Quiet Mode, but owners report the plastic case running hot to the touch under sustained load.
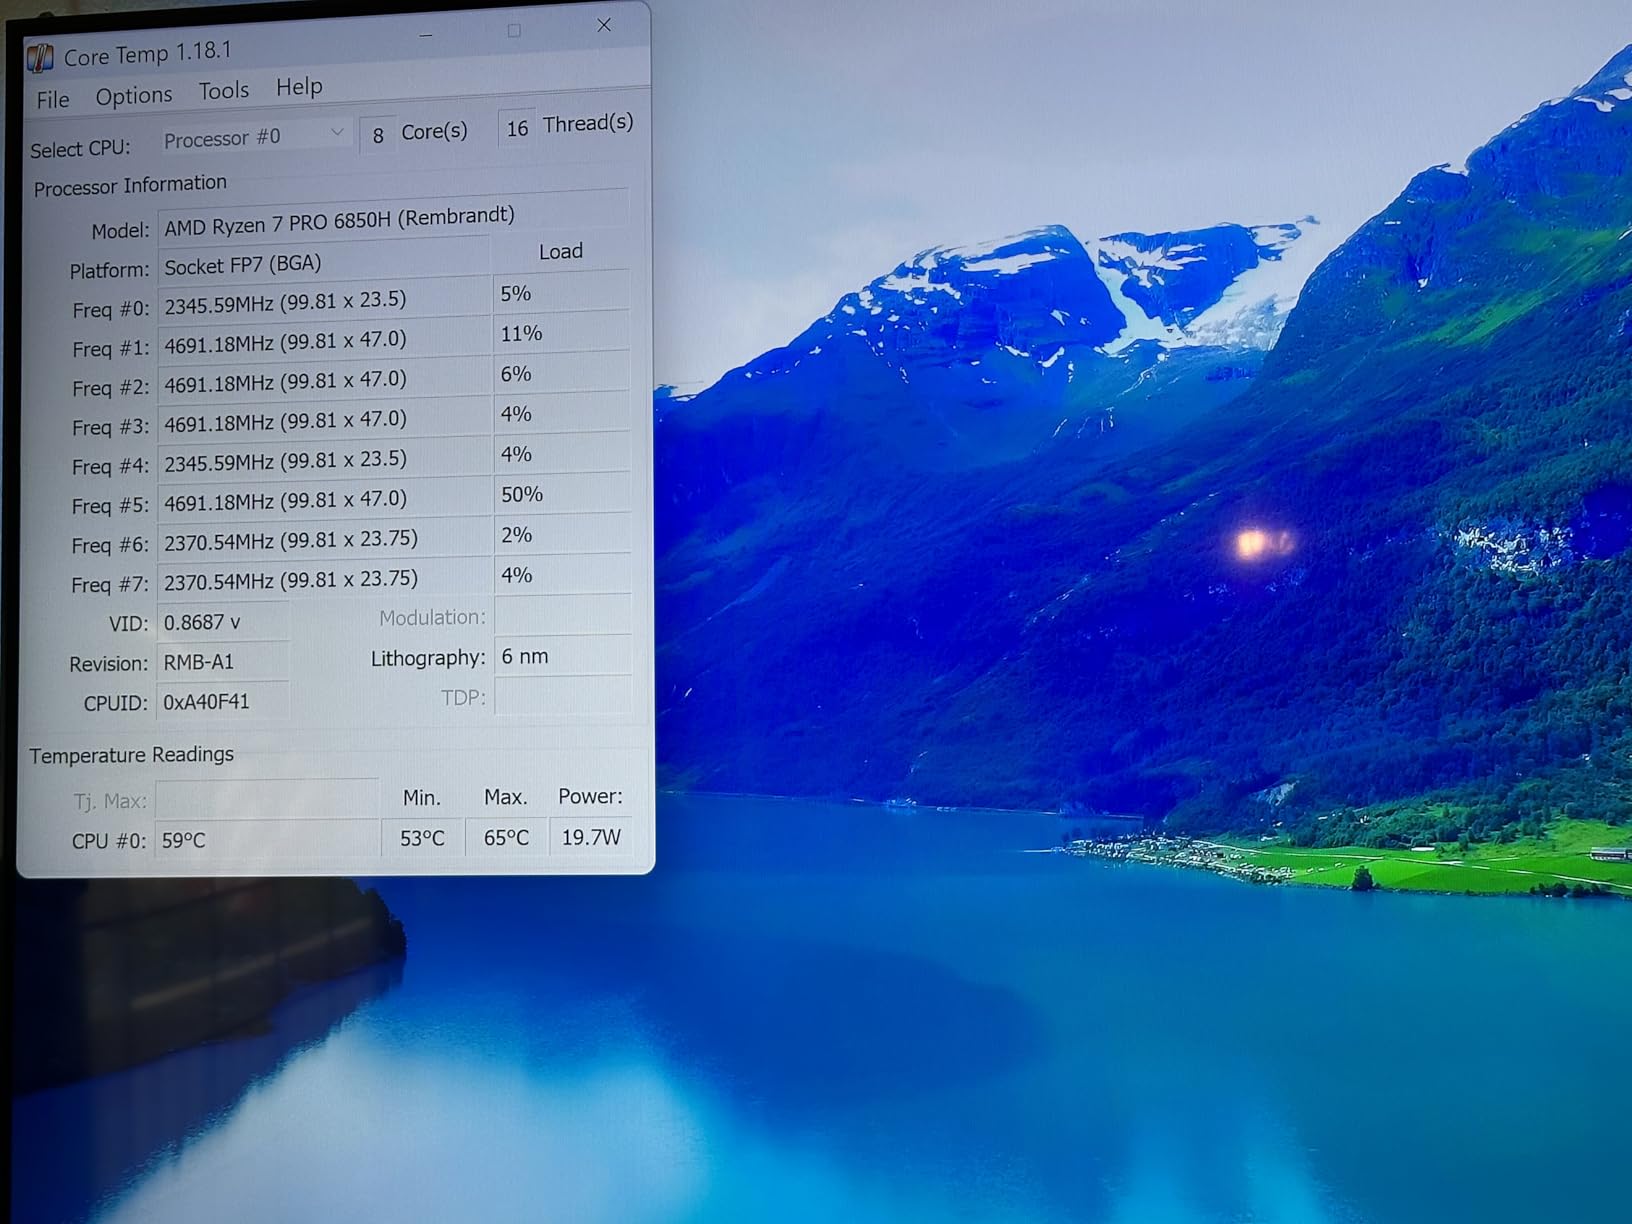
Known quirks to plan around
A MediaTek RZ616 Wi-Fi card has caused driver lockups on some units, which is an easy fix with a USB adapter but a real annoyance at two in the morning. Some users also report application crashes when pushing demanding 3D and rendering tasks.
If you are buying for a 30B-class model or any training at all, this is the wrong box. If you are serving 7B to 8B models around the clock on a power budget, it is the right one.
6. BOSGAME VTA-439 – Native OCuLink and a 256GB Memory Ceiling
- ✓ Highest satisfaction score here at 4.5 with 83 percent five-star ratings
- ✓ 86 TOPS AI with a 55 TOPS XDNA 2 NPU
- ✓ Memory expandable to 256GB the highest ceiling in this roundup
- ✓ Built-in OCuLink PCIe 4.0 x4 plus three Gen4 M.2 slots
- ✕ Fewer customer reviews than the established GEEKOM and GMKtec models
- ✕ External power adapter rather than integrated
- ✕ VESA mount included but cooling is not tower class
Ryzen AI 9 HX 470 12C/24T
86 TOPS with 55 TOPS NPU
Radeon 890M
32GB DDR5 to 256GB
The VTA-439 is the specification outlier of this group and the machine to watch. A 256GB memory ceiling is the highest documented in the roundup, and it is paired with a built-in OCuLink port at PCIe 4.0 x4 rather than an adapter card or a USB4 tunnel.
Underneath is the Ryzen AI 9 HX 470 with 86 TOPS of total AI performance, including an XDNA 2 NPU rated up to 55 TOPS, plus Radeon 890M graphics with 16 compute units clocking up to 3100MHz.
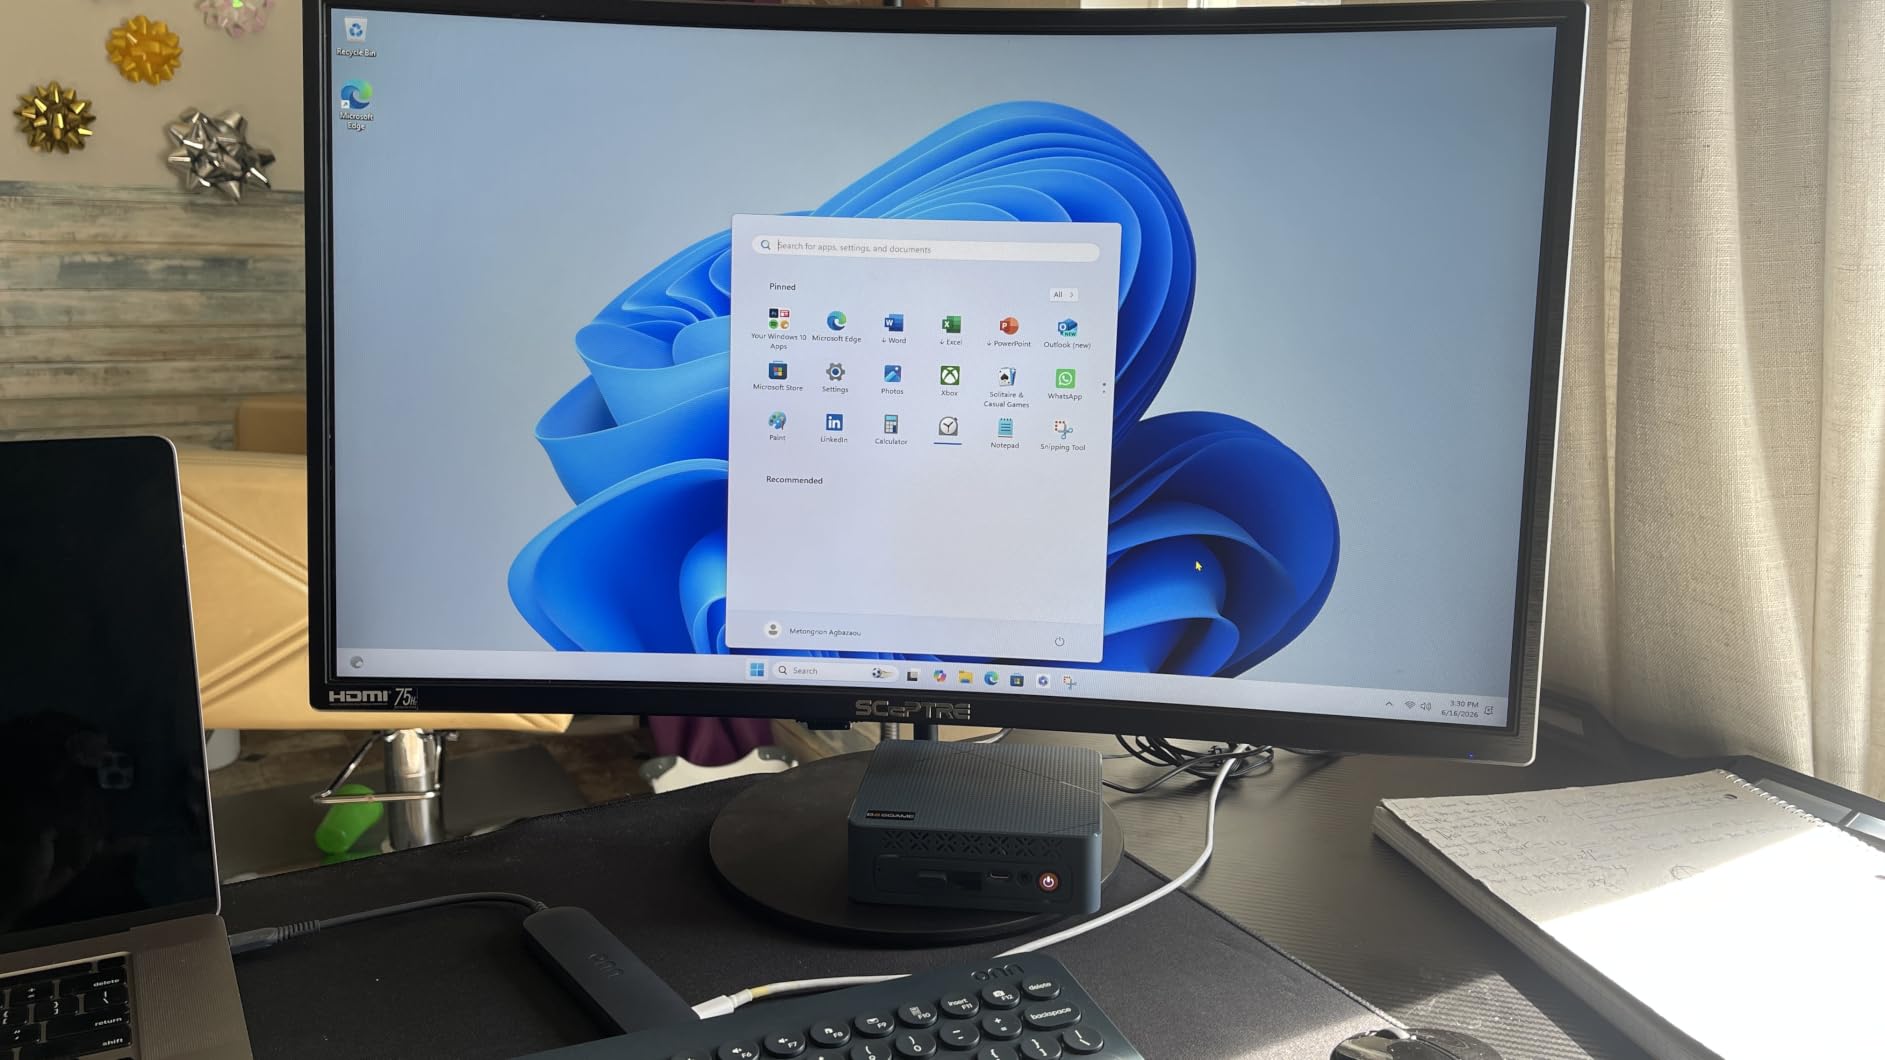
Buyers highlight the 256GB ceiling, triple Gen4 storage and the OCuLink path as exactly what an AI development and virtualization setup needs. At 54W with a 120W adapter it also stays in the low-power camp that makes 24/7 operation reasonable.
Display output is unusually thorough for the size, with HDMI 2.1 and DisplayPort 1.4 at 4K144Hz, USB4 at 8K60Hz and USB-C at 4K60Hz. A VESA mount is included, and Windows 11 Pro comes pre-installed with Ubuntu compatibility noted.
Why 256GB changes what you can attempt
At that ceiling you can hold a quantized 70B-class model with room to spare, or serve several 30B-class models concurrently from one box. That is a different category of work from running a single 7B model, and none of the other machines here can do it.
The catch is bandwidth, and the Radeon 890M is the same memory architecture as the cheaper boxes. A large model that fits will not generate tokens quickly. Image-processing users on the image.sc forum describe a Ryzen AI Max+ 395 mini PC as maybe two-thirds as capable as their NVIDIA box, and the same caution applies here.
The trust caveat on a newer brand
With 226 ratings, this has the thinnest long-term feedback of the group, and buyers specifically worry about firmware maturity and warranty support on newer brands. The review data is thinner precisely where the risk sits.
The warranty terms are decent, one year on the machine and three years on parts with lifetime technical support, but the external power adapter is a small daily irritation that integrated-adapter designs avoid.
7. MINISFORUM M1 Pro-125H – The Value Entry With OCuLink Included
- ✓ 32GB DDR5 with dual Gen4 slots and OCuLink at the entry point
- ✓ Quiet under load at about 45dB with copper heat pipes
- ✓ Dual USB4 ports deliver 40Gbps each and accept 65-100W PD-IN
- ✓ Quad display including 8K-capable DisplayPort and USB4
- ✕ Core Ultra 5 125H has no strong dedicated NPU
- ✕ OCuLink is not hot-swappable and consumes one of two M.2 slots
- ✕ Only two USB ports listed in the spec sheet
- ✕ Weakest of the multi-core options here for large model training
Core Ultra 5 125H 14C/18T
32GB DDR5-5600 to 128GB
OCuLink PCIe 4.0 x4
Under 45dB under load
The M1 Pro-125H is unusual in how much of the AI-relevant expansion it includes at the bottom of the range. The OCuLink PCIe 4.0 x4 adapter ships in the box, and memory runs to 128GB across dual SO-DIMM slots.
Buyers view it as the value entry point, praising build quality, quiet thermals and USB4 single-cable flexibility. The aluminum alloy chassis with phase-change materials, copper heat pipes and a large silent fan holds under 45dB at full load.
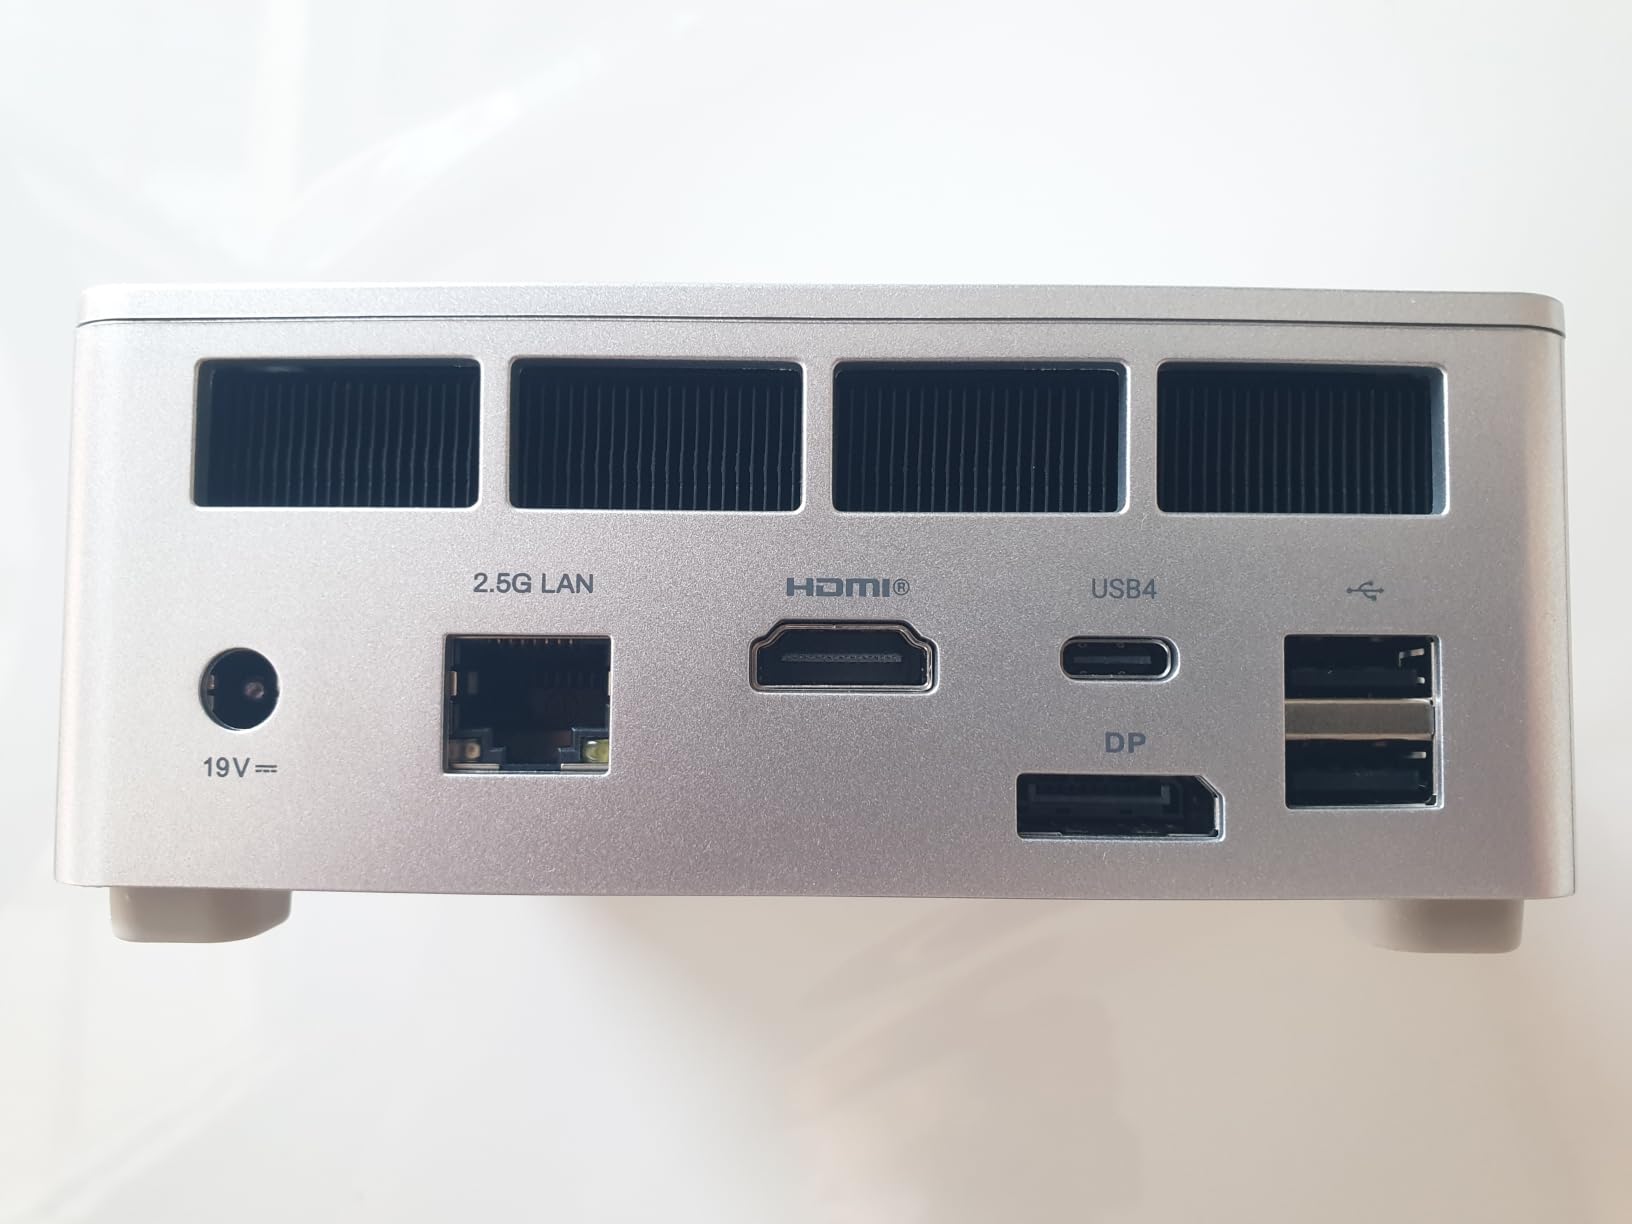
Those two USB4 ports are genuinely useful in a deep learning setup. At 40Gbps each with PD-IN up to 100W, one cable can carry data, video and power, which matters when the mini PC lives under a desk or behind a monitor.
Storage is dual M.2 2280 PCIe 4.0 slots supporting up to 4TB each, and networking is 2.5GbE with Wi-Fi 7, which is fast enough to pull datasets onto the box without dominating your workflow.
Where the Core Ultra 5 tier bites
The 125H has 14 cores and 18 threads at up to 4.5 GHz but no meaningful dedicated NPU, so everything runs on the integrated Arc graphics and the CPU. Data preprocessing, which is what a CPU is genuinely good at, is where this chip shines.
For training, it is the weakest of the multi-core options here. Use it for inference, notebook development and small transfer-learning runs, then look at the VTA-439 or the AI X1 Pro if the model gets serious.
Know the OCuLink trade-off
OCuLink is not hot-swappable and it consumes one of the two M.2 SSD slots, so adding a GPU means giving up a storage bay permanently. Plan the storage layout before you commit.
Only two USB ports are listed in the spec sheet, so a hub is usually needed for peripherals. It also means the deepest data set in the roundup, at 8TB total.
8. Apple Mac mini M4 Pro – The Quiet Metal Box With Fixed Memory
- ✓ Highest average rating here at 4.7 with 87 percent five-star ratings
- ✓ 12-core CPU and 16-core GPU handle heavy multitasking and code compilation
- ✓ Silent under load at a five-inch square footprint
- ✓ Unified memory lets the GPU access the full 24GB pool for local model work
- ✕ Only three Thunderbolt ports and a single HDMI on this configuration
- ✕ 24GB unified memory is not user-upgradeable
- ✕ 512GB SSD is small for model weight files and datasets
- ✕ Non-Apple peripherals often need third-party software
M4 Pro 12-core CPU 16-core GPU
24GB unified memory
512GB SSD
5 by 5 by 2 inches
The Mac mini is the outlier in this roundup and the machine owners are most attached to. It carries the highest satisfaction score of the group at 4.7 stars with 87 percent five-star ratings, and a meaningful share of buyers converted from Windows specifically because of it.
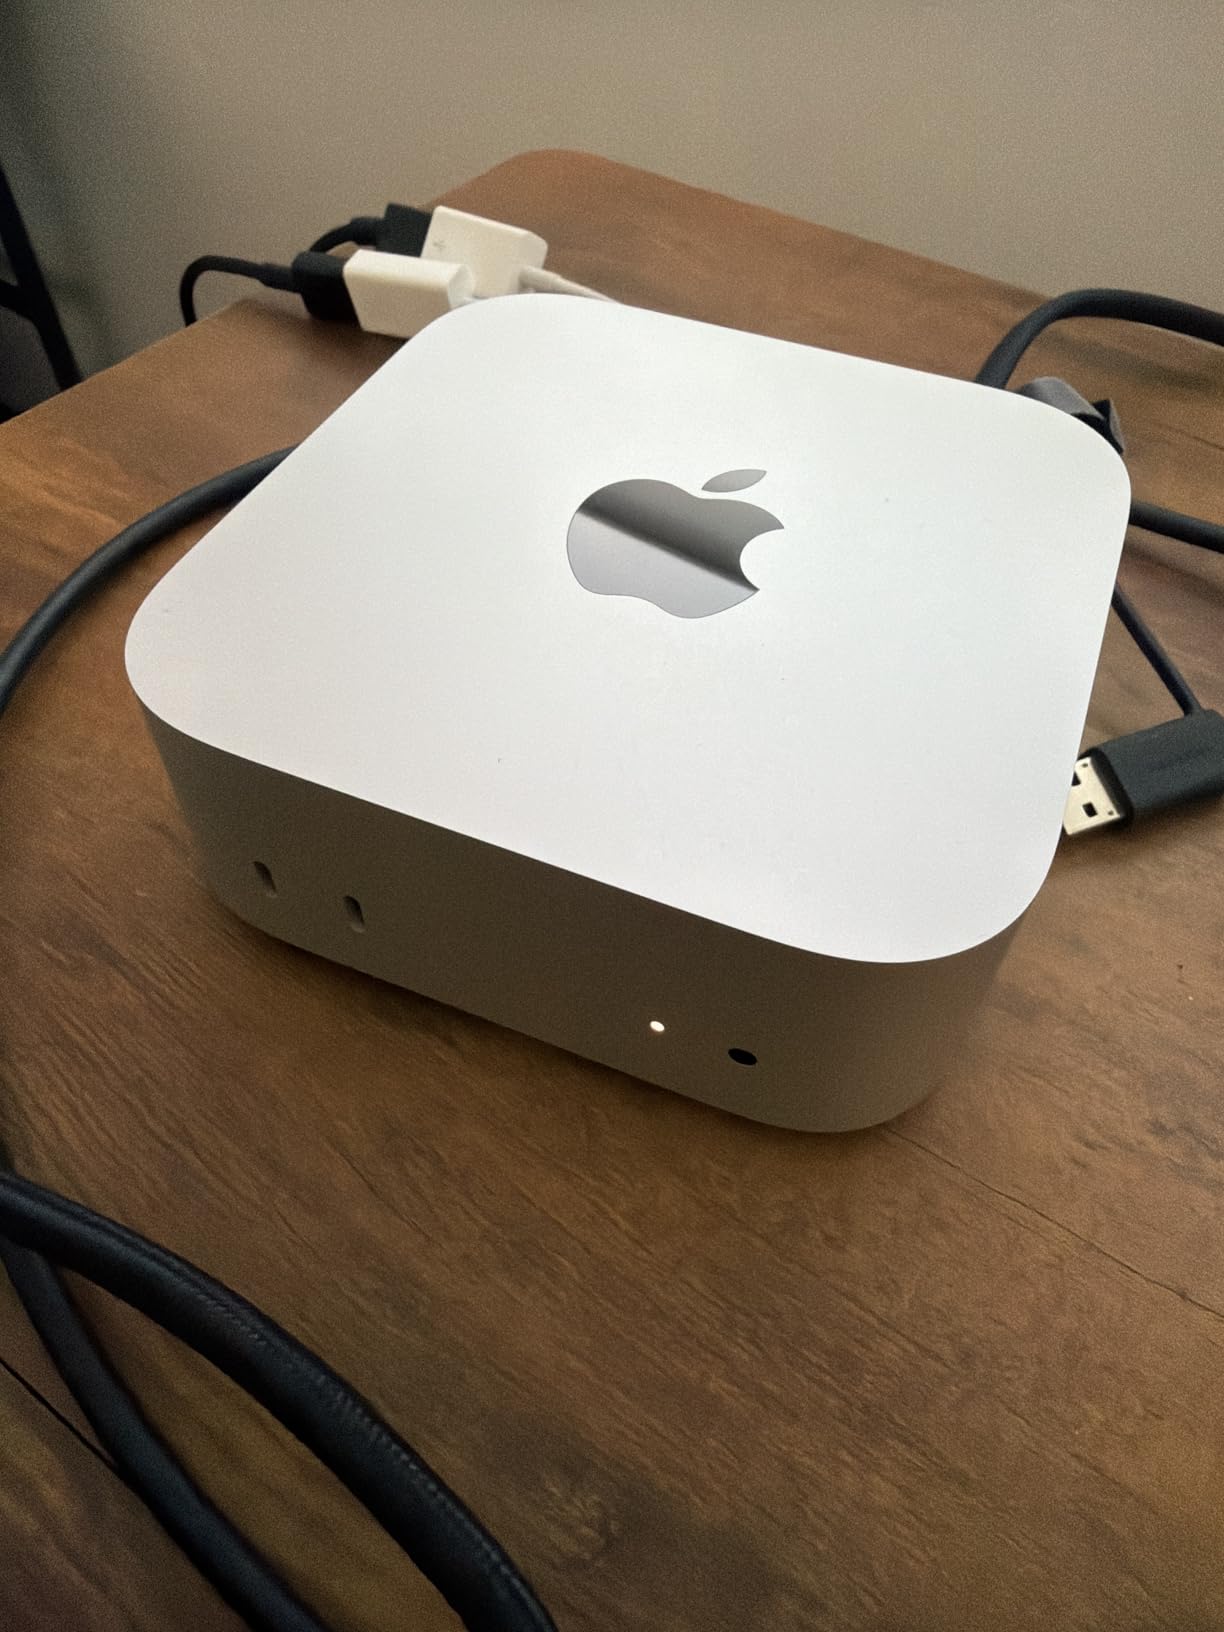
The M4 Pro pairs a 12-core CPU with a 16-core GPU across a 24GB unified memory pool, in a 5 by 5 by 2 inch chassis weighing 1.6 pounds. It is completely silent under load, which no fan-cooled box in this list can match.
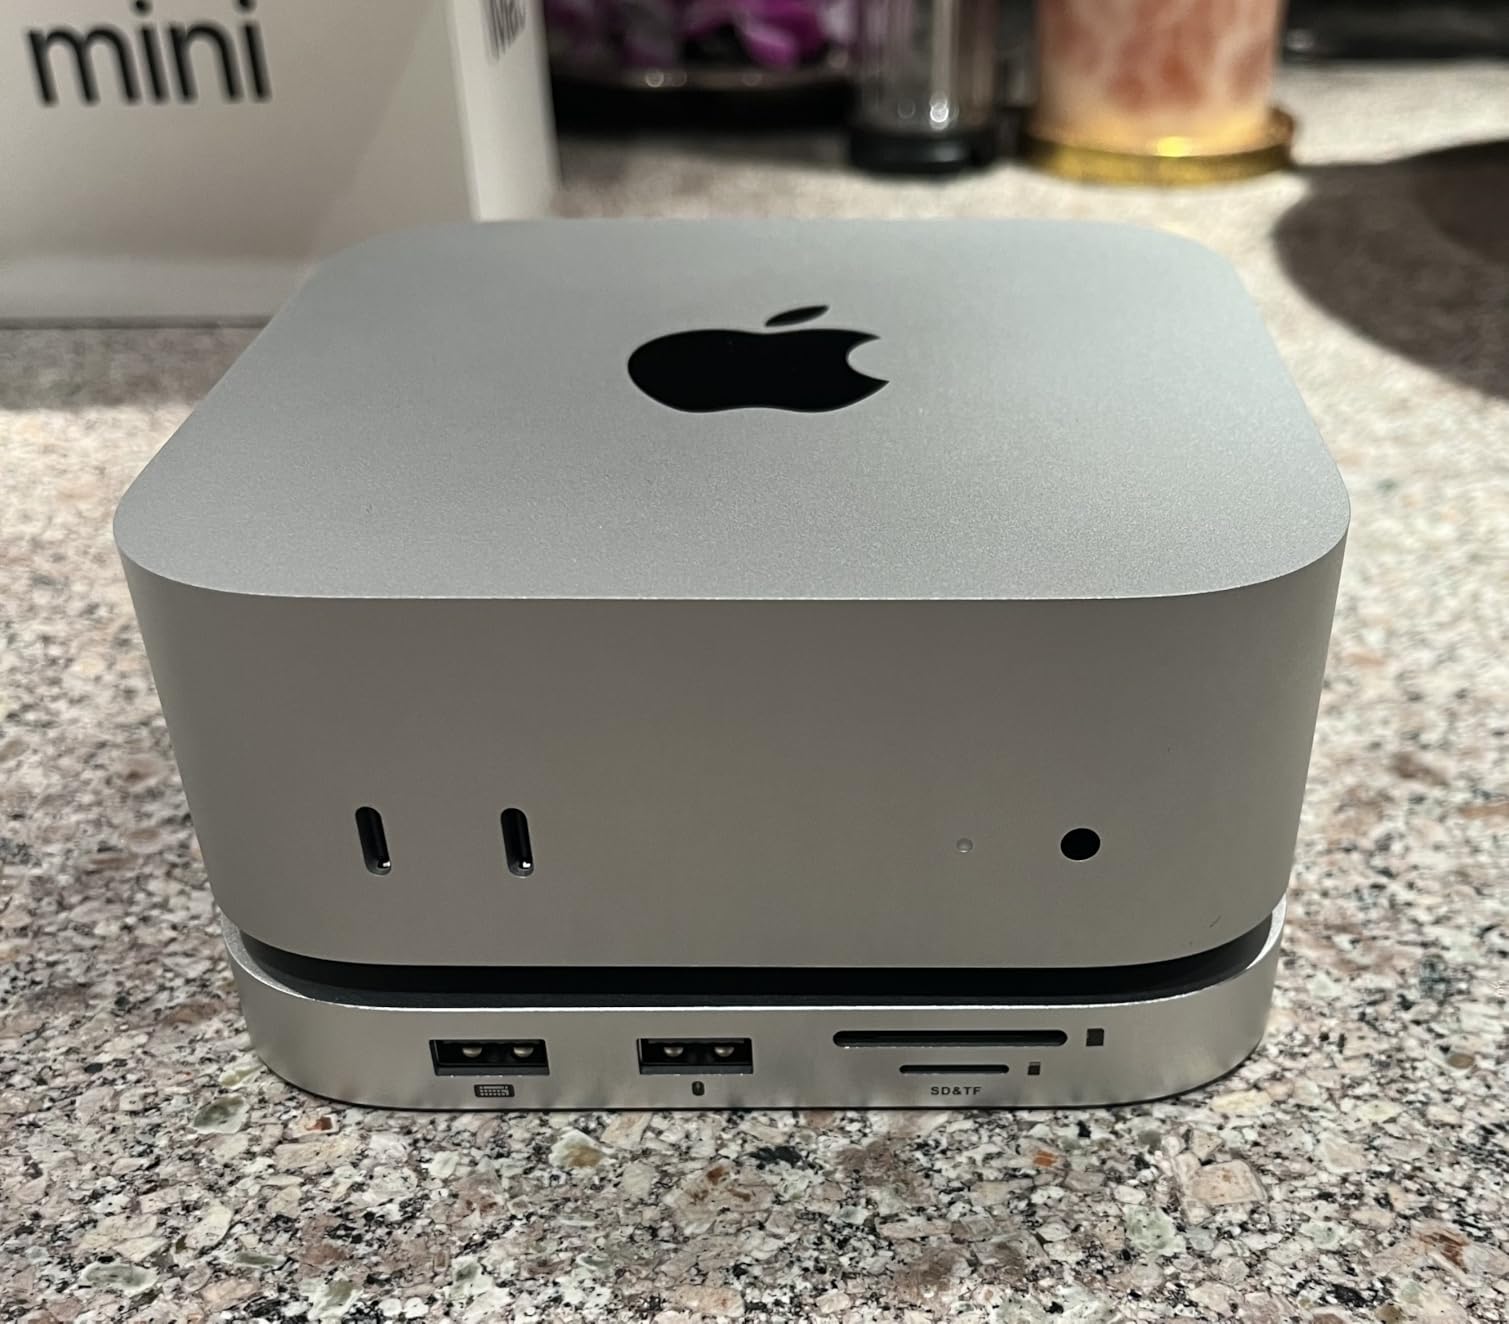
Unified memory is the architectural advantage. CPU and GPU address the same pool, so the GPU can use all 24GB rather than a fixed VRAM slice, and owners use that headroom for local model work that would not fit in a comparable discrete card.
What you give up is the framework ecosystem. PyTorch on Metal exists and works, but CUDA-specific code, cuDNN operators and most production tooling do not exist here. The fast.ai community has long argued for a dedicated tower for training rather than any small-form-factor machine.
24GB is a hard ceiling
Unified memory on Apple Silicon is soldered, and buyers cite that as the single biggest limitation for local AI work. You cannot add 8GB of extra memory to make a model fit, and there is no equivalent of the 96GB pools in the AMD boxes.
The 512GB SSD compounds it. Model weight files at multiple quantizations plus a working dataset run out of room quickly, and external storage does not help if your loader expects a local NVMe device.
Ports, peripherals and the learning curve
This configuration carries three Thunderbolt ports and a single HDMI, which is tight for multi-monitor setups. Non-Apple peripherals often need third-party display or driver software, and macOS has a real learning curve for new users.
r/MiniPCs members chasing local AI regularly ask whether a higher-memory mini PC can beat a Mac mini while staying small and low-power. The answer depends entirely on whether your model fits in 24GB.
How to Choose a Mini PC for Deep Learning
Deep learning is a memory-bound workload before it is a compute-bound one. The model weights have to live in fast memory on every single training step and on every generated token, and that single fact explains almost every purchasing decision in this category. Here is the order I would evaluate specs in.
1. Memory capacity decides whether your model loads at all
Nothing else matters if the weights do not fit. A model that needs 30GB will not load on a 24GB card no matter how fast the card is, and this is the single most common failure buyers describe when they upgrade.
Sizing rule of thumb: a 7B to 13B model at Q4 quantization needs roughly 8GB to 10GB of weights, a 30B class needs around 20GB, and a 70B class pushes past 40GB. Add headroom for the KV cache, which grows with context window, and for your operating system.
This is why 96GB configurations exist. If you want headroom to move up model sizes without replacing the machine, the 96GB box is buying you time rather than speed.
2. Memory bandwidth decides tokens per second
Once it loads, bandwidth sets the pace. DDR5-5600, DDR5-4800 and Apple’s unified memory sit in very different places on this curve, and the difference is visible in generation speed long before it is visible in load time.
This is the spec nobody puts on the sticker, and the reason forum buyers cross-check measured token figures instead of trusting TOPS numbers. A larger number of TOPS does not compensate for slow memory.
3. Graphics architecture decides which frameworks you can run
RDNA 3.5 in the Radeon 890M, Intel Arc 140T in the Core Ultra boxes, and Apple GPU cores in the Mac mini are three different software worlds. The Intel parts are weakest for anything beyond inference, and the 13 TOPS NPU on those machines does not change that.
Storage matters more than most buyers expect too. Three M.2 2280 PCIe 4.0 slots, as on the T1 AI and the K15, let you keep checkpoints and multiple quantizations on fast local NVMe rather than a network drive.
4. The software stack: CUDA, ROCm and Metal in practice
NVIDIA CUDA with cuDNN and PyTorch is the only mature training stack, and none of the eight machines here has an NVIDIA GPU. That is the honest headline of this roundup: you are choosing an inference platform, and adding a discrete card later is the only route to CUDA.
AMD’s ROCm path on RDNA 3.5 works but is narrower, with fewer supported distributions and more manual setup. Apple’s Metal path via PyTorch is well supported for inference and increasingly capable for fine-tuning. Linux driver installation is consistently named as the biggest time sink on all three platforms by people setting these up headless.
5. Thermal headroom decides whether peak speed survives an hour
A mini PC cooler cannot sustain boost clocks through a multi-hour job the way a tower can, and this is the most repeated pain point across the r/MiniPCs discussions we reviewed. Benchmarks taken in the first ten minutes are not the numbers you will live with.
Look for published sustained-load noise figures rather than idle ones. Under 35dB on the IT15 AI and roughly 45dB on the AI X1 Pro and M1 Pro are useful numbers; anything that goes hot to the touch under load, like the plastic K15, will not hold its boost for a long inference run.
6. The upgrade path decides how long the box stays relevant
Soldered memory is a one-way door. The Mac mini’s 24GB cannot change, and buyers cite that as the main reason to skip it for local model work. Every other machine here uses socketed SO-DIMMs, though ceilings vary from 96GB to 256GB.
Watch the OCuLink implementation closely. A native port costs nothing, an adapter card costs you an SSD slot, and a USB4 tunnel costs you bandwidth. Then check whether two memory slots means a dual-channel configuration you should populate with matched modules.
When a Mini PC Is the Wrong Machine for Deep Learning
There are four situations where I would tell you not to buy any of these.
First, if you are training a large model from scratch rather than fine-tuning one. That work needs multiple GPUs, high-bandwidth interconnects and a full tower with proper cooling, and the fast.ai community has argued this for years. Our 15 best professional GPU workstations guide covers that tier properly.
Second, if you need CUDA and cannot add a discrete card. The OCuLink machines here make it possible, but once you are buying a graphics card and a desktop to hold it, the case for a mini PC weakens considerably.
Third, if your model is larger than about 24GB and you want it fast. A large model that fits will still be bandwidth-limited, and a cluster of two mini PCs over Thunderbolt is almost always slower and more expensive than a single desktop. If you are considering running several as a home server, our mini PC roundup for Proxmox is the better read.
Fourth, if you need quiet 24/7 operation in a living space. The only genuinely silent option here is the Mac mini; every other box is fan-cooled. Our fanless mini PC guide covers machines built for silence, though they are rarely the right choice for AI work.
Frequently Asked Questions
Are mini PCs good for AI?
They are good for local AI inference, fine-tuning and small-scale training, but not for training a large model from scratch. A mini PC is a good AI machine when the model fits in system memory and the workload is serving, quantised inference, LoRA adapter work or coursework-scale training. It is a poor choice when you need CUDA, multiple GPUs or high-bandwidth interconnect, because mini PCs ship with integrated or Apple graphics rather than discrete NVIDIA cards.
Which mini PC is best for AI development?
For most developers, the GMKtec T1 AI is the strongest all-round pick: a 16-core Core Ultra 9 285H, a socketed 32GB DDR5-5600 configuration expandable to 96GB, three M.2 2280 PCIe 4.0 slots and a native OCuLink port for adding a discrete GPU later. If you already have memory covered, a 96GB configuration such as the MINISFORUM AI X1 Pro holds far larger models out of the box.
What is the best PC for AI and machine learning?
For training, the honest answer is a tower workstation or server with discrete NVIDIA GPUs, because CUDA and cuDNN remain the only mature training stack. A mini PC is a strong companion machine for data preparation, notebooks, inference serving and fine-tuning, and it wins on power draw, size and cost. If you already own a training machine, an always-on mini PC for serving is the highest-value addition.
What mini PC is best for running local LLMs?
Memory capacity is the deciding spec, because a model that does not fit will not load at all. A 7B to 13B model at Q4 quantization needs roughly 8GB to 10GB of weights, a 30B class model needs around 20GB, and a 70B class model needs more than 40GB. A 96GB machine such as the MINISFORUM AI X1 Pro holds models no 24GB discrete card can hold, while the 24GB Mac mini M4 Pro is limited to smaller quantisations.
How much RAM do I need for deep learning?
Budget roughly four bits of memory per parameter at Q4 quantization, then add headroom for the KV cache and your operating system. That works out to about 8GB to 10GB for a 7B to 13B model, around 20GB for a 30B class model and more than 40GB for a 70B class model. If you plan to move up model sizes later, buy the higher memory tier now, because soldered memory cannot be replaced.
Do I need a GPU for deep learning?
For serious training, yes, and it needs to be an NVIDIA GPU for CUDA. None of the eight mini PCs here ships with a discrete NVIDIA card, so all of them rely on integrated AMD or Intel graphics or Apple Metal, which are inference-strong and training-hostile. The OCuLink-equipped models in this roundup, including the GMKtec T1 AI and the BOSGAME VTA-439, let you add a discrete card later, though a USB4 tunnel costs you bandwidth.
What is the downside to a mini PC for AI work?
The main downsides are thermal throttling under sustained AI load, soldered memory on several models, no full-length PCIe x16 slot, and a limited software story because there is no CUDA. Mini PC coolers cannot sustain boost clocks through a multi-hour training or inference job the way a tower can, and a USB4 eGPU tunnel costs a meaningful share of the GPU’s peak throughput. Buyers who cluster two mini PCs for training usually find it slower and pricier than one desktop.
Does an NPU TOPS rating mean faster AI?
Not necessarily. NPU TOPS figures describe a dedicated block that accelerates specific on-device tasks, while mainstream local tools such as Ollama, LM Studio and llama.cpp still lean primarily on the CPU and integrated GPU. The GMKtec T1 AI and K15 have 13 TOPS NPUs and still run quantized models perfectly well, because their workload runs elsewhere. Compare measured tokens per second rather than TOPS when choosing between machines.
Final Verdict: The Best Mini PCs for Deep Learning in 2026
If you want the single best mini PC for deep learning, take the GMKtec T1 AI. Its 829 ratings give it more proven reliability than anything else here, the OCuLink port at PCIe x4 is the cleanest upgrade path on the list, and three M.2 2280 slots give you room for the datasets and checkpoints that a deep learning setup generates quickly.
If model size is your binding constraint rather than speed, the MINISFORUM AI X1 Pro with 96GB is the pick, since it holds weights that no 24GB discrete card can hold. If you are running containers and virtual machines more than models, the GEEKOM IT15 AI is quieter and better connected.
For a 24/7 headless inference node on a power budget, the GMKtec NucBox K15 runs at 35W and has been measured by owners running quantised models under Ollama. For a machine that grows into whatever you need next, the BOSGAME VTA-439 with a 256GB ceiling and a built-in OCuLink port is the one to watch. And if silence is non-negotiable, only the Mac mini M4 Pro delivers it, at a fixed 24GB you have to plan around.
None of these trains a frontier model, and the honest way to read this list is as a serving and experimentation tier. For from-scratch training at scale, the answer is still a GPU workstation, not a mini PC.

