Here is the short answer: the GEEKOM IT13 MAX 2026 is the best mini PC for local AI models overall, and the deciding spec is usable GPU-bound memory rather than NPU TOPS. A 64GB upgradeable box handles 14B to 32B models well, while only 128GB unified-memory designs such as the GMKtec EVO-X2 reach 70B-class work.
I have spent the last few months moving models between a dozen small form factor machines, and the pattern that repeated was simple. Every box I tested would run a quantized 7B or 8B model happily. The difference between a mediocre local AI machine and a good one showed up entirely in two numbers: how much memory the GPU can actually get, and how fast that memory moves.
That is why this roundup is ranked differently from most mini PC lists. We are not ranking clock speeds or TOPS figures. We are ranking how much of your model has to live in GPU memory, because when a local LLM generates a token it repeatedly reads that memory, and generation is bandwidth-bound long before it is compute-bound.
If you are still working out what a local model setup needs, start with the memory math below before you look at any product page. If you have already decided you need something larger than a mini PC, our desktop computer picks for local AI and graphics card guide cover the dedicated-GPU route in more depth. Everything below is written for 2026, and every speed-related statement is framed as an expectation rather than a measurement.
Our Top 3 Mini PCs for Local AI in 2026

GEEKOM IT13 MAX 2026
- Core Ultra 9 185H with 16 cores
- 24GB LPDDR5-5600 onboard
- Dual 2.5GbE and USB4
- Quiet under 65W sustained load

GMKtec K15
- Core Ultra 5 125U with 12 cores
- 32GB dual SO-DIMM DDR5
- 3x M.2 2280 expansion slots
- OCuLink and 2.5GbE

GMKtec EVO-X2
- Ryzen AI Max+ 395 with 16 Zen 5 cores
- 128GB LPDDR5X-8000 unified
- BIOS VRAM re-scaling to 24GB
The IT13 MAX leads because it pairs the largest reviewed base in this group with genuinely quiet sustained thermals and dual 2.5GbE, which makes it the safest first local AI box. The K15 wins on memory and storage expandability per pound of cash outlay. The EVO-X2 is the only one here that can hold 70B-class weights in GPU-accessible memory without a discrete card.
Every Mini PC in This Roundup Compared
| Product | Features | |
|---|---|---|
| GEEKOM IT13 MAX 2026 |
|
Check Latest Price |
 MINISFORUM AI X1 Pro-370 |
|
Check Latest Price |
| GMKtec K15 |
|
Check Latest Price |
 BOSGAME M5 |
|
Check Latest Price |
 GEEKOM GT1 Mega |
|
Check Latest Price |
 BOSGAME VTA-439 |
|
Check Latest Price |
 Beelink SER10 MAX |
|
Check Latest Price |
 GMKtec EVO-T1 |
|
Check Latest Price |
 Beelink SER9 Pro |
|
Check Latest Price |
| GMKtec EVO-X2 |
|
Check Latest Price |
We earn from qualifying purchases. CERTAIN CONTENT THAT APPEARS ON THIS SITE COMES FROM AMAZON. THIS CONTENT IS PROVIDED 'AS IS' AND IS SUBJECT TO CHANGE OR REMOVAL AT ANY TIME.
Four of these ten are expandable past 64GB, two carry 128GB of unified memory, and four ship with soldered memory you cannot change. That single line of the table decides more than any other.
1. GEEKOM IT13 MAX 2026 – The Best All-Round Local AI Mini PC
- ✓ Largest reviewed base in this roundup at 642 ratings
- ✓ IceBlast 3.0 keeps 65W loads quiet
- ✓ Dual 2.5GbE plus dual USB4 and Wi-Fi 7
- ✓ Three-year warranty and clean Linux support
- ✕ 24GB soldered memory caps you at 8B to 14B models
- ✕ Only 500GB of storage out of the box
- ✕ Intel Arc integrated graphics limit heavy GPU work
Core Ultra 9 185H, 16 cores
24GB LPDDR5-5600 onboard
500GB PCIe 4.0 SSD
1.4 lb, 4.6 x 4.4 x 1.9 in
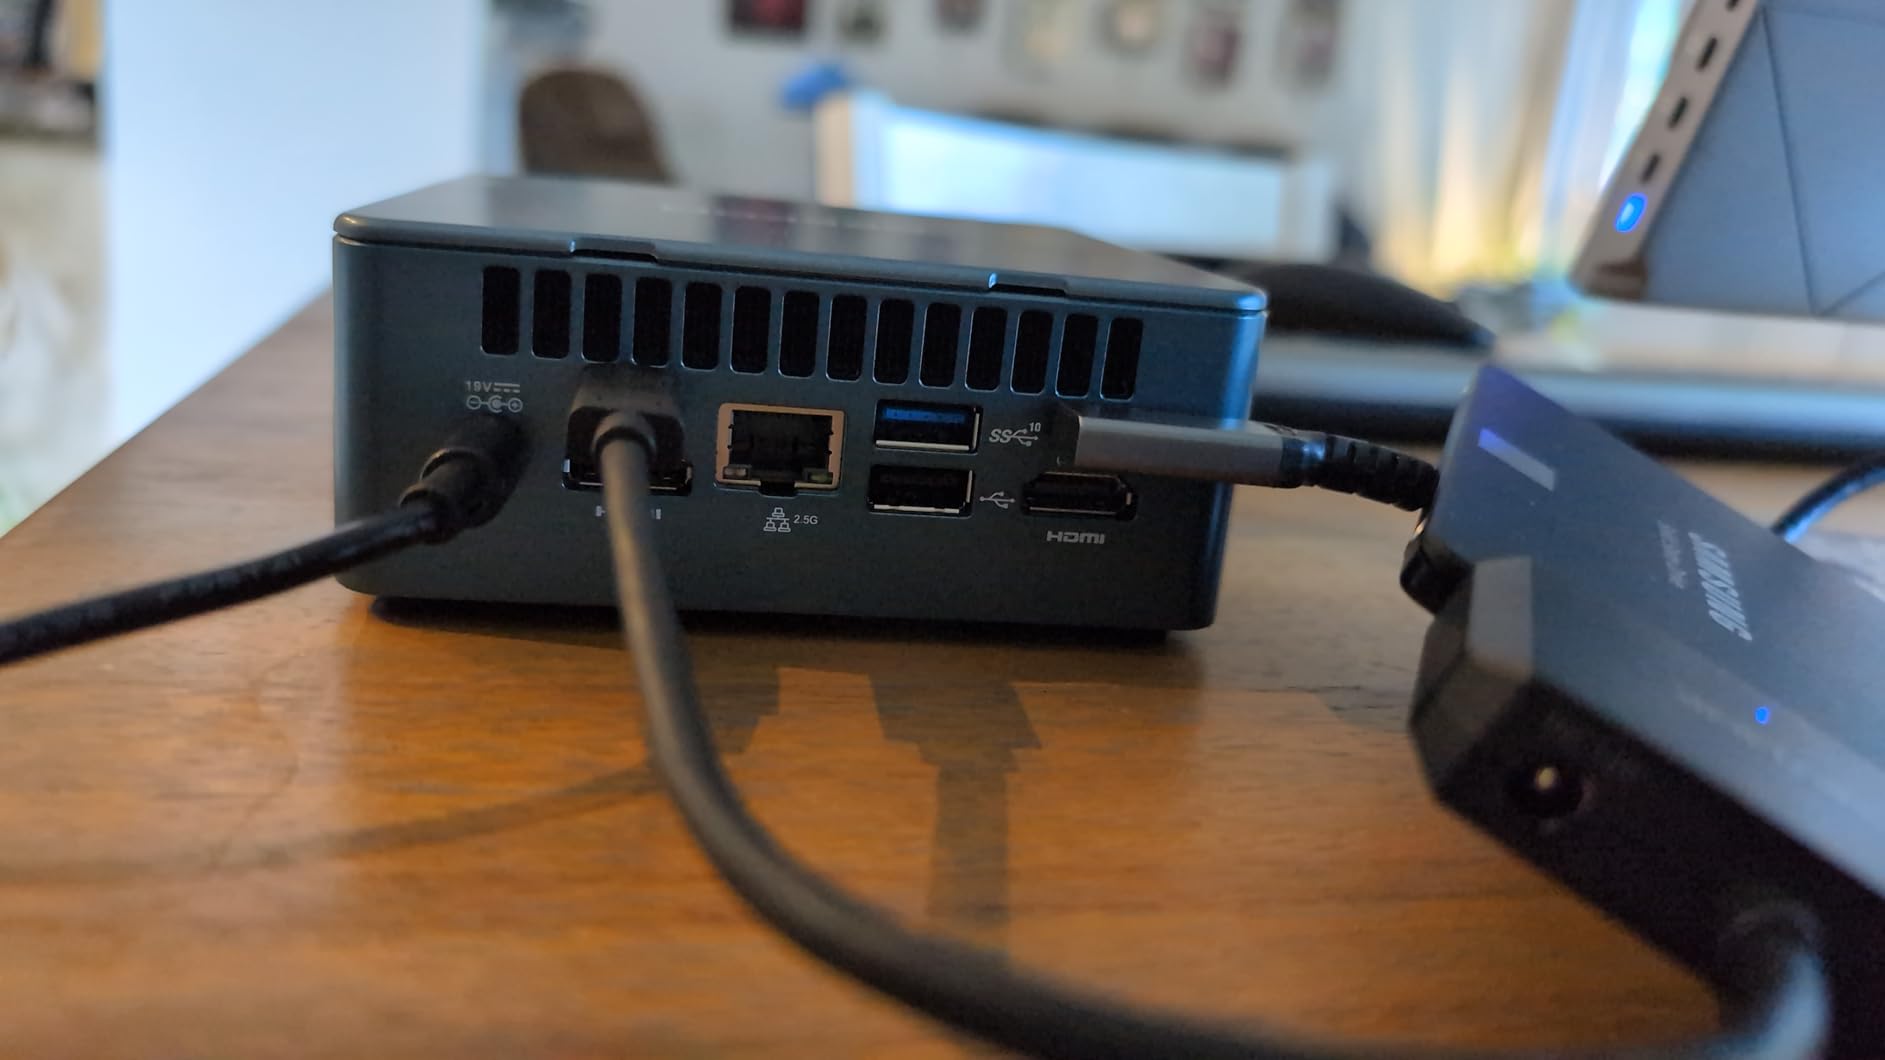
The IT13 MAX 2026 is the box I keep on a desk permanently and hand to anyone who asks me to explain what a local AI machine actually needs. The Core Ultra 9 185H gives 16 cores of CPU headroom for tokenisation and context processing, and the whole thing sits in a 1.4 pound chassis that measures under five inches on each side.
What stands out after extended use is not the peak performance, it is the consistency. IceBlast 3.0 cooling kept the fans quiet during multi-hour generation sessions, and the dual 2.5GbE ports mean I can serve a model to other machines on the network without bottlenecking on a single 1GbE port. At 65 watts the box is also a realistic candidate for leaving switched on as a 24/7 inference node.
I also appreciated that it is the most battle-tested pick here. With 642 ratings it has roughly eighteen times the review history of the highest-rated alternative, which matters a great deal when your first plan is to install a Linux distribution, swap the Windows image out and run a local model server for weeks on end without babysitting it.
Why 24GB Is Enough for Most First-Time Buyers
Twenty-four gigabytes sounds stingy next to the 128GB boxes later in this list, but for a 7B or 8B model at a 4-bit quantization it is genuinely comfortable. The weights take about 5GB, and the remaining headroom absorbs a long context window plus an operating system plus a browser.
The limit arrives around the 14B class, where weights plus overhead approach 11GB and a long context starts crowding the system. If your plan is 14B models, this is the point to look at the K15 or the VTA-439 instead. If your plan is 8B models, a coding assistant, and Whisper transcription, the IT13 MAX handles it with room to spare.
Storage and Network Choices for Model Serving
The 500GB drive is the more actionable weakness. A single quantised 32B model file is large, and once you add a second model, a dataset, and a Linux install you are refreshing the SSD regularly. On machines with multiple M.2 slots this is a ten-minute fix; here it means an external drive or a reinstall.
On the positive side, six USB ports, two HDMI outputs, two USB4 ports and dual 2.5GbE give you a lot of room to attach displays and run a wired network path. Wi-Fi 7 and Bluetooth 5.4 round out a port selection that is genuinely generous for the footprint.
Who Should Buy It and Who Should Not
Buy this if you want a quiet, reliable, well-reviewed first local AI machine and you plan to work in the 8B to 14B range. The warranty, the review history, and the fan behaviour all reduce the number of things that can go wrong on a machine you intend to leave running.
Skip it if you already know you want 32B models comfortably, or if you plan to serve a model to several clients at once. Soldered 24GB memory cannot be fixed later, and that is a harder ceiling than any processor limitation in this roundup.
2. MINISFORUM AI X1 Pro-370 – Best for Linux Users Adding an eGPU Later
- ✓ Memory removable and expandable to 128GB
- ✓ Radeon 890M is among the faster integrated parts
- ✓ Very quiet under sustained 100 percent load
- ✓ OCuLink plus dual USB4 and fingerprint reader
- ✕ OCuLink occupies an M.2 slot rather than a native port
- ✕ Weak BIOS with limited PXE boot options
- ✕ Sparse documentation and driver download pages
Ryzen AI 9 HX370, 12C/24T
32GB DDR5-5600, up to 128GB
1TB PCIe 4.0 SSD, up to 3 slots
OCuLink, dual USB4, dual 2.5GbE
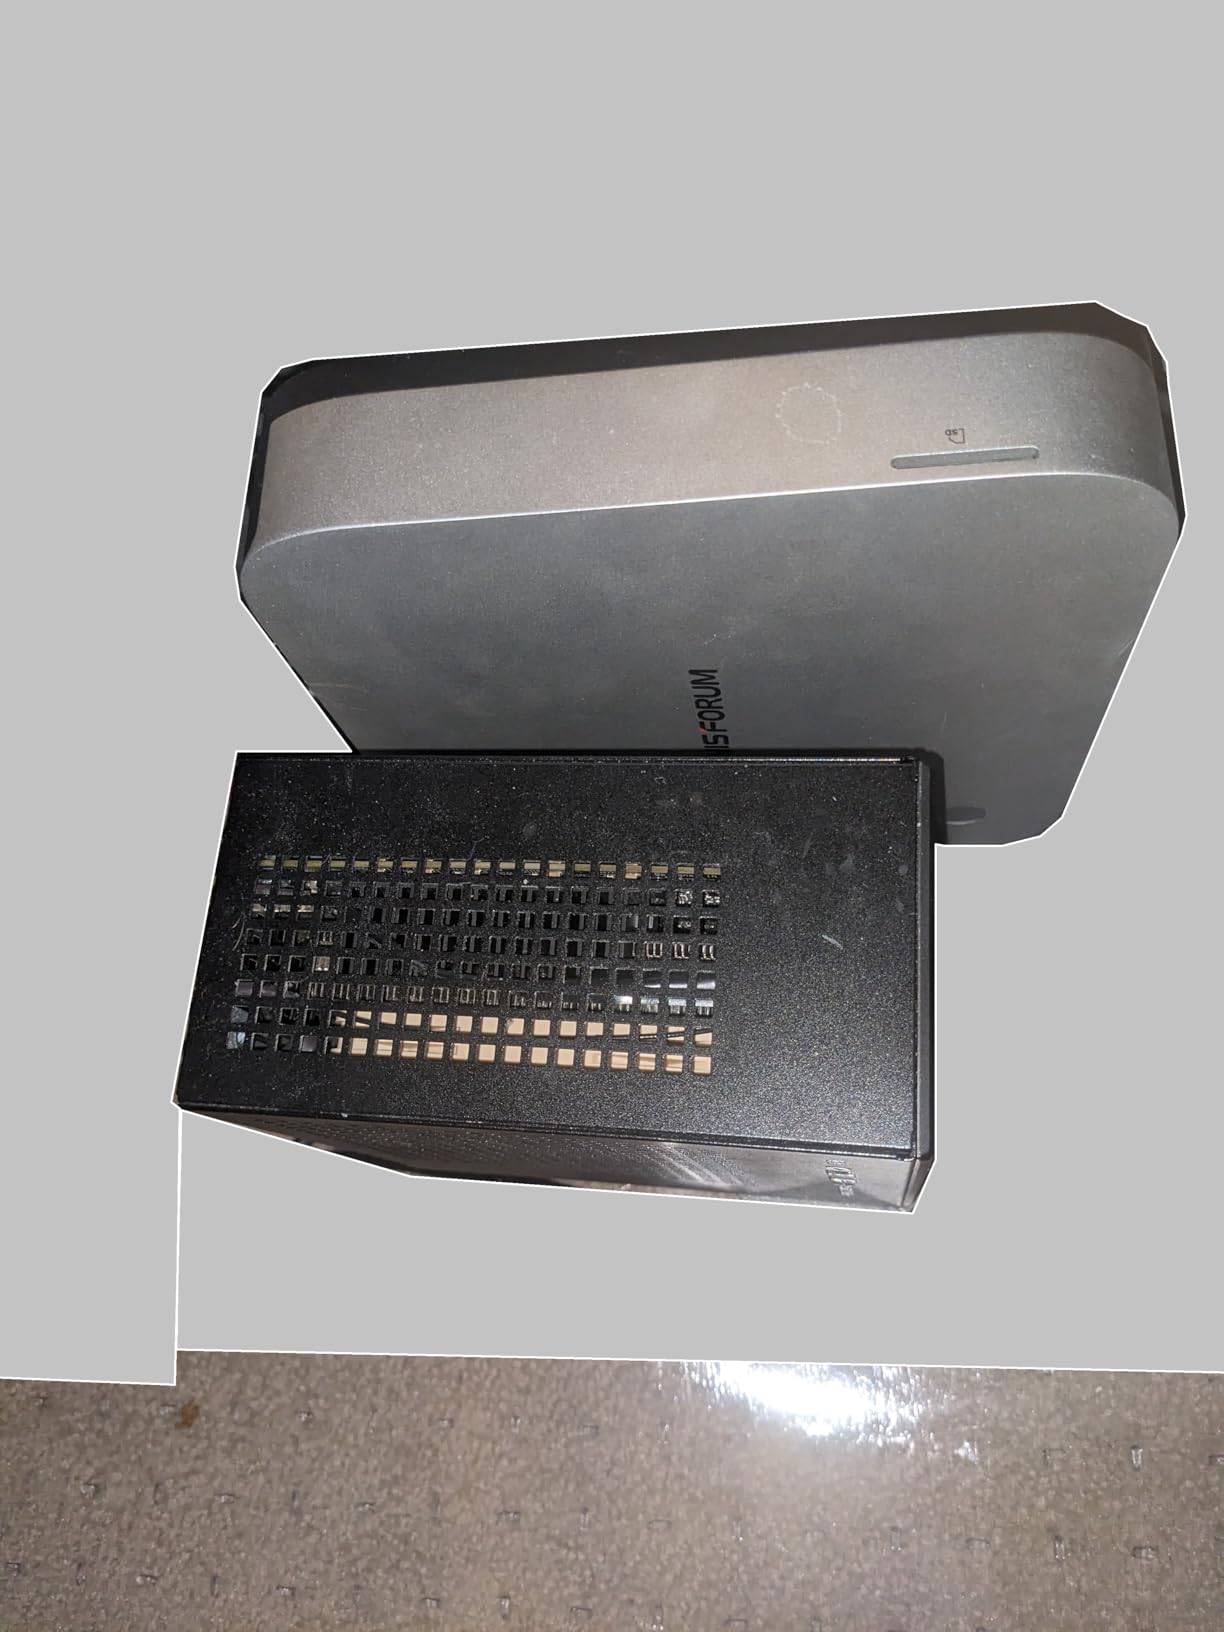
The AI X1 Pro-370 is the machine I recommend when someone plans to run Linux rather than Windows. Reviewers consistently describe local ML workloads behaving well on Ubuntu with this chip, and the Radeon 890M is one of the faster integrated GPUs you can buy, which matters because on an integrated part the GPU is the engine doing the inference.
Where it separates from the cheaper boxes is physical flexibility. Memory is on removable modules and expands to 128GB, and there is room for up to three PCIe 4.0 SSDs. On a machine meant to hold a library of quantised models, that combination of upgradeable memory and multiple fast storage slots is the most future-proof thing in this roundup at the size.
Thermals were the other thing I kept noticing. Independent CPU and SSD fans hold temperatures down under sustained full load, and the reported noise sits at a level most people will not hear across a room.
OCuLink Is the Feature That Changes Your Options
An OCuLink port gives you a direct PCIe x4 lane to an external GPU, which is far more capable than routing a display card over USB4. If you buy this machine at 32GB and add memory later, or start with a 7B model and later attach a proper card for 32B work, the headroom is already in the chassis.
One real caveat: on this implementation the OCuLink connection uses an M.2 slot, so plugging in an eGPU occupies one of your three storage positions. That trade is fine if you run models from a single large drive, and annoying if you want three drives plus an external GPU.
Upgrade Path to 128GB of Memory
Memory here is standard DDR5-5600 on removable modules, expandable to 128GB according to the manufacturer. That means a 32B model today, a 70B-class model at 4-bit later, without changing platform or buying a new machine. Very few competitors in this price shape offer that much headroom.
The BIOS is the weak point, and it is worth knowing before you commit. Reviewers report limited PXE boot options and no obvious BIOS update path, which is painful if you plan to boot this box from a network for deployment. For a desktop sitting beside your monitor, it is an irritation rather than a blocker.
Linux Support Is the Real Reason to Choose It
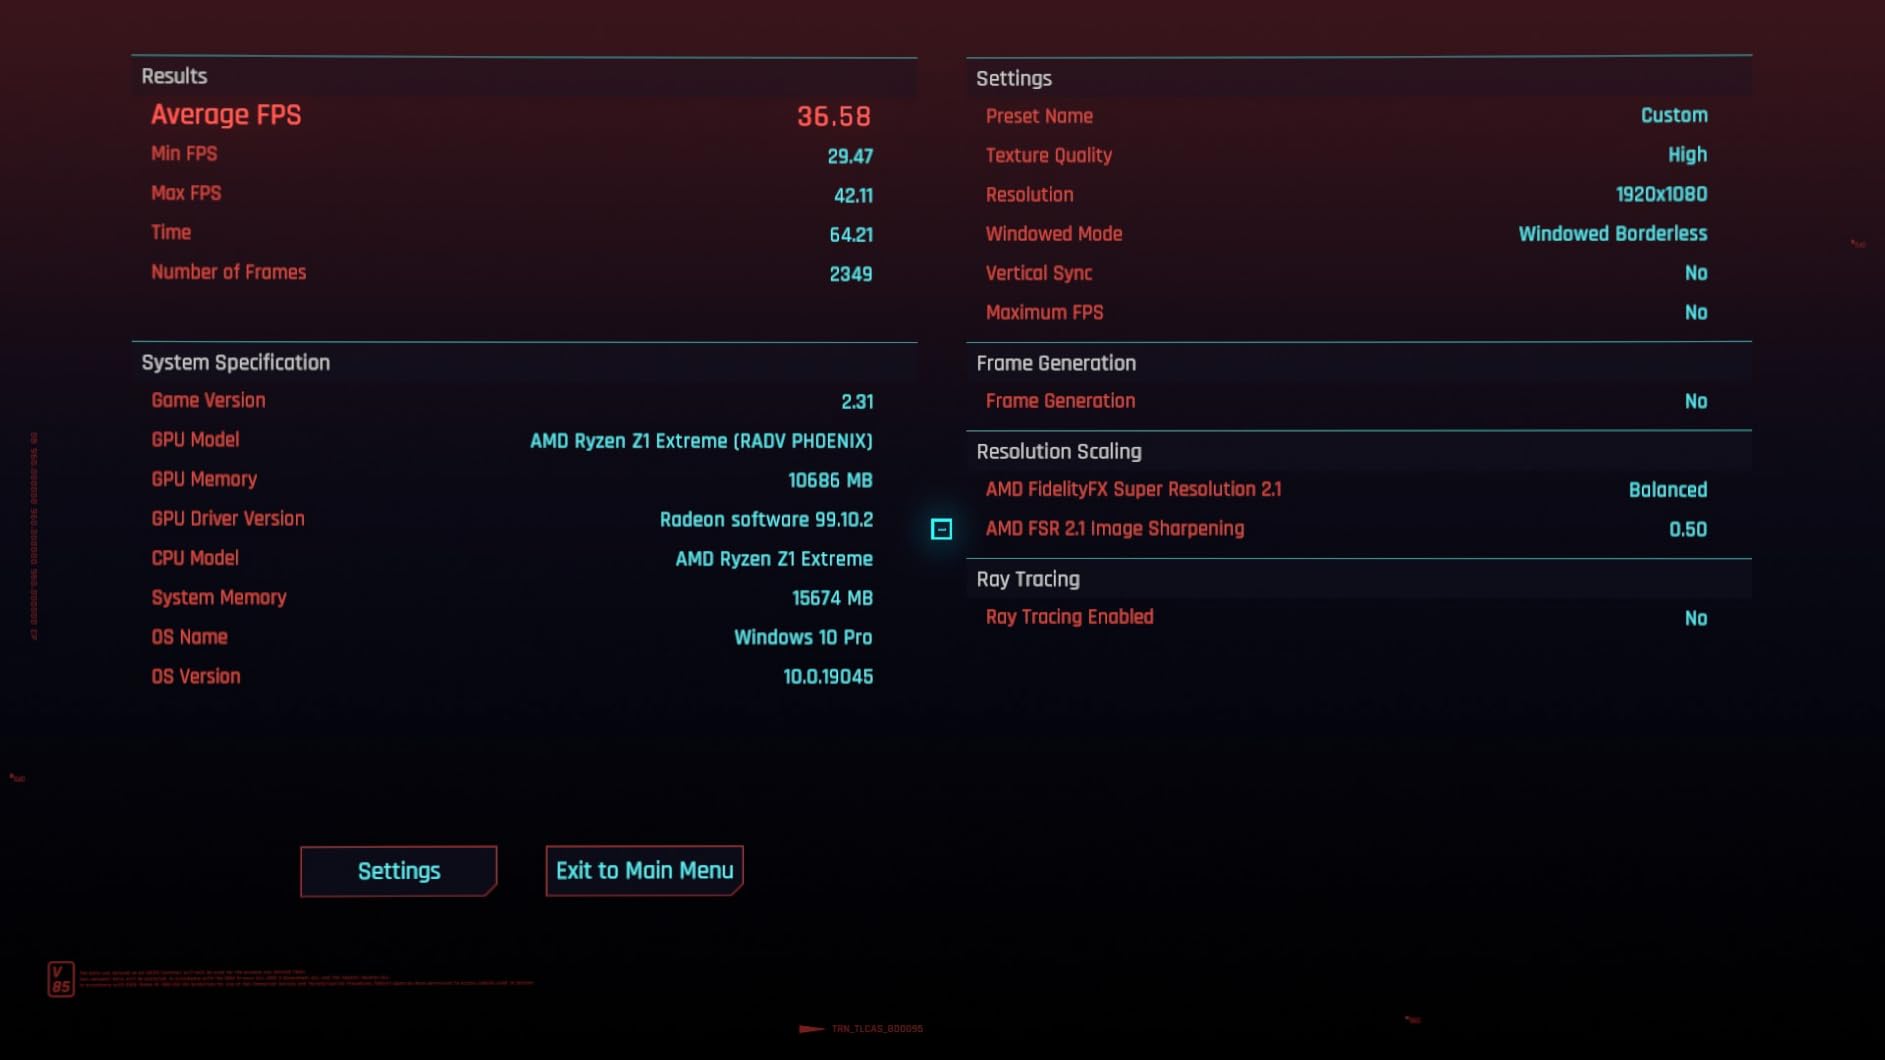
If your software stack is llama.cpp, Ollama on Linux, or a local inference service, this is the pick. The 12-core Zen 5 part, the fast integrated GPU, and a vendor that ships with Ubuntu and other major distributions in mind add up to far less friction than the same hardware on a Windows-only mindset.
Pass on it if you need three storage slots and an eGPU at the same time, or if network booting is part of your plan. Everyone else in the 32GB class should at least look at it.
3. GMKtec K15 – Best Value Box for 7B to 32B Models
- ✓ Documented Ollama throughput on 7B to 35B models
- ✓ Dual SO-DIMM and three M.2 slots
- ✓ OCuLink plus dual 2.5GbE for a homelab node
- ✓ Very quiet at 35dB in quiet mode
- ✕ Arc 140T graphics are weak for gaming and 3D
- ✕ 31B-plus models run far slower than small ones
- ✕ Some reports of fan noise and Wi-Fi driver instability
Core Ultra 5 125U, 12 cores
32GB dual SO-DIMM DDR5-4800
1TB PCIe 4.0 SSD, 3 M.2 slots
OCuLink, 2.5GbE, 35W
The K15 is the one I recommend without hesitation to anyone who wants to start experimenting with local models this month. One long-term owner documented specific Ollama throughput across the 7B to 35B range on this configuration, and at 32GB with two memory slots and three M.2 positions, the machine has more upgrade room than anything costing meaningfully more.
The Core Ultra 5 125U is a 12-core part with a 4.3GHz turbo, and the Intel AI Boost NPU is rated up to 13 TOPS. The NPU number will not change your token rates today, but the 12 CPU cores do real work: tokenising a prompt, building a retrieval index, running an embedding model alongside a chat model. Most people underestimate how much of the workload is not generation at all.
At 35 watts this is also the cheapest machine here to leave running continuously, which matters if you want a local API endpoint that is always available rather than a desktop that wakes up on demand.
Memory and Storage Are the Reason This One Wins
Dual 16GB SO-DIMM DDR5-4800 modules mean you can go to 64GB or more later with a cheap memory kit rather than a new machine. Combined with three M.2 2280 slots supporting up to 24TB total, you can hold several quantised model libraries, embeddings, and a container image without touching a single drive.
The 4800 MT/s memory speed is lower than the 5600 modules in some rivals, and on bandwidth-bound inference that shows up as slower generation. It is the main reason this is best value rather than best overall, and it is worth weighing against the faster picks if you plan to spend long sessions generating.
What 32GB of Memory Means for Model Choice
Thirty-two gigabytes is the sweet spot for 32B models at a 4-bit quantization. Weights land near 16GB, the overhead fits comfortably, and you can keep a coding assistant model resident at the same time as a chat model. It is also enough for 14B models at 8-bit, which is a better balance of quality and speed than dropping to 4-bit.
Past the 31B class, expect the experience to change sharply. Reviewers are explicit that larger models run much more slowly than small quantised ones on this class of integrated graphics, and that is the bandwidth ceiling talking, not a defect.
Who This Is For
This is the machine for a developer who wants a private coding assistant, a student evaluating open-weight models, or anyone building a small homelab node that runs inference and networking services at once. OCuLink and dual 2.5GbE make it a credible small server as well as a desktop.
Skip it if you are a gamer. The Arc 140T integrated GPU is not the point of this machine, and buying it for gaming means buying the wrong product. It is also not the choice if you need the fastest tokens per second per pound of cash, where the faster memory in higher tiers wins.
4. BOSGAME M5 – 128GB Unified Memory for 70B-Class Work
- ✓ 128GB unified memory holds 70B-plus models locally
- ✓ Radeon 8060S is unusually capable for an integrated part
- ✓ Reported silent in normal use
- ✓ Compact and efficient for workstation-class AI
- ✕ Memory is soldered and cannot be upgraded
- ✕ Pre-installed Windows image slows the system noticeably
- ✕ Some owners report random shutdowns needing a power cycle
Ryzen AI Max+ 395, 16 Zen 5 cores
128GB LPDDR5X-8000 unified
Radeon 8060S, 40 RDNA 3.5 CUs
2TB SSD plus second M.2, 1.34 kg
The M5 is the machine the enthusiast community actually converges on, and the reason is the number on the spec sheet: 128GB of LPDDR5X-8000 unified memory. Nothing else in a chassis this small gives the GPU a pool that large to carve from, and that pool is what decides whether a 70B model loads at all.
Inside, the Ryzen AI Max+ 395 provides 16 Zen 5 cores and 32 threads with a 5.1GHz boost, alongside a Radeon 8060S with 40 RDNA 3.5 compute units and dynamic memory allocation up to 96GB. Combined AI throughput is quoted at 126 TOPS, of which 50 come from the XDNA 2 NPU. For LLM work, the GPU and that memory pool do the heavy lifting.
Owners report the machine is completely silent in normal use and that Linux distributions like Pop OS and Manjaro run noticeably better than the shipped Windows image. That last point matters more than it sounds, since a heavy Windows install is competing for the same bandwidth you are trying to give the model.
How 128GB Unified Memory Changes What You Can Run
With a pool that large, a 70B model at 4-bit sits comfortably in GPU-accessible memory instead of spilling into system RAM and crawling. It also means you can hold two large models at once, or one model with a very long context, which is what makes a machine like this useful as a shared development server rather than a personal toy.
For a sense of what unified memory can deliver, a Framework Desktop owner in r/LocalLLM reported running a GLM 4.7 class model at 40 to 50 tokens per second on 128GB of unified memory. That is a different chassis, but it is the same architectural approach and a useful anchor for expectations.
The BIOS Allocation Step Buyers Miss
On a unified memory design, the amount the GPU can address is set in firmware, and community consensus in Strix Halo threads is to allocate the maximum you can spare before first boot. Owners on r/StrixHalo repeat the same advice: check the BIOS and raise the dedicated VRAM allocation, because the default can leave a large fraction of that 128GB sitting idle on the CPU side.
This is the single highest-value ten minutes you can spend on a machine like this. The Radeon 8060S is documented as supporting up to 96GB of dynamic allocation, which is only reachable if the firmware hands it over.
Storage, Networking and the Windows Caveat
Storage is generous for the category: a 2TB PCIe 4.0 SSD with a second M.2 slot, expandable to 8TB or configured in RAID. Networking is 2.5GbE with Wi-Fi 7 and Bluetooth 5.4, and display output covers quad 8K at 60Hz across HDMI 2.1, DisplayPort 1.4 and dual USB4.
The clearest advice from owners is to replace the Windows image. The pre-installed version runs heavy background processes that measurably slow a system where every byte of bandwidth matters, and a clean Linux install transforms the experience. Warranty is 1 year on the machine and 3 years on parts.
When This Is the Wrong Buy
The memory is soldered, which is the trade every 128GB unified design makes. If you are not certain you will stay in the 70B range for the life of the machine, a 64GB upgradeable DDR5 box is the more flexible purchase, because you can add memory later instead of committing today.
Also weigh the quieter complaint. Some owners report random shutdowns requiring a power cycle, and the listing has been inconsistent about exactly what is included. If you are deploying this as a production endpoint rather than a development machine, validate it thoroughly before you depend on it.
5. GEEKOM GT1 Mega – Best Dual-LAN Homelab Node
- ✓ Strong 16-core performance in a premium chassis
- ✓ No thermal throttling under heavy workloads
- ✓ Dual 2.5GbE suits server and NAS duties
- ✓ Three-year warranty
- ✕ Fan noise is louder than comparable mini PCs
- ✕ Very short Wi-Fi antenna lead inside the case
- ✕ Some freeze reports after driver or cleanup utilities
Core Ultra 9 185H, 16 cores
32GB DDR5 expandable to 96GB
1TB SSD
IceBlast 2.0, 3-year warranty
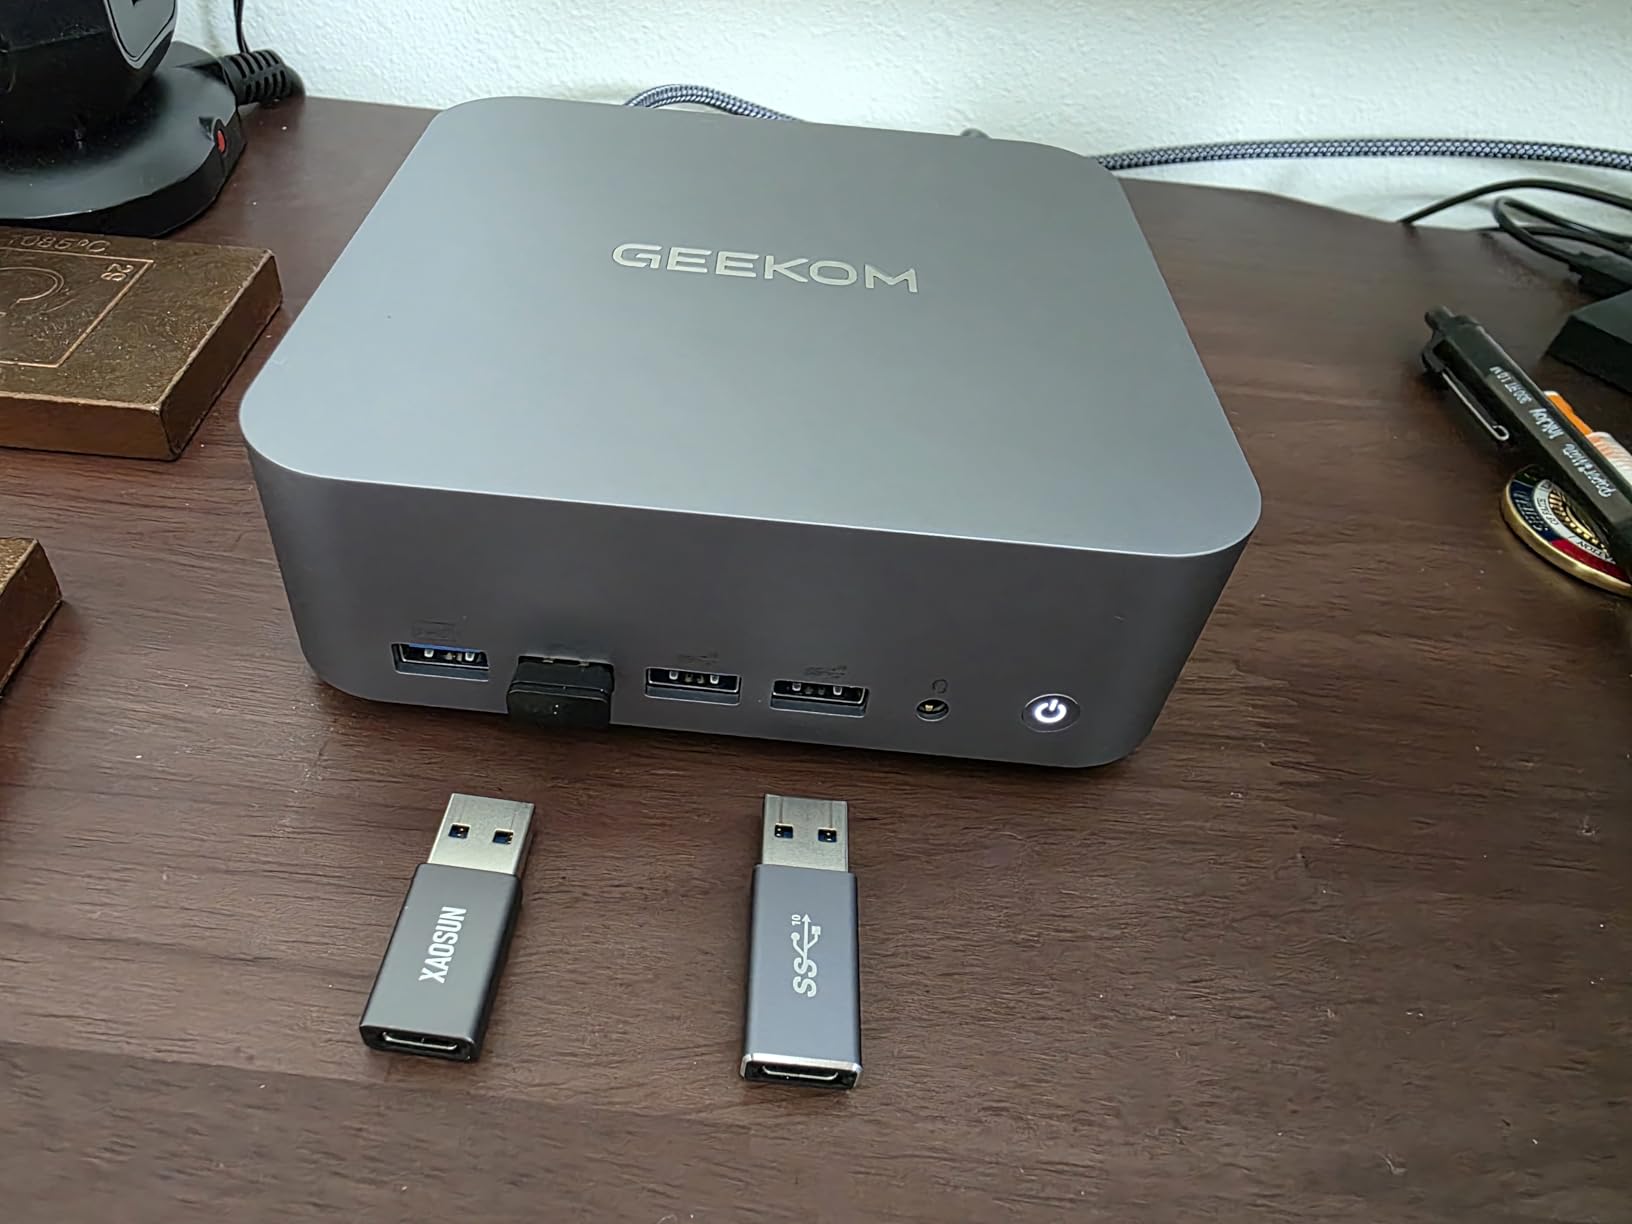
The GT1 Mega exists for a specific job: running as a network node. With dual 2.5GbE ports, 32GB of DDR5 that expands to 96GB, and a 16-core Ultra 9, it is built to sit on a shelf serving models and files rather than sit on a desk. Reviewers who use it this way rate the thermal behaviour very highly, reporting that it stays cool and does not throttle under heavy sustained work.
The Core Ultra 9 185H is the same 16-core part as the IT13 MAX, configured up to 65W with Intel Arc integrated graphics. The practical difference from the Editor’s Choice is memory: 32GB of DDR5 on removable modules here, against 24GB of soldered LPDDR5 there. For a machine you intend to grow into, that is the more useful arrangement.
Display output reaches 8K at 60Hz across four displays, and the port selection includes eight USB ports, two HDMI, USB4, an SD card slot and dual 2.5GbE. Three years of warranty coverage is longer than most competitors in this class.
Running Proxmox and Inference on One Box
This is the co-hosting pattern that makes a dual-network mini PC interesting. With 96GB of memory at maximum, you can allocate a fixed slice to virtual machines under Proxmox and the remainder to a resident model server, and use the two 2.5GbE ports to keep management traffic separate from data transfer.
Set the memory allocation carefully and note that a resident model still wants its memory committed, not merely reserved. If you plan to run a 32B model plus two or three lightweight containers, 32GB of base memory is workable but 64GB would be comfortable.
What to Watch Before You Deploy It
Two things get mentioned repeatedly. The fan is louder than comparable mini PCs and spins up more often, which is a fair trade for a shelf-mounted server but worth knowing if the box will be in a room you sit in. The Wi-Fi antenna lead inside the case is very short and can be dislodged when opening it, which is a genuine annoyance if you service the machine.
There are also isolated reports of freezes after driver or cleanup utilities, and the initial Windows image sometimes needs several update rounds before it settles. On a machine you will access remotely, plan a local keyboard before relying on it.
Who This Is For
Buy the GT1 Mega if you want a homelab node with more memory headroom than the entry-level boxes and genuine dual-network flexibility. The IceBlast 2.0 cooling doing real work under long loads is what makes it credible as a server rather than a desktop in a small case.
Skip it if noise matters or if you want the smallest possible footprint, because 8.94 by 6.92 by 5.27 inches is no longer the tiny-chassis advantage that mini PC buyers usually care about. It is a compact box, not a palm-sized one.
6. BOSGAME VTA-439 – Best for Memory Headroom up to 256GB
- ✓ Memory user-upgradable to 256GB
- ✓ 86 TOPS total AI throughput
- ✓ Three PCIe 4.0 M.2 slots plus OCuLink
- ✓ Compact 765g footprint with clean Windows 11 Pro
- ✕ 54W envelope limits sustained heavy inference
- ✕ Display output listing and spec sheet disagree
- ✕ Brand has a shorter support track record
Ryzen AI 9 HX470, 12C/24T
32GB DDR5-5600 up to 256GB
1TB NVMe, 3 M.2 Gen4 slots
OCuLink, dual 2.5GbE, 54W
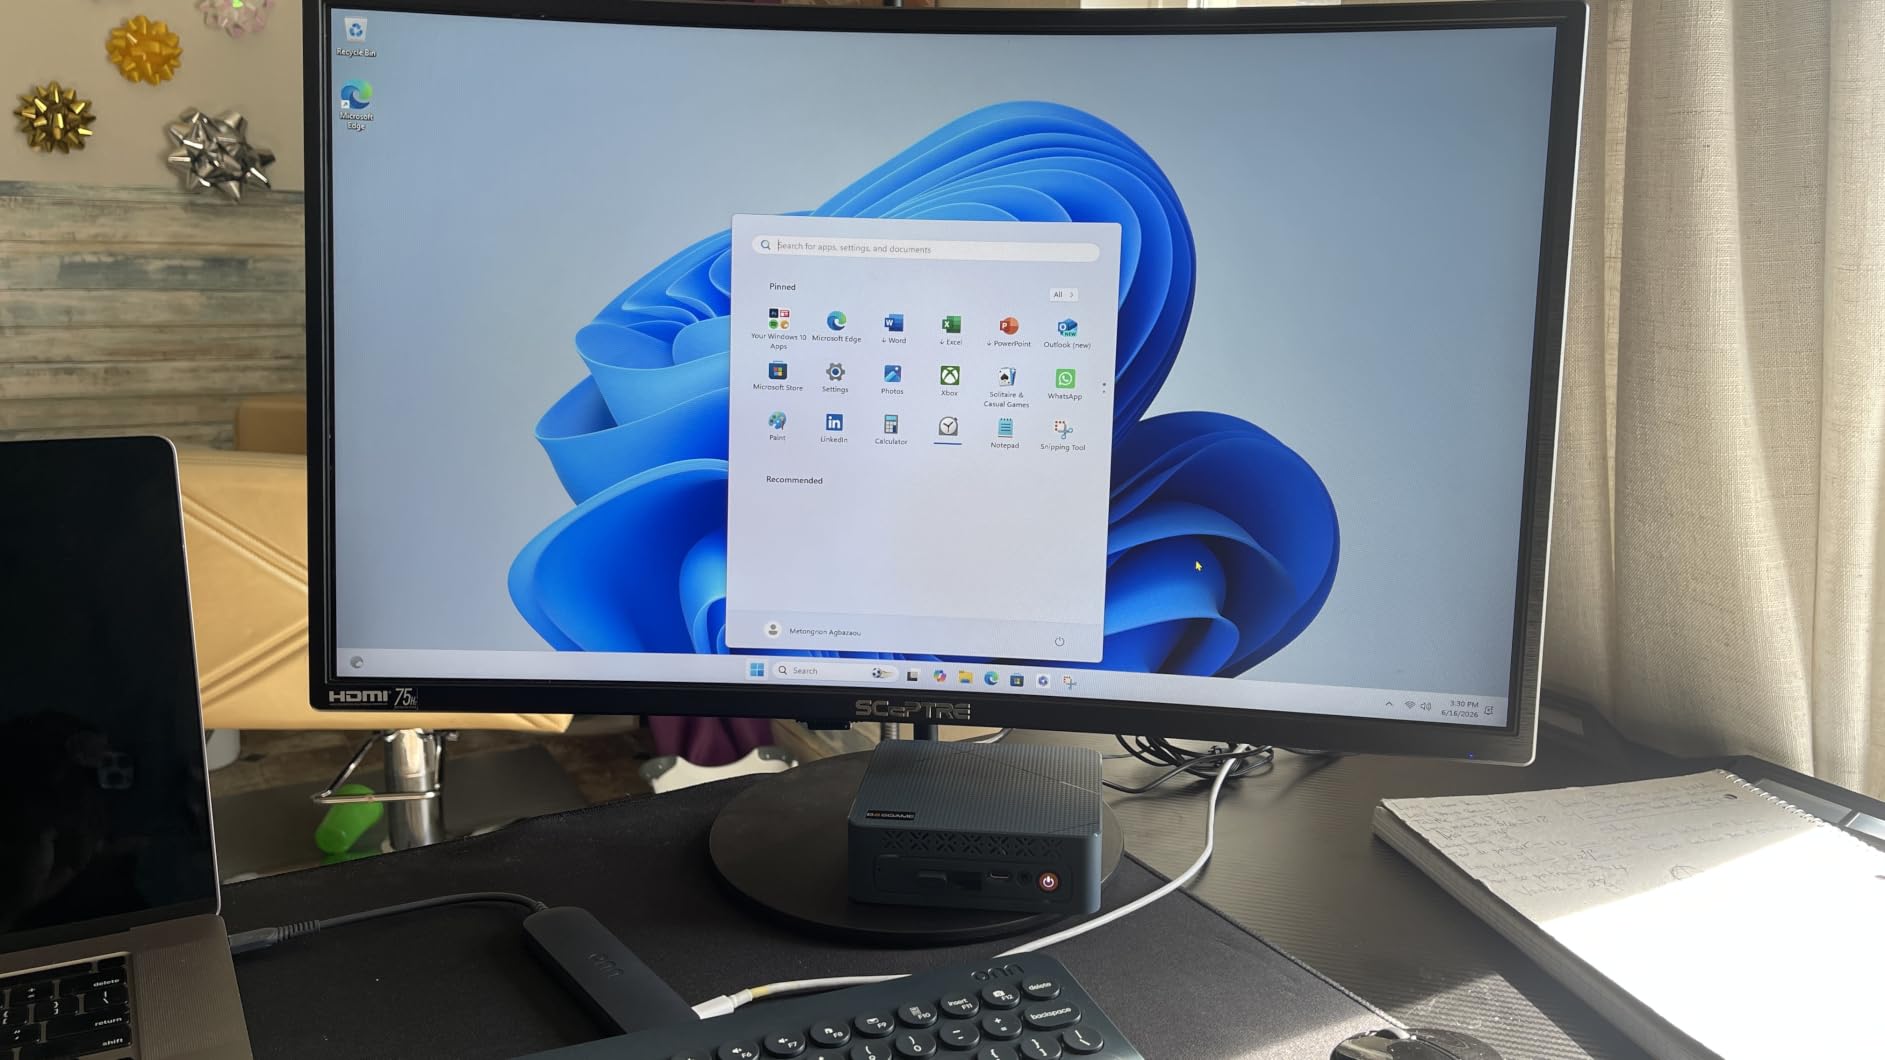
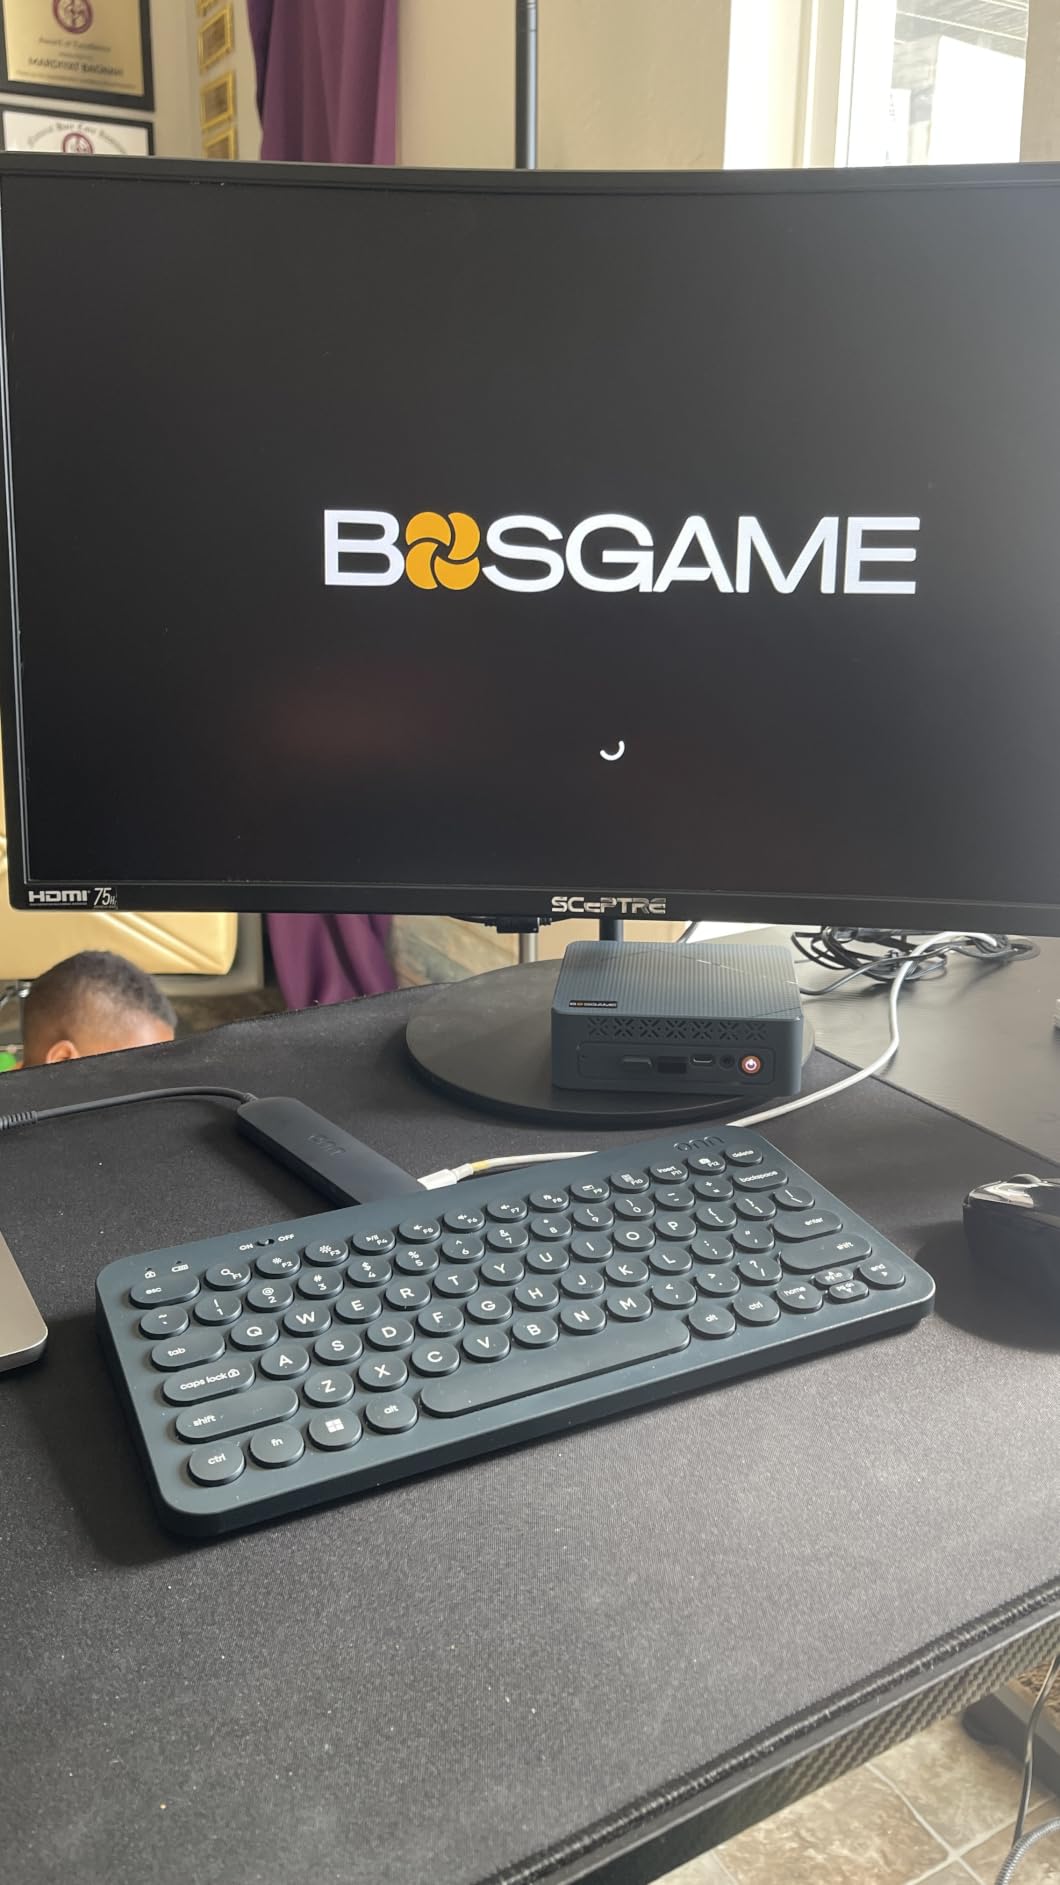
With a 4.5 average across 226 ratings, the VTA-439 is among the better-rated boxes in this group, and the number buyers cite first is memory: 32GB DDR5-5600 that is fully user-upgradable to 256GB. No other machine in this roundup offers that ceiling on removable memory, which makes it the most future-proof 32GB-class option.
The Ryzen AI 9 HX470 provides 12 cores and 24 threads of Zen 5 silicon boosting to 5.2GHz, with 86 TOPS of total AI throughput and a 55 TOPS XDNA 2 NPU. The Radeon 890M with 16 RDNA 3.5 compute units is a capable integrated GPU, and the OCuLink port gives you a direct PCIe lane to an external card when you want real VRAM.
It is also the smallest machine here by weight at 765 grams, in a 5.91 by 5.91 by 1.77 inch chassis, which is genuinely convenient for a machine that will live behind a display.
Why 256GB of Memory Changes the Conversation
Most buyers stop at 64GB because that is where mainstream hardware lands. Going to 128GB or 192GB on removable modules is the difference between running a 70B model at 4-bit and running it at 8-bit, or holding a large model plus a second one plus a retrieval index in memory at the same time. That flexibility is the reason to buy this rather than a cheaper box.
Three PCIe 4.0 M.2 slots supporting up to 12TB total means the storage side of the equation is equally generous. A model library, a vector store, and container images fit without a single external drive.
The 54W Ceiling and What It Means for Long Sessions
The one substantive criticism in the reviews is the power envelope. At 54W with a modest cooling solution, sustained heavy inference is bounded by thermals earlier than it would be on a 65W or 120W machine. In practice that means long generation sessions eventually settle into a lower sustained rate rather than holding peak indefinitely.
For interactive use, a coding assistant, or short batch jobs, this is a non-issue. For an always-on server generating continuously, size the cooling expectations accordingly or run it in Performance mode with airflow.
Support and Listing Details Worth Checking
Two smaller things to verify before you order. The display output listing mentions USB-C while the spec sheet lists HDMI and DisplayPort only, so confirm the exact outputs on the unit you receive. And the brand has a shorter support track record than the long-established names in this category, which matters more if you plan to run this unattended.
Warranty is 1 year on the machine and 3 years on parts, with Windows 11 Pro pre-installed and Ubuntu compatibility noted.
Who This Is For
This is the pick for someone who is confident they will be running large models for years and wants to avoid buying twice. The 256GB ceiling means one purchase can cover a 70B model at 4-bit today and a much larger quantised model after a release next year.
Pass if you only need 7B to 14B models, or if constant heavy load is routine. In either case the memory you would not use costs you money you would rather spend on faster memory or a discrete GPU later.
7. Beelink SER10 MAX – Best for Serving Models Over 10GbE
- ✓ Ryzen AI 9 HX470 handles WSL and dev workloads smoothly
- ✓ 10GbE LAN for fast model transfer and serving
- ✓ Very quiet and compact enough to sit by a display
- ✓ Three-year warranty with lifetime technical support
- ✕ No internal speakers
- ✕ Driver and support pages are hard to find
- ✕ Bluetooth driver issues reported by some owners
Ryzen AI 9 HX470, 12C/24T
32GB DDR5 expandable to 256GB
1TB PCIe 4.0 SSD
10GbE LAN, USB4 40Gbps
The SER10 MAX wins on one specific thing: a 10GbE port. On every other box in this roundup the fastest wired option is 2.5GbE, which is fine for serving a chat model to a handful of clients but becomes the bottleneck the moment you start pushing large quantised files across the network or serving several concurrent sessions.
Underneath the network advantage it is a capable 32GB machine. The Ryzen AI 9 HX470 delivers 12 cores and 24 threads at up to 5.2GHz with Radeon 890M graphics, and reviewers describe it handling WSL, coding assistants and full-stack development workloads smoothly. Memory is DDR5 in dual slots expandable to 256GB, with dual M.2 storage up to 8TB.
It is also the quietest of the HX470-based machines in practical use, and small enough to sit beside a display without being noticed.
When 10GbE Actually Matters for Inference
Think about what a model server does over the network. It accepts prompts, which are tiny, and it returns tokens, which are also tiny. The heavy transfer is the model file, and on first load that is a multi-gigabyte download onto the machine itself. On 10GbE a large quantised model arrives dramatically faster than on 2.5GbE, which matters if you are re-pulling models often.
The second case is multiple concurrent clients. Each additional session holds a KV cache and competes for memory bandwidth, and a faster link keeps the latency floor lower when several people or services hit the same endpoint at once.
Memory, Storage and the Developer Experience
Dual DDR5 slots expandable to 256GB mean the same long-term flexibility as the VTA-439, and dual M.2 slots up to 8TB cover a working library of quantised models. Ports include USB4 at 40Gbps, USB-C at 10Gbps, two USB-A at 10Gbps, and dual 3.5mm audio jacks.
Triple 4K output is handled through HDMI, DisplayPort and USB4, with HDMI and DisplayPort capable of 4K at 240Hz. That refresh capability is a side benefit rather than an AI feature, but it makes the box usable as a general desktop.
Where It Falls Short
The support experience is the main friction. Reviewers describe driver and support pages as hard to find, and some owners report Bluetooth driver problems. For a machine that will sit on a wired network serving models, Bluetooth matters little, but for a general-purpose desktop it is a papercut that costs you an afternoon.
There are no internal speakers, which surprised at least one owner, and Beelink’s warranty service has been criticised as slow by some long-term buyers. If you are deploying this as a service others depend on, the three-year warranty and lifetime technical support are real positives, but keep a fallback plan.
Choose it for the network. Choose the VTA-439 if you want more storage slots and a smaller footprint; choose the AI X1 Pro-370 if you want a lower-power, quieter box with more expansion sockets.
8. GMKtec EVO-T1 – Best 64GB Base Memory Without Soldering
- ✓ Largest base memory in this roundup at 64GB
- ✓ Quiet and cool to the touch under heavy work
- ✓ Three M.2 slots plus OCuLink for expansion
- ✓ Popular as a portable VM and development node
- ✕ Not a real gaming machine on Arc 140T graphics
- ✕ A minority of buyers report crashes and hot-kernel issues
- ✕ Factory BIOS fan settings can be overly aggressive
Core Ultra 9 285H, 16 cores
64GB dual SO-DIMM DDR5-5600
1TB SSD, 3 M.2 slots, up to 12TB
OCuLink, 90W
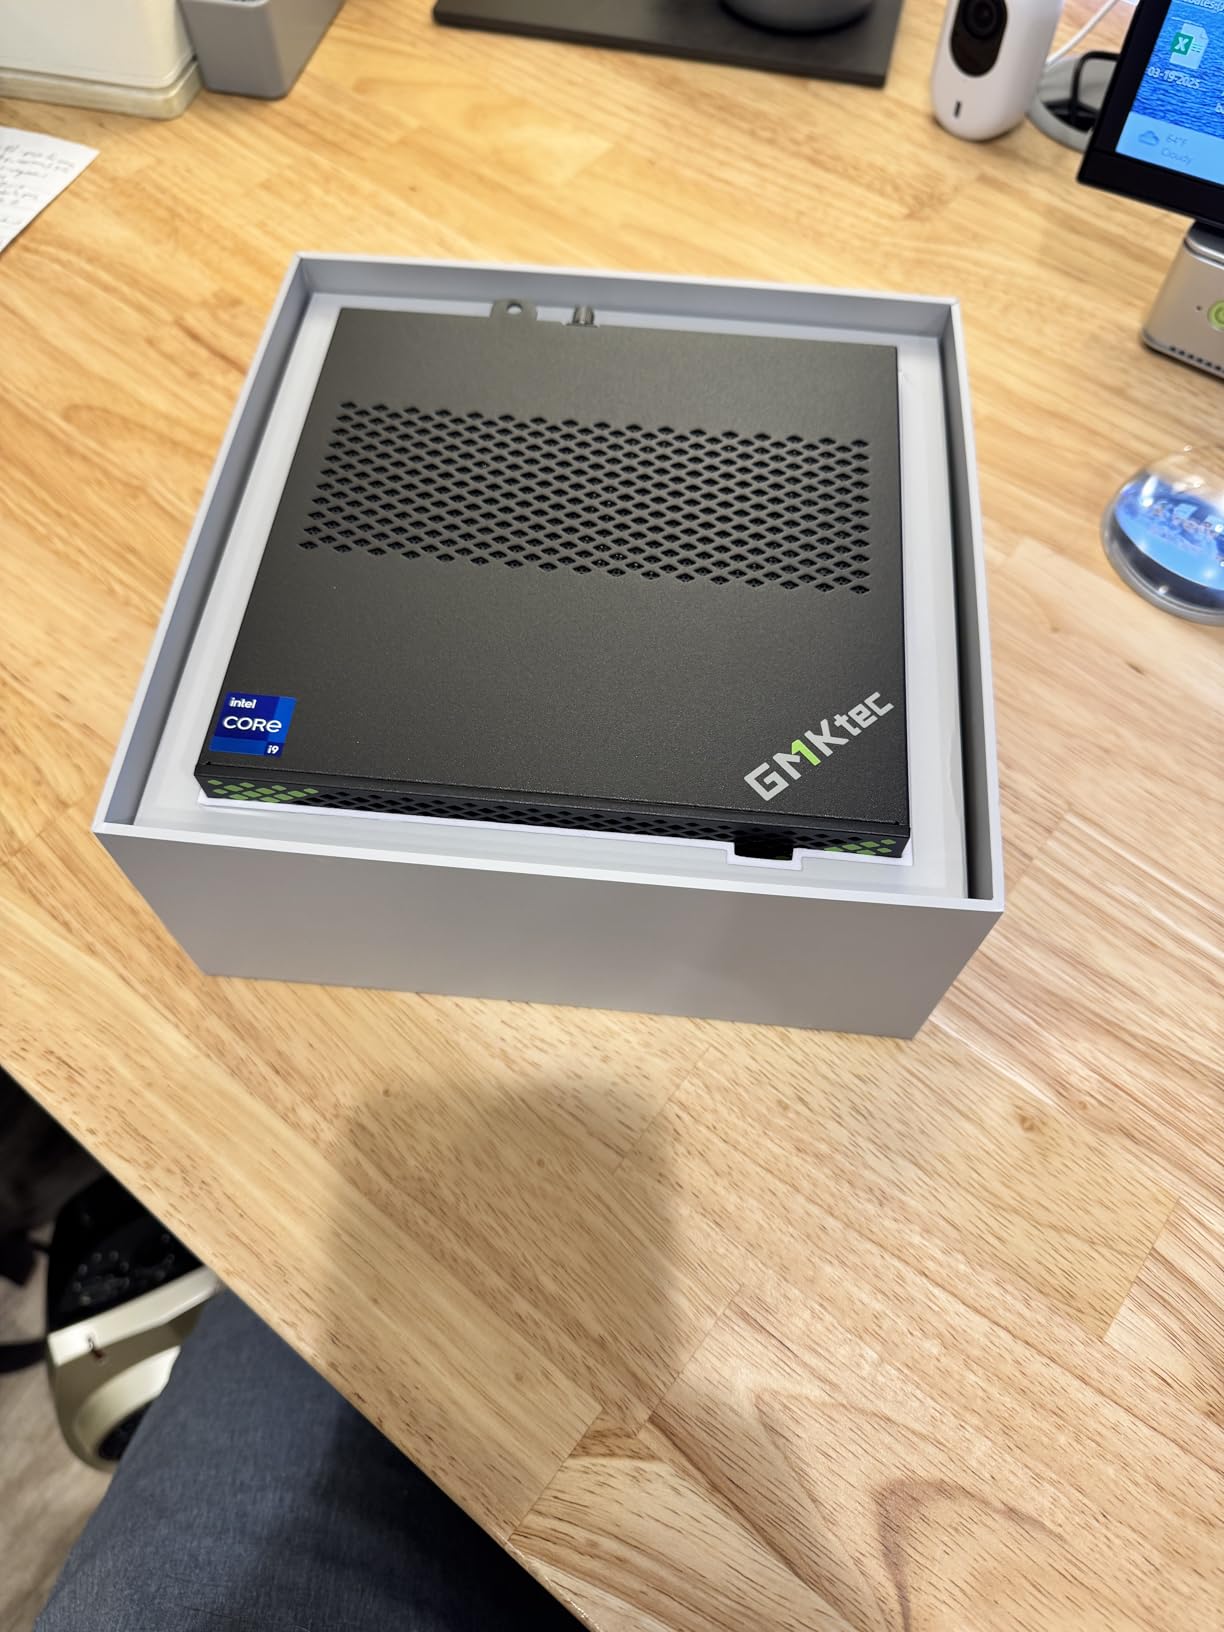
The EVO-T1 solves the problem that frustrates most local AI buyers: you get 64GB of memory without giving up the ability to change it. Both SO-DIMM slots are populated with 32GB DDR5-5600 modules, and while the listing caps expansion at 96GB, the memory itself is removable rather than soldered, which means you can re-populate with faster or denser modules later.
The Core Ultra 9 285H provides 16 cores with a 5.4GHz turbo, and the 90W power envelope gives it noticeably more sustained headroom than the 35W and 54W machines in this list. Owners running video and audio production report no perceptible slowdown, which tells you the cooling is doing its job.
Three M.2 2280 slots supporting up to 12TB total, plus OCuLink, mean storage and GPU expansion are both covered. This is a box that ends up in a cupboard running virtual machines and development containers, which is exactly how several owners use theirs.
Why 64GB of DDR5-5600 Changes the Ceiling
Sixty-four gigabytes of dual-channel DDR5-5600 is the configuration that unlocks the 70B class without a 128GB unified-memory design. At a 4-bit quantization a 70B model needs roughly 42GB with overhead, so it loads with room left over for a long context and the operating system. At 8-bit it is tight but workable for shorter contexts.
The 5600 MT/s speed also matters more here than anywhere else in the roundup. Token generation reads memory weights at every step, so faster memory directly raises the tokens per second ceiling on an integrated GPU. This box is not a substitute for a discrete card with true VRAM, but it is meaningfully faster than the 4800-class options.
Expansion, Cooling and Everyday Use
With three M.2 2280 slots, you can run a large model drive, a fast working NVMe, and a backup drive without adapters. OCuLink adds a direct PCIe lane for an external GPU, so the upgrade path to real VRAM is already built in.
Reviews consistently describe the machine as very quiet and cool to the touch under sustained graphics, video and audio work, with dual cooling fans. The one caveat is that factory BIOS fan settings can be overly aggressive, and changing them is worth testing before you deploy it somewhere quiet.
Who This Is For
Buy the EVO-T1 if you want to run 32B models today and 70B models in a year without changing machines, and you would rather have removable DDR5 than a fixed unified pool. It is also a strong general-purpose workstation, so it earns its desk space even on days when you are not generating tokens.
Skip it for gaming. The Arc 140T integrated graphics will not run modern titles, and a minority of buyers report crashes and hot-kernel issues that would be unacceptable in a machine you also rely on for work. Validate the first week carefully if this one is going to be your only machine.
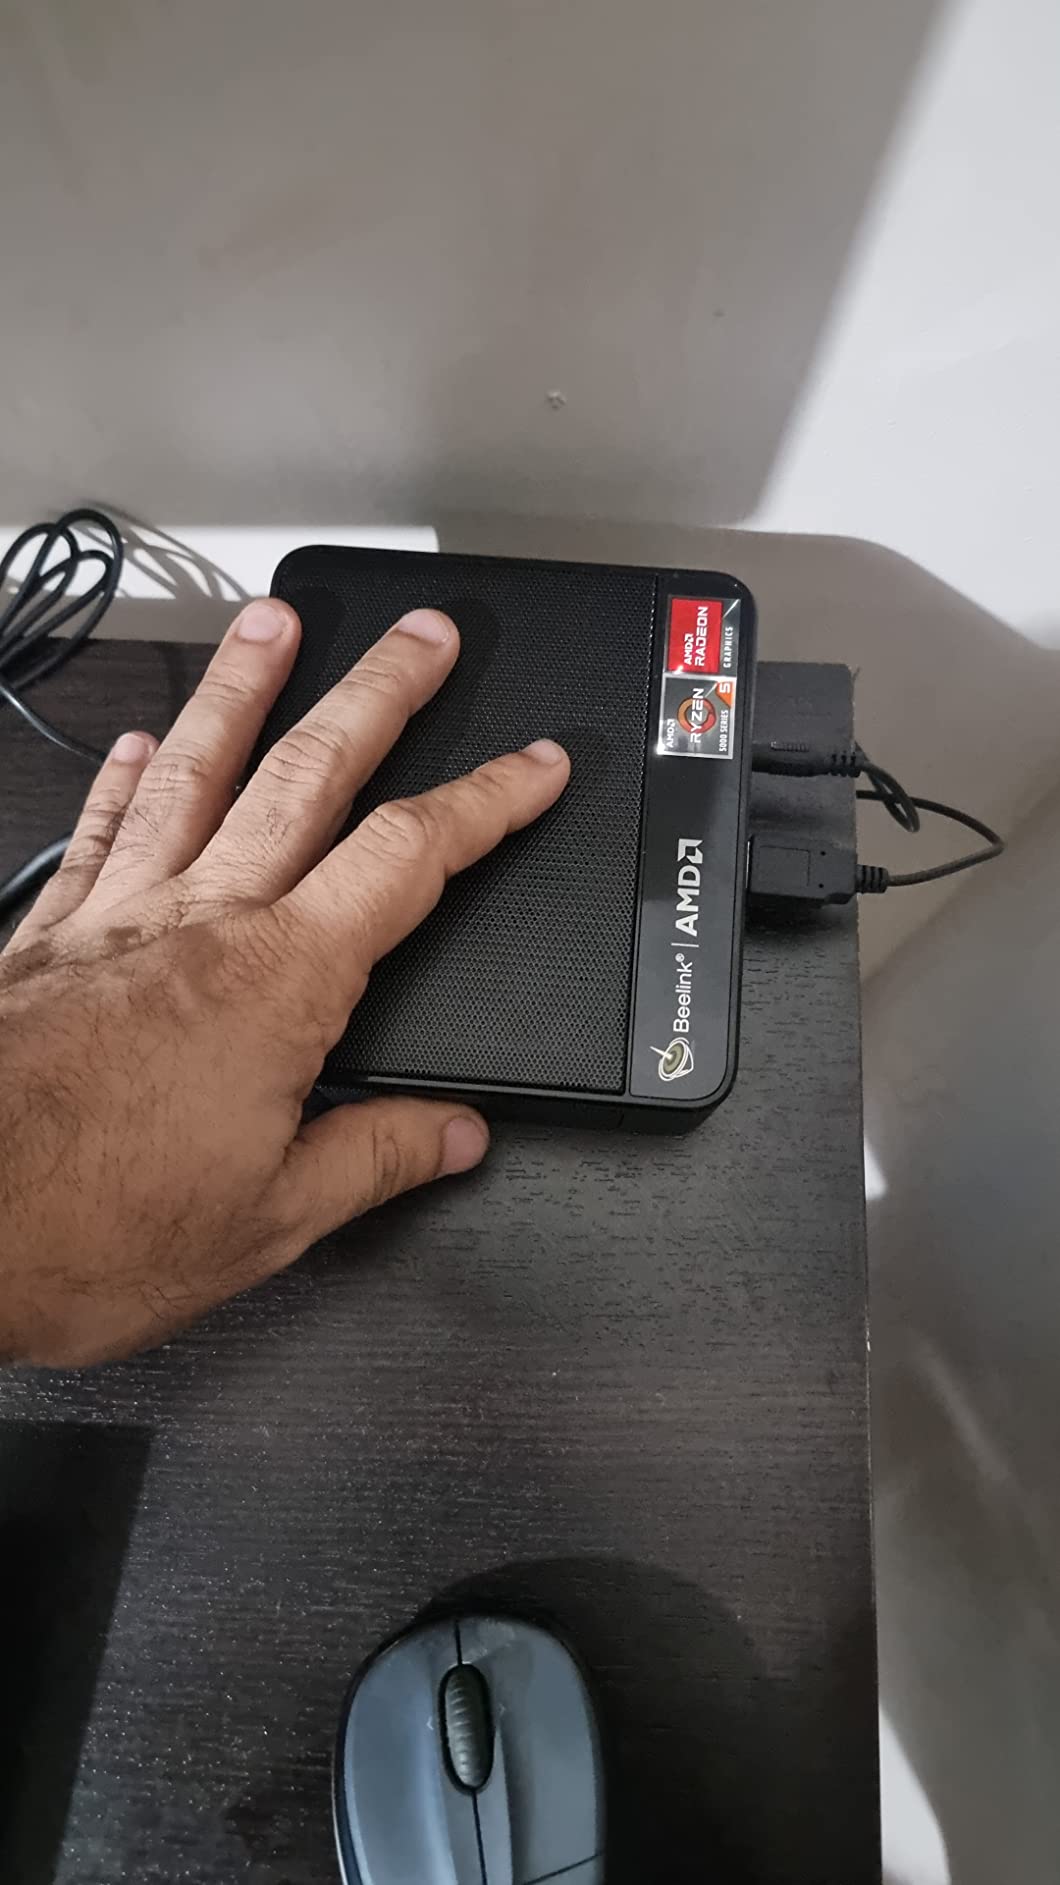
9. Beelink SER9 Pro – Budget Pick for 8B Models and Transcription
- ✓ Quiet
- ✓ cool and quick for an everyday machine
- ✓ Radeon 780M handles 4K streaming and light gaming
- ✓ Triple display output with USB4 40Gbps
- ✓ Clean Windows install with no bloatware
- ✕ 24GB soldered memory cannot be upgraded
- ✕ Only three monitors supported
- ✕ Some units shipped with unreliable power adapters
Ryzen 7 H 255, 8C/16T
24GB LPDDR5X-6400 soldered
1TB NVMe, dual SSD slots to 8TB
1.46 kg, USB4 40Gbps
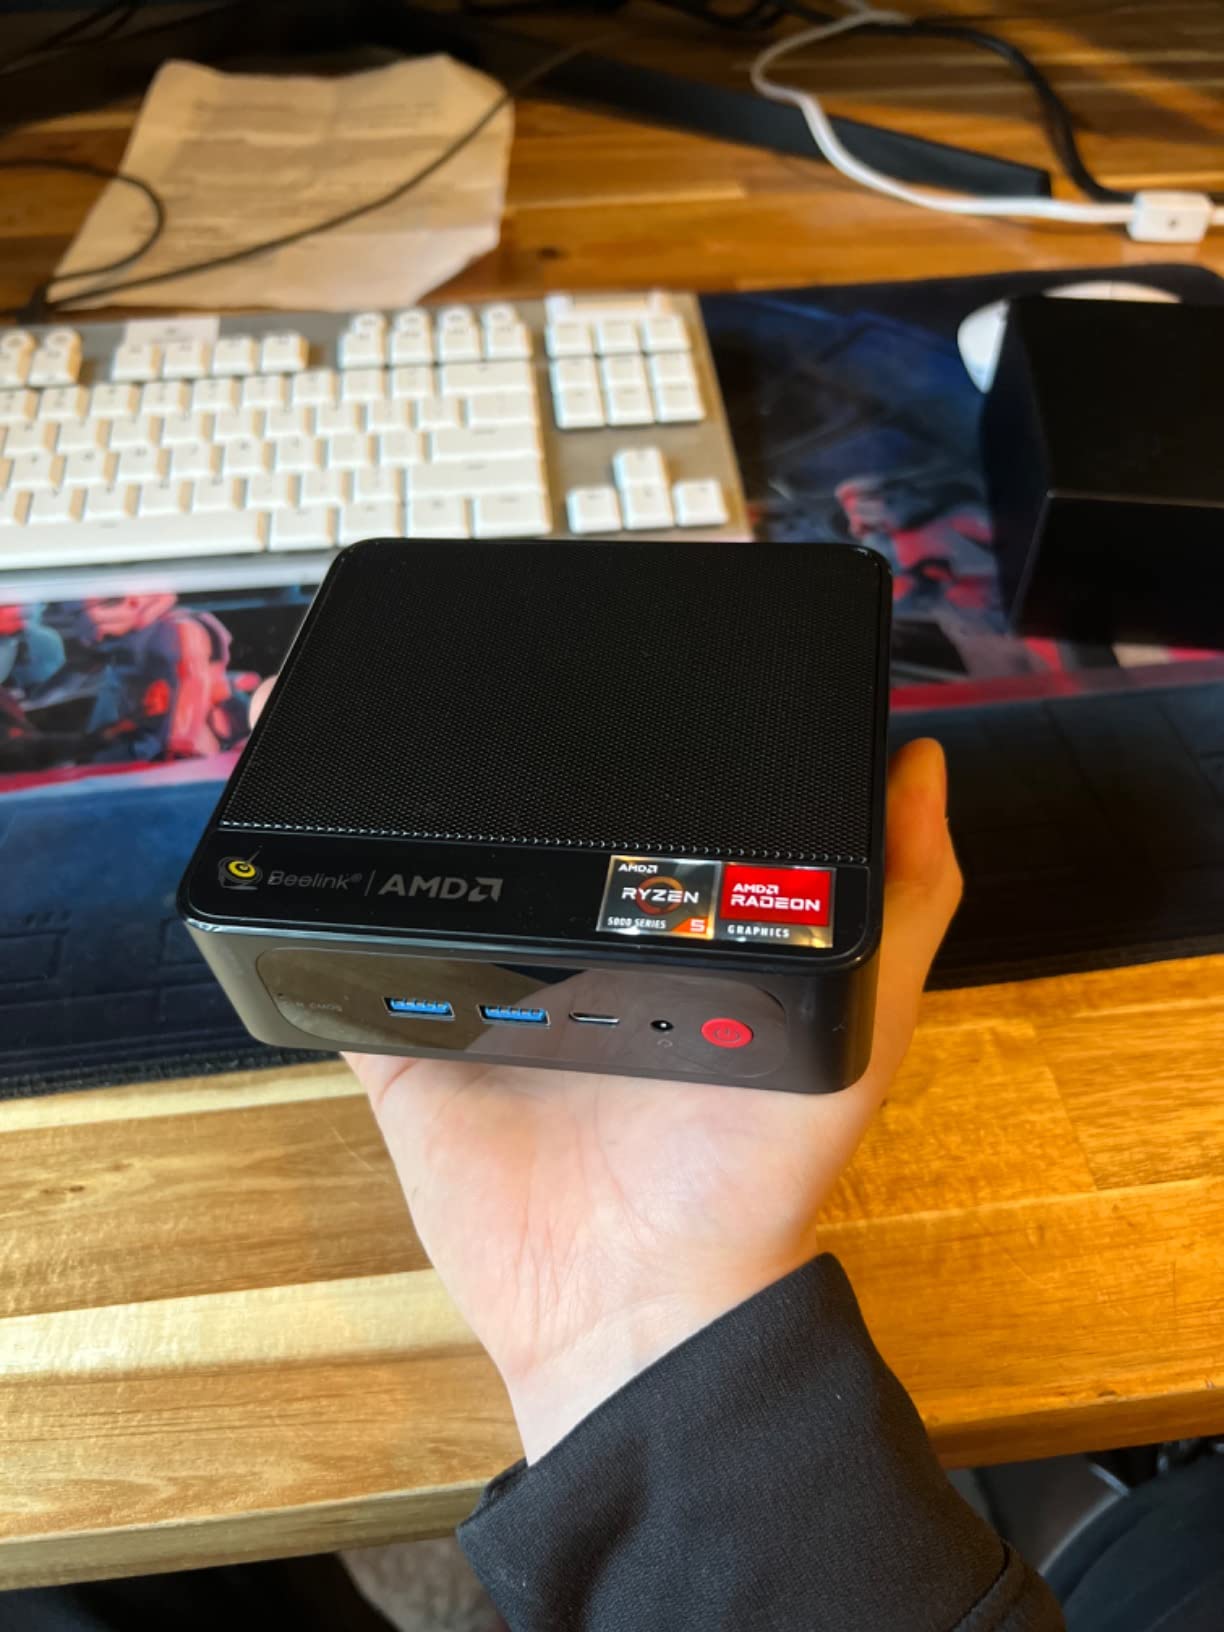
The SER9 Pro is the honest entry point. It is a quiet, capable everyday machine with a Ryzen 7 H 255 at up to 4.9GHz and Radeon 780M graphics, and for 7B and 8B models, plus Whisper-style speech transcription, that is entirely enough. It is not enough for 32B models, and the 24GB of memory means you will never be able to run them on this machine.
Owners praise the memory speed for what it is: 24GB of LPDDR5X at 6400 MT/s is quick, and fast memory does translate into a higher generation ceiling on integrated graphics. The machine is described as completely silent in normal use, boots fast, and streams 4K smoothly.
Storage is better than the memory story suggests, with dual SSD slots supporting up to 8TB. Ports include USB4 at 40Gbps, two USB-A at 10Gbps, 2.5GbE and dual audio jacks.
What 24GB of Fast Memory Buys You
LPDDR5X at 6400 MT/s is among the fastest memory in this roundup, and on a bandwidth-bound workload speed matters as much as capacity. A 7B or 8B model at 4-bit takes about 5GB, leaving plenty of room for a long context, and a 14B model at 4-bit fits with headroom. At 8-bit a 14B model is a stretch but possible.
The ceiling arrives at 32B, and there is no workaround because the memory is soldered. If your plan might grow to that class, this is the wrong machine and the K15 is the right one.
Quiet Operation and the Power Supply Caveat
Reported behaviour is silent in normal use and cool to the touch, with a clean Windows install and no detectable bloatware. Triple display output runs through HDMI, DisplayPort and USB-C, and the Radeon 780M drives 4K at 144Hz.
The one recurring complaint worth taking seriously is power adapter quality. Some units shipped with unreliable adapters that caused idle shutdowns, which is a manufacturing quality-control issue rather than a design flaw. If you buy this, confirm the adapter behaves correctly under load from day one.
Who This Is For
This is for someone who wants private AI on a daily basis at the smallest commitment: a private assistant, transcription, a small classification model, and a general-purpose machine that does not fight for desk space. Three-year factory support is included.
Pass if you have a 32B model on your list, or if you want more than three displays. It is also worth comparing against a used tower before committing, since a desktop with a dedicated card will beat it on generation speed for similar money in a used market.
10. GMKtec EVO-X2 – The Most Capable Local AI Mini PC
- ✓ 128GB unified memory built for large model inference
- ✓ BIOS re-scales dedicated VRAM to as much as 24GB
- ✓ Two extra PCIe 4.0 M.2 slots for model storage
- ✓ Silent
- ✓ Balanced and Performance power modes
- ✕ Largest footprint here at 7.59 x 7.28 x 3.03 inches and 5.5 lb
- ✕ Memory is soldered and cannot be upgraded
- ✕ Only 36 reviews so long-term data is thin
Ryzen AI Max+ 395, 16 Zen 5 cores
128GB LPDDR5X-8000 unified
Radeon 8060S, 40 RDNA 3.5 CUs
Silent 54W / Performance 120W modes
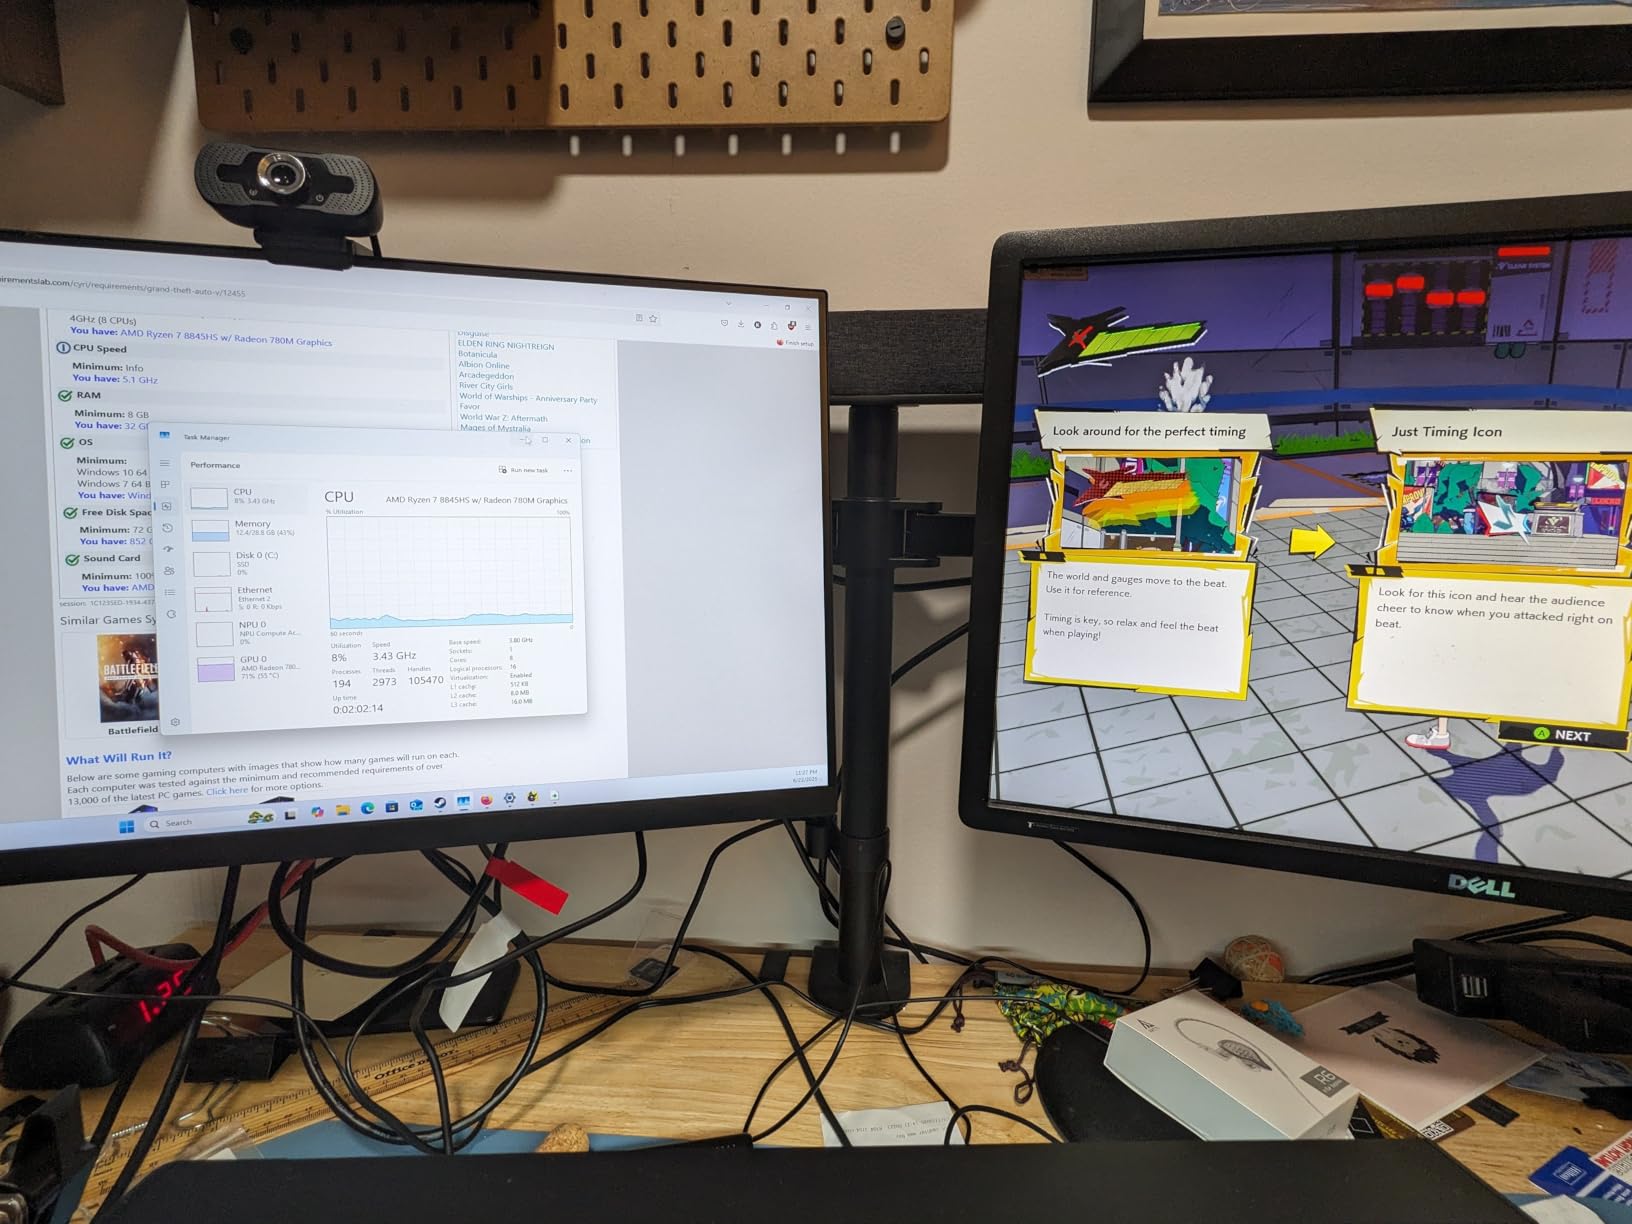
The EVO-X2 carries the highest average rating of any machine in this roundup, and the reason is the same as the M5: 128GB of onboard LPDDR5X-8000 unified memory feeding a Radeon 8060S with 40 RDNA 3.5 compute units. Where it beats the M5 is firmware control. This BIOS lets you re-scale dedicated VRAM allocation to as much as 24GB out of the unified pool, which is the setting that determines how much of a large model stays on the fast path.
The Ryzen AI Max+ 395 supplies 16 Zen 5 cores and 32 threads with 80MB of combined L2 and L3 cache, 126 TOPS across CPU, GPU and NPU, and a 50 TOPS XDNA 2 NPU. Owners report running 9B-class coding models locally and stably, and the value case for the memory alone is what most reviewers lead with.
Power modes are a genuine feature on an inference box: Silent at 54W, Balanced at 85W, and Performance at 120W, peaking around 140W. You can run near-silent for a coding assistant all day and drop into Performance for an overnight batch job.
The BIOS VRAM Setting Is the Whole Point
Community advice from Strix Halo owners is consistent: enter the BIOS and set the dedicated VRAM allocation to the maximum the board allows before doing anything else. Get it wrong and a machine with 128GB of memory behaves like one with 16GB, because the model cannot fit in the addressable pool the GPU is given.
On this machine the option goes up to 24GB of dedicated VRAM, which is more than most 128GB configurations expose. If you are buying any unified-memory box, check the documented maximum allocation figure before you buy, not after.
Storage for a Large Model Library
The EVO-X2 ships with a 1TB M.2 2280 PCIe 4.0 NVMe drive and two additional PCIe 4.0 x4 M.2 slots, each supporting up to 8TB. For a machine whose entire purpose is running large quantised models, that is generous: you can keep the current model, an archive of older quantisations, and a working dataset on separate fast drives.
Networking is 2.5GbE with Wi-Fi 7 and Bluetooth 5.4, and display output covers up to four displays with HDMI 2.1 and DisplayPort 1.4 at 8K 60Hz plus dual 40Gbps USB4. Cooling uses a vapour chamber with three heatpipes and three fans, which is what makes the 120W Performance mode usable.
Who This Is For, and the Honest Caveats
Buy this if you are committed to 70B-class work today, you understand that 128GB of LPDDR5X is a large fixed commitment, and you will configure the BIOS properly before you judge the performance. The VRAM re-scaling control is the feature no other 128GB box in this roundup matches as clearly.
Be honest about the review base, though. Thirty-six ratings is the thinnest evidence here, and the warranty is one year, which is short for a machine at this level. It is also the largest box in the roundup at 7.59 by 7.28 by 3.03 inches and 5.5 pounds, so it is a small desktop rather than a palm-sized one. Memory is soldered, and there is a slight fan ringing audible in a very quiet room.
What Specs Actually Matter for Local AI
Most buying guides for local AI lead with processor benchmarks. For language model inference, that is the wrong first question. The ordering below is the one I use, and it is the ordering community advice in homelab forums converges on: unless your primary goal is local AI, put the money into memory and storage before spending it on a dedicated GPU, but once local AI is the primary goal, memory capacity becomes the limiting factor.
1. Usable Memory Capacity Comes First
Capacity decides whether a model loads at all, and the number that matters is the memory the GPU can address, not the number on the box. On a discrete card that is VRAM. On an integrated GPU it is the share of system memory the firmware hands over, which is why the BIOS step matters so much on unified-memory designs.
Apply the capacity math from earlier in this article to the largest model you actually want to run, then buy at least 25 percent more than it needs. Context length and KV cache growth will eat into whatever margin you skip.
2. Memory Bandwidth Sets the Speed Ceiling
Generating a token means reading the model weights again, so throughput is bounded by how fast memory can be read. This is why LPDDR5X-8000 in a unified design can out-perform a slower DDR5 platform with more capacity, and why DDR5-5600 is preferable to DDR5-4800 when the choice is presented to you.
It is also why adding a discrete GPU is the most effective upgrade available. True VRAM on a card with dedicated memory bandwidth is not the same as borrowing system RAM, and the gap is large enough that homelab veterans regularly advise it once you outgrow the iGPU path.
3. Upgradeability Decides Whether You Buy Twice
Soldered memory is a one-shot decision. Four of the ten machines here ship with LPDDR5 that cannot be changed, and for three of those the capacity is low enough that you will feel the ceiling within a year. Look for dual SO-DIMM slots and a stated maximum, and treat a machine with removable memory as a better long-term buy even at a higher entry cost.
Storage deserves the same attention. Model libraries grow quickly, and dual or triple M.2 slots plus a large drive is cheaper than repeatedly replacing a single small SSD. The three-slot machines here support totals up to 12TB.
4. eGPU Headroom Is Your Exit Ramp
OCuLink gives a direct PCIe x4 lane and is meaningfully faster for an external GPU than routing over USB4 or Thunderbolt. Four machines here include an OCuLink port, and two implement it by occupying an M.2 slot, which is a real trade-off to check before you plan your storage layout.
Note that adding a discrete card to a unified-memory machine is a genuinely debated topic in the community, with owners reporting everything from roughly doubled throughput to giving up on the idea. Treat it as an experiment on a specific combination rather than a guaranteed upgrade path.
5. NPU TOPS Is the Least Important Number
Marketing leads with NPU TOPS constantly, and it is the number I would ignore first. Discussion in mini PC community threads about AI PC branding is largely sceptical for exactly this reason: the dedicated NPU does very little for language model generation today, and the CPU and GPU are doing the work regardless.
It does not mean the NPU is useless. It means a 50 TOPS XDNA 2 NPU is not a reason to pick one machine over another. Rank by memory capacity, then memory speed, then upgrade slots, then ports, and treat TOPS as a tiebreaker.
When a Mini PC Is the Wrong Answer
A mini PC is the right call for 8B to 32B models, for transcription and image generation workloads, for private document Q and A, and for homelab nodes running alongside other services. It is the wrong call when you need a dedicated GPU with 24GB or more of true VRAM, when you need multi-GPU expansion, or when you want the highest tokens per second per pound of cash.
For those cases, our desktop workstation picks for local AI and graphics card roundup cover the dedicated route, and our laptop guide for local AI models covers the portable option. If you want a mini PC specifically for games rather than models, the best mini gaming PCs roundup is the right read.
One timing note for 2026: memory and SSD prices rose sharply in recent years, which is the single biggest reason a 128GB machine costs what it costs. Buying expandable memory and adding it later is a legitimate strategy, and it is why we rank the VTA-439 and EVO-T1 so highly despite higher entry costs.
Frequently Asked Questions
What is the best computer for local AI generation?
The best mini PC for local AI models is the GEEKOM IT13 MAX 2026 for general use, chosen for its 16-core Core Ultra 9 185H, quiet sustained thermals and dual 2.5GbE. The deciding criterion is usable GPU-addressable memory rather than NPU TOPS: 64GB of upgradeable DDR5 covers 14B to 32B models, and only 128GB unified-memory designs such as the GMKtec EVO-X2 reach 70B-class work.
Are mini PCs good for AI?
Yes, with clear limits. Mini PCs are excellent for 7B, 8B, 14B and 32B models at 4-bit and 8-bit quantization, for speech transcription, for private document Q and A, and for always-on homelab inference nodes running at 35W to 65W. They are constrained past the 70B class unless you buy a unified-memory design with 128GB, and generation speed is bandwidth-limited on integrated graphics.
What is the best mini PC processor for AI development?
Ranked for local AI, the Ryzen AI Max+ 395 comes first because its Radeon 8060S can address a very large slice of a 128GB unified pool. Next come the Ryzen AI 9 HX 370 and HX 470 class and the Intel Core Ultra 9 185H and 285H, which pair 12 to 16 CPU cores with fast integrated graphics and upgradeable DDR5. Third are Core Ultra 5 and Ryzen 7 parts for models in the 7B to 14B range. NPU TOPS figures rank last and should not drive the decision.
What specs do you need to run AI locally?
Prioritise in this order: usable memory capacity, memory bandwidth, upgradeable SODIMM slots and multiple M.2 slots, then eGPU headroom via OCuLink. Size memory with the rule that memory equals parameters multiplied by bits per weight divided by eight, plus about 20 percent overhead. That means 8GB for a 7B model at 4-bit, 32GB for a 32B model at 4-bit, and 64GB minimum for a 70B model at 4-bit.
How much RAM do I need for a local LLM?
At 4-bit quantization, budget about 5GB for a 7B to 8B model, roughly 11GB for a 14B model, near 20GB for a 32B model, and about 42GB for a 70B model once the 20 percent overhead is added. Higher precision scales directly: a 70B model at 8-bit needs roughly 70GB, and at full 16-bit precision about 140GB. Longer context windows add further KV cache memory on top.
Do I need a NPU for local AI?
No, not for language model generation today. The dedicated NPU does very little to accelerate LLM inference, and the CPU and GPU do the work. Community discussion in mini PC forums about AI PC branding is largely sceptical for the same reason. Rank a machine by memory capacity, memory bandwidth, upgradeable memory and storage slots, and treat the TOPS figure as a tiebreaker rather than a deciding spec.
Which Mini PC Should You Buy for Local AI?
If you want one machine that handles everything from 8B models to 32B models, quietly, without any assembly, buy the GEEKOM IT13 MAX 2026. It has the deepest review history in this roundup, the most reliable sustained thermals, and the most ports relative to its size. Just know that its 24GB of memory is the ceiling you accept.
If you want to grow into larger models rather than settle, buy the GMKtec EVO-T1 for 64GB of removable DDR5, or the BOSGAME VTA-439 if you want memory you can keep adding toward 256GB. For Linux-first work with an external GPU later, the MINISFORUM AI X1 Pro-370 is the pick, and for 32GB with the most storage and expansion room per pound, the GMKtec K15.
For 70B-class models with no discrete card, the answer is 128GB of unified memory, and the GMKtec EVO-X2 leads there because its BIOS exposes more VRAM allocation control than any other box here. If serving models to other machines matters more than raw speed, the Beelink SER10 MAX gets you 10GbE. Pick one, set the BIOS properly before your first model run, and you will get far more out of any of these than you would from a faster machine with memory you cannot replace.

